
Overview
AREX-2 is a 27-billion-parameter long-horizon agent model from the Beijing Academy of Artificial Intelligence (BAAI), published on Hugging Face on September 29, 2026 under the Apache 2.0 license together with the paper "AREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks". It is a dense, Qwen3.8-compatible multimodal model built on Qwen3.8-27B, with a 262,144-token context window.
The model is trained to turn extra test-time rounds into a better answer: it proposes a solution, measures it, reflects on the feedback and revises. BAAI's paper treats this as two connected abilities — reflection, which reads scores, logs, errors and timings to decide what to change, and long-horizon execution, which keeps the improvement loop useful as the task budget grows.
BAAI trained AREX-2 on machine-learning-engineering and algorithmic-programming tasks where progress can be checked directly, together with the existing AREX deep-research data. According to the model card, the self-improvement behaviour learned on coding and ML tasks transfers to deep research without adding new search trajectories.
In BAAI's model card AREX-2 scores 70.7 on the 188-task Frontier-CS Agent Track and 81.8 on MLE-Lite (Any Medal, averaged over three seeds), and 84.0 on BrowseComp, 52.6 on HLE (text-only subset), 92.2 on GAIA and 93.8 on DeepSearchQA. The same tables list GPT-5.6 Sol at 76.4 on Frontier-CS and Kimi-K3 at 91.2 on BrowseComp, so the 27B model does not lead every column.
Alongside the weights, BAAI publishes the evaluation runners and dataset definitions for the six reported tracks in the VectorSpaceLab/AREX-2 GitHub repository. The model card positions AREX-2 for research on long-horizon agents, iterative problem solving, ML engineering, algorithmic coding and tool-augmented deep research.
| Released | 2026-09-29 |
|---|---|
| License | Apache-2.0 |
| Weights | Open weights |
| Parameters | 27B (dense) |
| Context | 262,144 tokens |
| Architecture | Dense Qwen3.8-compatible multimodal model, fine-tuned from Qwen3.8-27B |
| Modalities | Text, Vision |
| Status | Open weights on Hugging Face (Apache 2.0), BF16 safetensors, with an accompanying arXiv paper and evaluation code on GitHub. |
Benchmarks
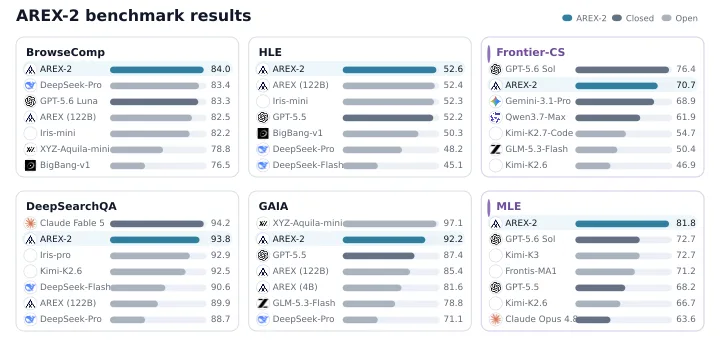
AREX-2 against frontier and large open models, transcribed from BAAI's model card. HLE values marked * use the full HLE set; unmarked values use the text-only subset. A dash means the card gives no score.
| Benchmark | AREX-2 (27B) | GPT-5.6 Sol | Claude Opus 4.8 | GPT-5.5 | Gemini-3.1-Pro | Kimi-K3 (2.8T) | DeepSeek-V4-Pro (1.6T) |
|---|---|---|---|---|---|---|---|
| Frontier-CS (Agent Track) | 70.7 | 76.4 | 74.5 | 72.1 | 68.9 | — | 44.7 |
| MLE-Lite (Any Medal) | 81.8 | 72.7 | 63.6 | 68.2 | — | 72.7 | 54.5 |
| BrowseComp | 84 | 90.4 | 84.3 | 84.4 | 85.9 | 91.2 | 83.4 |
| HLE | 52.6 | 58.0* | 57.9* | 52.2* | 51.4* | 56.0* | 48.2 |
| GAIA | 92.2 | — | — | 87.4 | 80.6 | — | 71.1 |
| DeepSearchQA | 93.8 | — | 93.1 | — | 93.3 | 95 | 88.7 |
This model's scores
- DeepSearchQA93.8%
- GAIA92.2%
- BrowseComp84%
- MLE-Lite (Any Medal)81.8%
- Frontier-CS (Agent Track)70.7
- HLE (text-only)52.6%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- Trained to refine its own solution over many rounds, reading scores, logs, errors and timings to decide what to change
- 81.8 on MLE-Lite in BAAI's table, above every closed and open model listed there
- 84.0 on BrowseComp, 92.2 on GAIA and 93.8 on DeepSearchQA at 27B parameters
- Apache 2.0 weights with a 262,144-token context and open evaluation code
Best for
- Reach for it for self-hosted agent loops that iterate on a measurable target — ML experiments, algorithmic coding against a judge, or benchmarked optimisation.
- Reach for it for tool-augmented deep research where a 27B open model fits your hardware.
- Look elsewhere for a general chat assistant: BAAI frames AREX-2 as a research model for long-horizon agents, not a tuned consumer assistant.
FAQ
What is AREX-2?
AREX-2 is a 27B-parameter open-weight agent model from the Beijing Academy of Artificial Intelligence (BAAI), published on Hugging Face on September 29, 2026. It is fine-tuned from Qwen3.8-27B to improve a solution over many test-time rounds: propose, measure, reflect and revise.
What license is AREX-2 released under?
Apache 2.0. BAAI's model card also asks users to follow the terms of the Qwen base model and of any downstream data or tools.
How does AREX-2 score on agent benchmarks?
In BAAI's model card it scores 70.7 on Frontier-CS (Agent Track), 81.8 on MLE-Lite, 84.0 on BrowseComp, 52.6 on HLE (text-only subset), 92.2 on GAIA and 93.8 on DeepSearchQA. In the same tables GPT-5.6 Sol leads Frontier-CS at 76.4 and Kimi-K3 leads BrowseComp at 91.2.
How do I run AREX-2?
The model card loads it with Hugging Face Transformers (AutoModelForMultimodalLM and AutoProcessor with the model id BAAI/AREX-2, in bfloat16) and asks for a recent Transformers release with Qwen3.8 support. The weights are BF16 safetensors.