
Overview
Edge0-145B is an open-weight language model from Edge0, announced on November 12, 2026 together with a smaller Edge0-120B. It is a 145-billion-parameter latent Mixture-of-Experts model derived from Alibaba's Qwen3.8-Flash-Next and, per its model card, trained natively at 4 bits. Only about 10.12B parameters are active per token, and Edge0 built it to run on one consumer GPU instead of a data-center cluster.
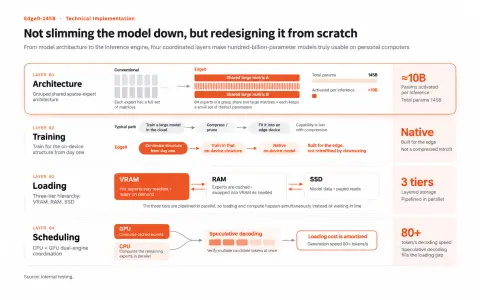
The model card describes 48 layers with hybrid attention (full attention every fourth layer plus a sparse indexer), 512 experts per layer with 10 routed and 1 shared expert active per token, and a 256K context with an int8 KV cache. Groups of 64 experts share two large matrices while each expert keeps a small set of its own parameters, so the experts are small enough to be kept on the GPU, cached in system memory or swapped in on demand. Edge0's launch post puts the expert library at about 40 GB of system memory and about 48 GB of vocabulary data on the SSD, read as needed, with a multi-token-prediction head driving speculative decoding.
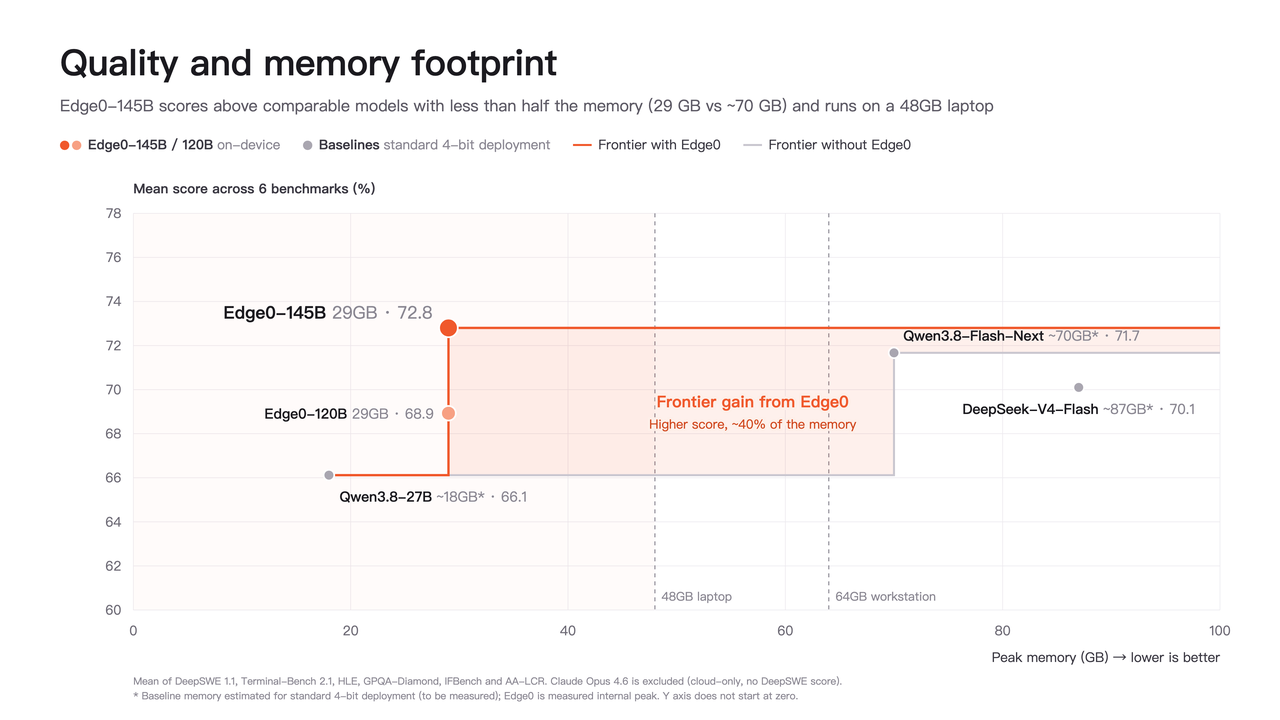
In Edge0's own evaluations the model scores 86.52 on Terminal-Bench 2.1 and 64.6 on DeepSWE 1.1, ahead of Qwen3.8-Flash-Next (83.3 and 58.7) and DeepSeek-V4-Flash-0731 (82.7 and 54.4), with a 72.8 mean across six benchmarks at 29 GB of measured peak memory. Qwen3.8-Flash-Next scores higher on HLE and GPQA-Diamond in the same table. Edge0 says the full evaluation setup is being released with its technical report.
The weights ship in Q3_K and NVFP4 builds and run on edge0-strata, the engine behind the Apache-2.0 edge0-infer command, which serves an OpenAI-compatible endpoint. The Edge0 README lists Linux and Windows with an NVIDIA GPU and CUDA 13 for the 145B and 120B models; its Apple M2 Ultra speed figures are marked as a Metal measurement, not macOS availability.
| Released | 2026-11-12 |
|---|---|
| License | Edge0 Community Model License 1.0 (Qwen Community License 1.0 also applies) |
| Weights | Open weights |
| Parameters | 145B total · 10.12B active per token |
| Context | 256K tokens |
| Architecture | Latent sparse Mixture-of-Experts: 48 layers, 512 experts per layer, 10 routed + 1 shared active per token, hybrid attention |
| Modalities | Text |
| Status | Open weights on Hugging Face in Q3_K and NVFP4 builds, released alongside a smaller Edge0-120B. |
Benchmarks
Edge0-145B against open and closed models, transcribed from Edge0's launch post. Edge0, Qwen, DeepSeek and Claude scores are Edge0's internal evaluations; Flint, Muse Glimmer and Gemma 4 take Terminal-Bench 2.1 and IFBench from the Recursive Flint evaluation and HLE, GPQA and AA-LCR from Artificial Analysis. A dash means no public score.
| Benchmark | Edge0-145B | Qwen3.8-Flash-Next | Qwen3.8-27B | DeepSeek-V4-Flash-0731 | Flint 40B | Muse Glimmer | Gemma 4 | Claude Opus 4.6 (Max) |
|---|---|---|---|---|---|---|---|---|
| DeepSWE 1.1 | 64.6 | 58.7 | 42.2 | 54.4 | — | — | — | — |
| Terminal-Bench 2.1 | 86.52 | 83.3 | 73 | 82.7 | 54.9 | 51.7 | 43.4 | 78.2 |
| HLE | 35.4 | 35.9 | 30.8 | 33.8 | — | 22 | 22.7 | 40 |
| GPQA-Diamond | 90.4 | 91.7 | 89.2 | 90.8 | — | 83.5 | 85.7 | 91.3 |
| IFBench | 80.6 | 81.3 | 79.5 | 79.2 | 89.2 | 77 | 76 | 62.5 |
| AA-LCR | 79.3 | 79.1 | 82 | 79.7 | — | 83.3 | 62 | 78 |
This model's scores
- GPQA-Diamond90.4%
- Terminal-Bench 2.186.52%
- IFBench80.6%
- AA-LCR79.3%
- DeepSWE 1.164.6%
- HLE35.4%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- 145B total parameters with about 10.12B active per token, sized for a single 24 GB NVIDIA GPU plus system RAM
- 86.52 on Terminal-Bench 2.1 and 64.6 on DeepSWE 1.1 in Edge0's internal evaluations
- 256K context, Q3_K and NVFP4 builds, and an OpenAI-compatible local server through edge0-infer
- Up to 121.2 tok/s agent decode on an RTX 5090 D 24 GB (Q3_K), per the model card
Best for
- Reach for it for local agentic coding and terminal work on a Linux or Windows machine with one NVIDIA GPU, where no prompt or code should leave the machine.
- Reach for it when a Qwen3.8-Flash-Next-class model will not fit your hardware with standard 4-bit weights.
- Look elsewhere for macOS, image input or permissive licensing: the 145B model targets NVIDIA GPUs, is text-only, and its weights are under the Edge0 Community Model License plus the Qwen license.
FAQ
What is Edge0-145B?
Edge0-145B is an open-weight 145B-parameter latent Mixture-of-Experts language model from Edge0, announced on November 12, 2026. It is derived from Qwen3.8-Flash-Next, activates about 10.12B parameters per token, supports 256K tokens of context and is designed to run on a single consumer NVIDIA GPU.
How much memory does Edge0-145B need?
Edge0 reports 29 GB of measured peak memory. The launch post also keeps an expert library of about 40 GB in system memory and reads about 48 GB of vocabulary data from the SSD on demand; on an RTX 5090 D 24 GB the model card measures the NVFP4 build at 23.25 GiB of VRAM plus 38.27 GiB of RAM.
Which platforms does Edge0-145B run on?
The Edge0 README lists Linux and Windows with an NVIDIA GPU and CUDA 13 for the 145B and 120B models, through the edge0-strata engine started by edge0-infer. macOS is not listed for these models; the Apple M2 Ultra row in the speed table is a Metal measurement, not a release platform.
What license covers Edge0-145B?
The weights are under the Edge0 Community Model License 1.0, and because the model is derived from Qwen3.8-Flash-Next the Qwen Community License 1.0 also applies. The edge0 inference framework on GitHub is Apache-2.0.