Overview
Eleven v4 Turbo is the low-latency variant of Eleven v4 that ElevenLabs launched on 28 September 2026. It is served in the ElevenLabs API as `eleven_v4_turbo`, through the Text to Dialogue WebSocket for real-time use, and in ElevenLabs' agent platform ElevenAgents. ElevenLabs aims it at support agents, AI assistants and interactive characters.
It brings the expressive range of Eleven v4 — inline audio tags for emotion and sound effects, 90+ languages, instant voice clones from 10 seconds of audio and Professional Voice Clones — to a real-time budget. The docs give a median inference latency of about 100 ms, excluding application and network latency. Text can be streamed in as an LLM generates it, with audio coming back before the sentence is finished.
In ElevenLabs' September 2026 measurement of median time from request to audible speech, with identical scripts, default settings and network latency removed, Eleven v4 Turbo over WebSocket streaming took 150 ms, against 262 ms for Cartesia Sonic 3.6, 362 ms for xAI TTS, 685 ms for Google Gemini 3.8 Flash-Lite TTS and 814 ms for OpenAI GPT-4o mini TTS.
ElevenLabs says it optimised Eleven v4 Turbo and ElevenAgents together as one system. On the API pricing page it lists at $0.04 per 1,000 characters, half the Eleven v4 rate, with a launch discount to $0.011 per 1,000 characters until 12 October 2026.
| Released | 2026-09-28 |
|---|---|
| License | Proprietary |
| Weights | API only |
| Parameters | Not disclosed |
| Modalities | Text, Audio |
| Status | Generally available |
Benchmarks
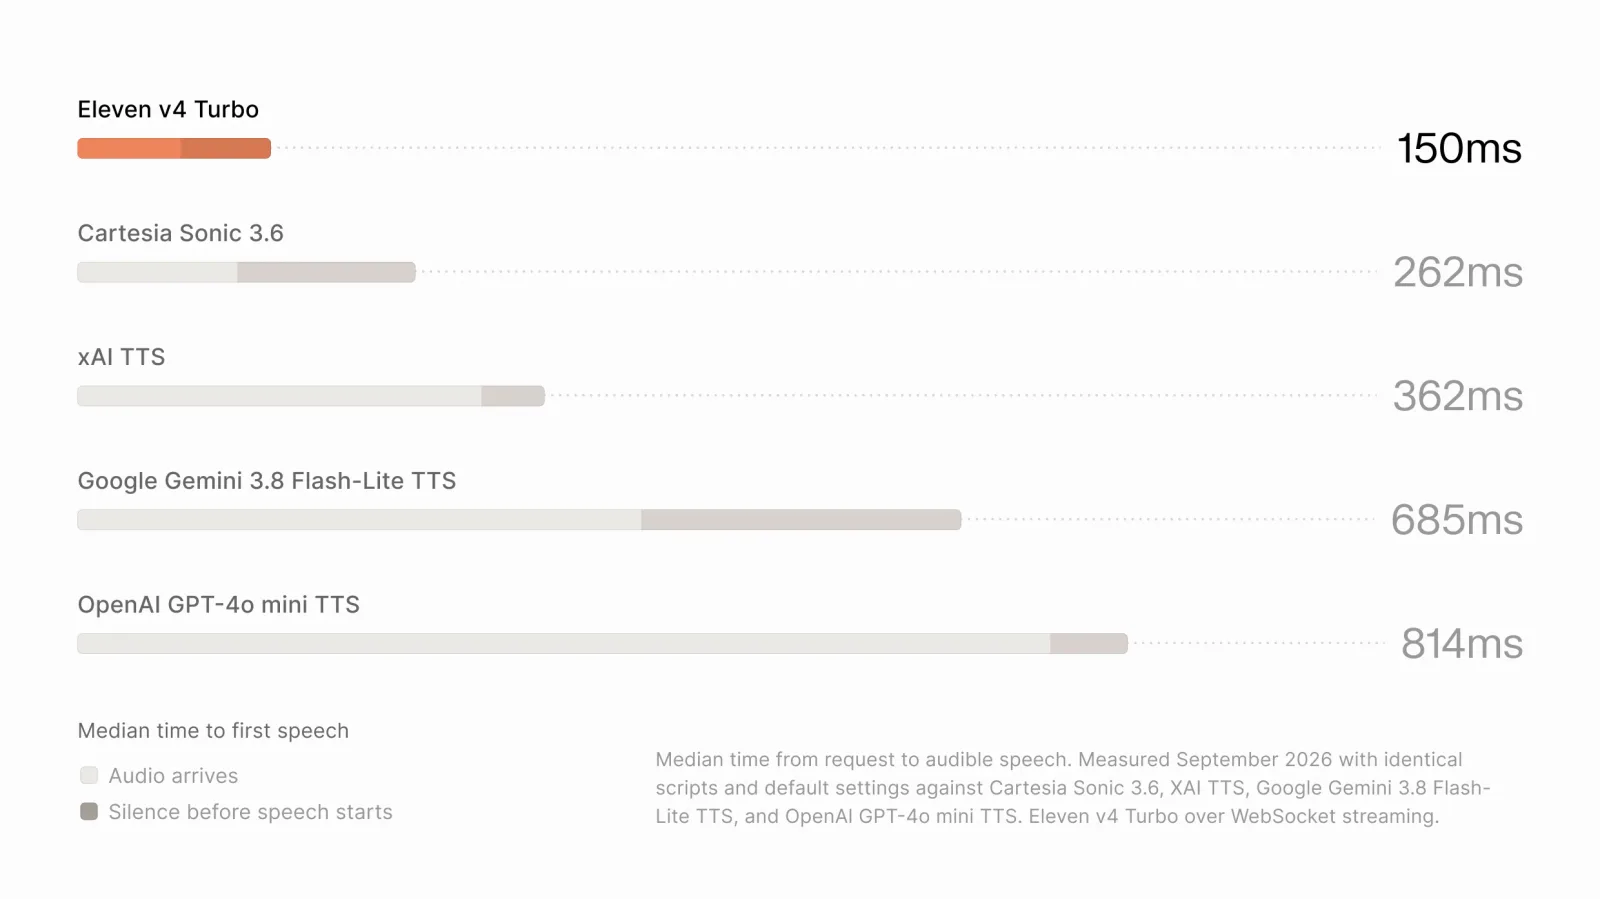
Median time from request to audible speech, as measured and published by ElevenLabs (September 2026; identical scripts, default settings, network latency removed; Eleven v4 Turbo over WebSocket streaming). Lower is better.
| Benchmark | Eleven v4 Turbo | Cartesia Sonic 3.6 | xAI TTS | Gemini 3.8 Flash-Lite TTS | OpenAI GPT-4o mini TTS |
|---|---|---|---|---|---|
| Median time to first speech | 150 ms | 262 ms | 362 ms | 685 ms | 814 ms |
Pricing
| Input | $0.04 / 1K characters |
|---|
ElevenLabs API list price for Eleven v4 Turbo text-to-speech; discounted 72% to $0.011 per 1K characters until 12 October 2026. Plans range from Free (20,000 characters included) to Business ($990/month).
Strengths
- About 100 ms median inference latency, excluding application and network latency
- 150 ms median time to first speech in ElevenLabs' September 2026 test, against 262–814 ms for Cartesia Sonic 3.6, xAI TTS, Gemini 3.8 Flash-Lite TTS and GPT-4o mini TTS
- The expressive range and audio tags of Eleven v4 at conversational speed
- 90+ languages and Professional Voice Clones that work identically across v4 and v4 Turbo
- $0.04 per 1,000 characters list price, half of Eleven v4
Best for
- Reach for it for customer-support and sales voice agents that need to answer without an audible pause
- Reach for it for AI assistants and interactive game characters that stream LLM text into speech
- Reach for it to keep one brand voice consistent across every turn of a call in any of its 90+ languages
- Reach for Eleven v4 instead for produced audio such as audiobooks or dubbing, where quality matters more than latency
How to access

| Provider | Model ID |
|---|---|
| ElevenLabs API ↗ | eleven_v4_turbo |
Eleven (text-to-speech) — every version
The full lineage of the Eleven (text-to-speech) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Eleven v4current | 2026-09-28 | — | Proprietary |
| Eleven v4 Turbo | 2026-09-28 | — | Proprietary |
FAQ
What is Eleven v4 Turbo?
Eleven v4 Turbo is ElevenLabs' low-latency text-to-speech model, launched on 28 September 2026 with Eleven v4. It is served in the API as eleven_v4_turbo and in ElevenAgents, and is designed for voice agents and other real-time use.
How fast is it?
ElevenLabs' docs give a median inference latency of about 100 ms, excluding application and network latency. In ElevenLabs' September 2026 test the median time to first audible speech was 150 ms over WebSocket streaming, against 262 ms for Cartesia Sonic 3.6 and 814 ms for OpenAI GPT-4o mini TTS.
Does it sound worse than Eleven v4?
ElevenLabs says both models share the same expressive range and both support Professional Voice Clones; Eleven v4 is tuned for produced content where quality matters most, and Turbo is tuned for latency.
What does it cost?
The ElevenLabs API pricing page lists $0.04 per 1,000 characters, discounted to $0.011 until 12 October 2026 — half the Eleven v4 rate.