
Overview
Endeavor 1.1 is a frontier-class generalist model from Flower Labs, the company behind the Flower open-source framework for federated AI. Flower released it on November 3, 2026 as its third model of the year, after the 7B Lizzy model in April and Endeavor 1.0 on September 1. Flower describes 1.1 as stronger at reasoning for demanding agent work than 1.0, and it is the first Endeavor release to accept images alongside text.
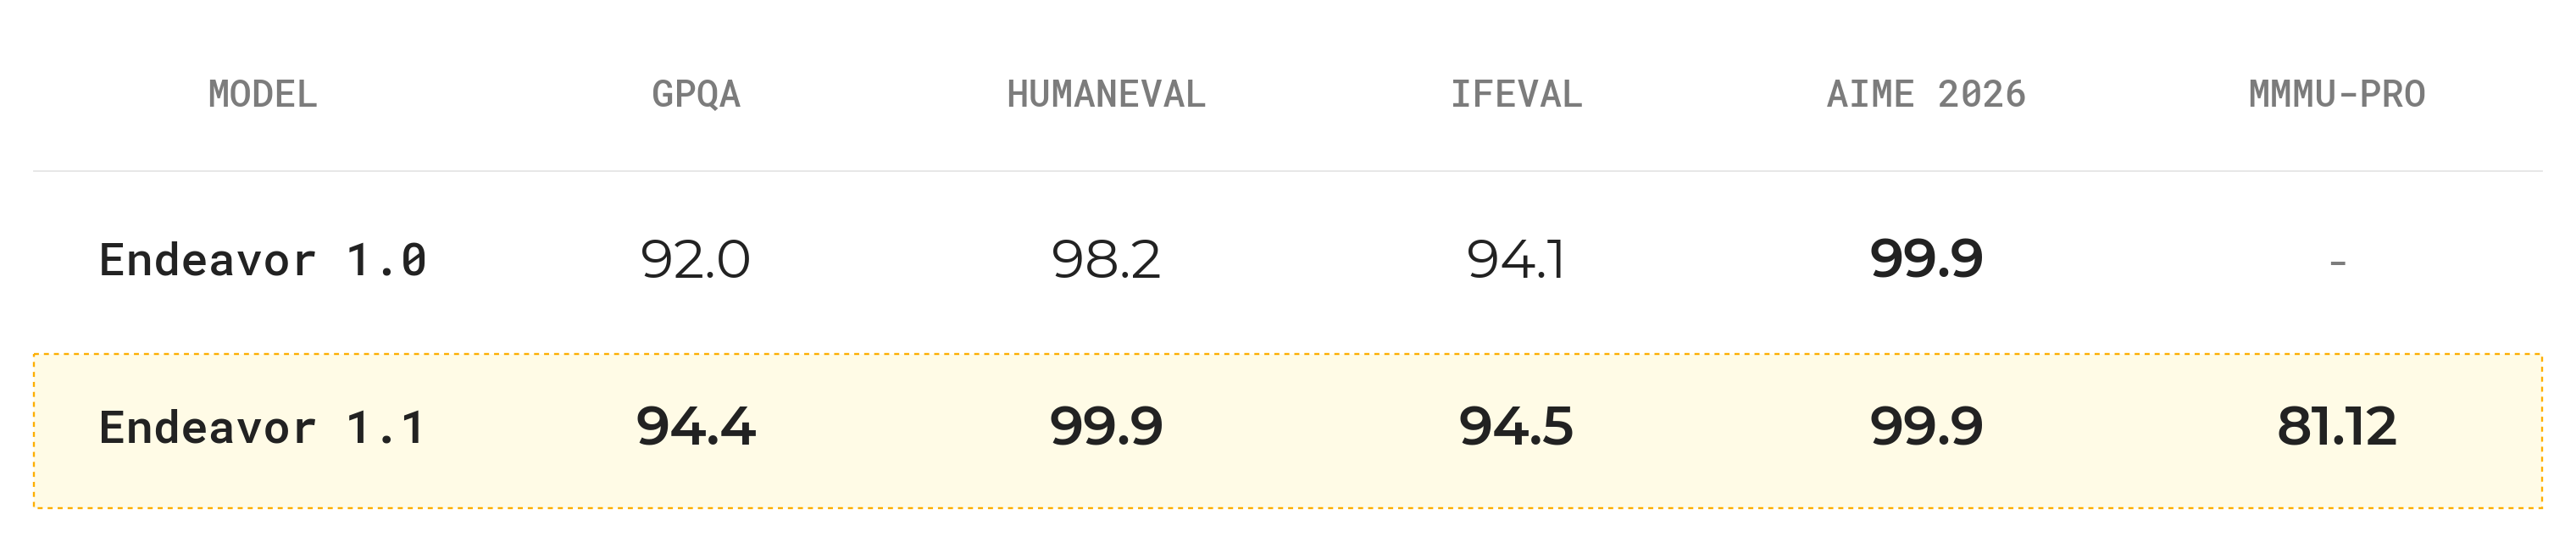
On Flower's own evaluation, Endeavor 1.1 scores 94.4 on GPQA, 99.9 on AIME 2026, 99.9 on HumanEval, 94.5 on IFEval and 81.12 on MMMU-Pro. Flower's intelligence composite, the equal-weighted mean of GPQA, AIME 2026, HumanEval and IFEval, puts it at 97.18, against 96.25 for GPT-5.6 Sol, 95.30 for Claude Fable 5, 94.83 for Kimi K3 and 92.28 for Nemotron 3 Ultra in the same comparison. GPT-5.6 Sol leads on IFEval (95.9) and MMMU-Pro (83.0). Against Endeavor 1.0, GPQA rises from 92.0 to 94.4, which Flower puts at about 30% fewer errors on that test, and HumanEval from 98.2 to 99.9. These are vendor-reported figures.
The pitch is control. Endeavor can run as a service operated by Flower, in a customer's private cloud or on premises, and from 1.1 customers can choose Flower's global inference or inference on GPUs located in the European Union, with service-level agreements; Flower says UK-only inference and regional options in the Middle East, Asia and Africa are planned. Users can read the model's full thinking traces, keep the inference outputs and traces they generate, and use them to fine-tune or train their own models.
Access is by request through Flower's website. Flower does not publish weights, a parameter count, a context window or per-token prices for Endeavor 1.1 on its launch post or model page.
| Released | 2026-11-03 |
|---|---|
| License | Proprietary |
| Weights | API only |
| Modalities | Text, Vision |
| Status | Available by request (managed service or private deployment) |
Benchmarks
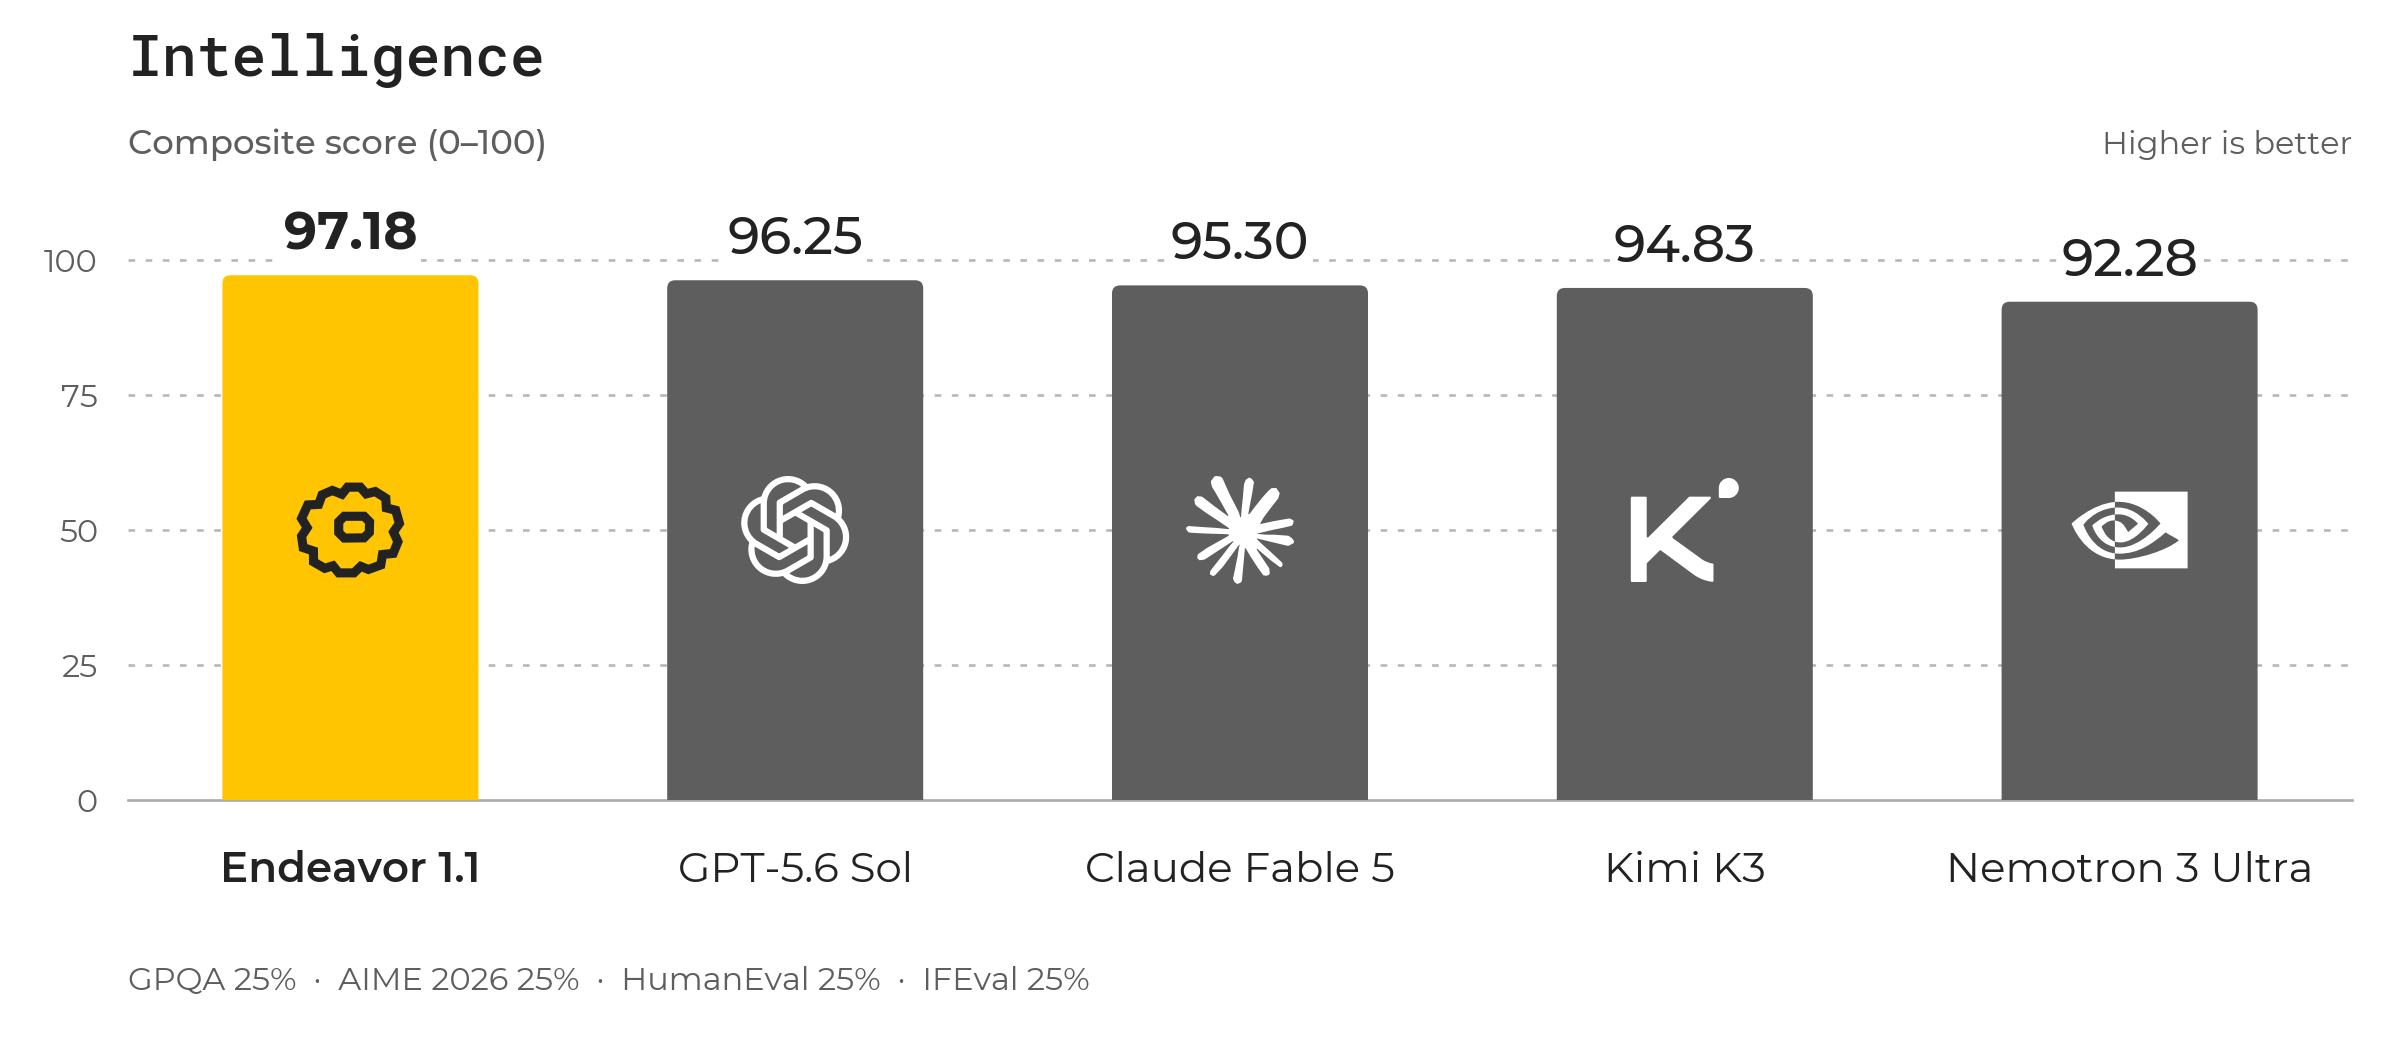
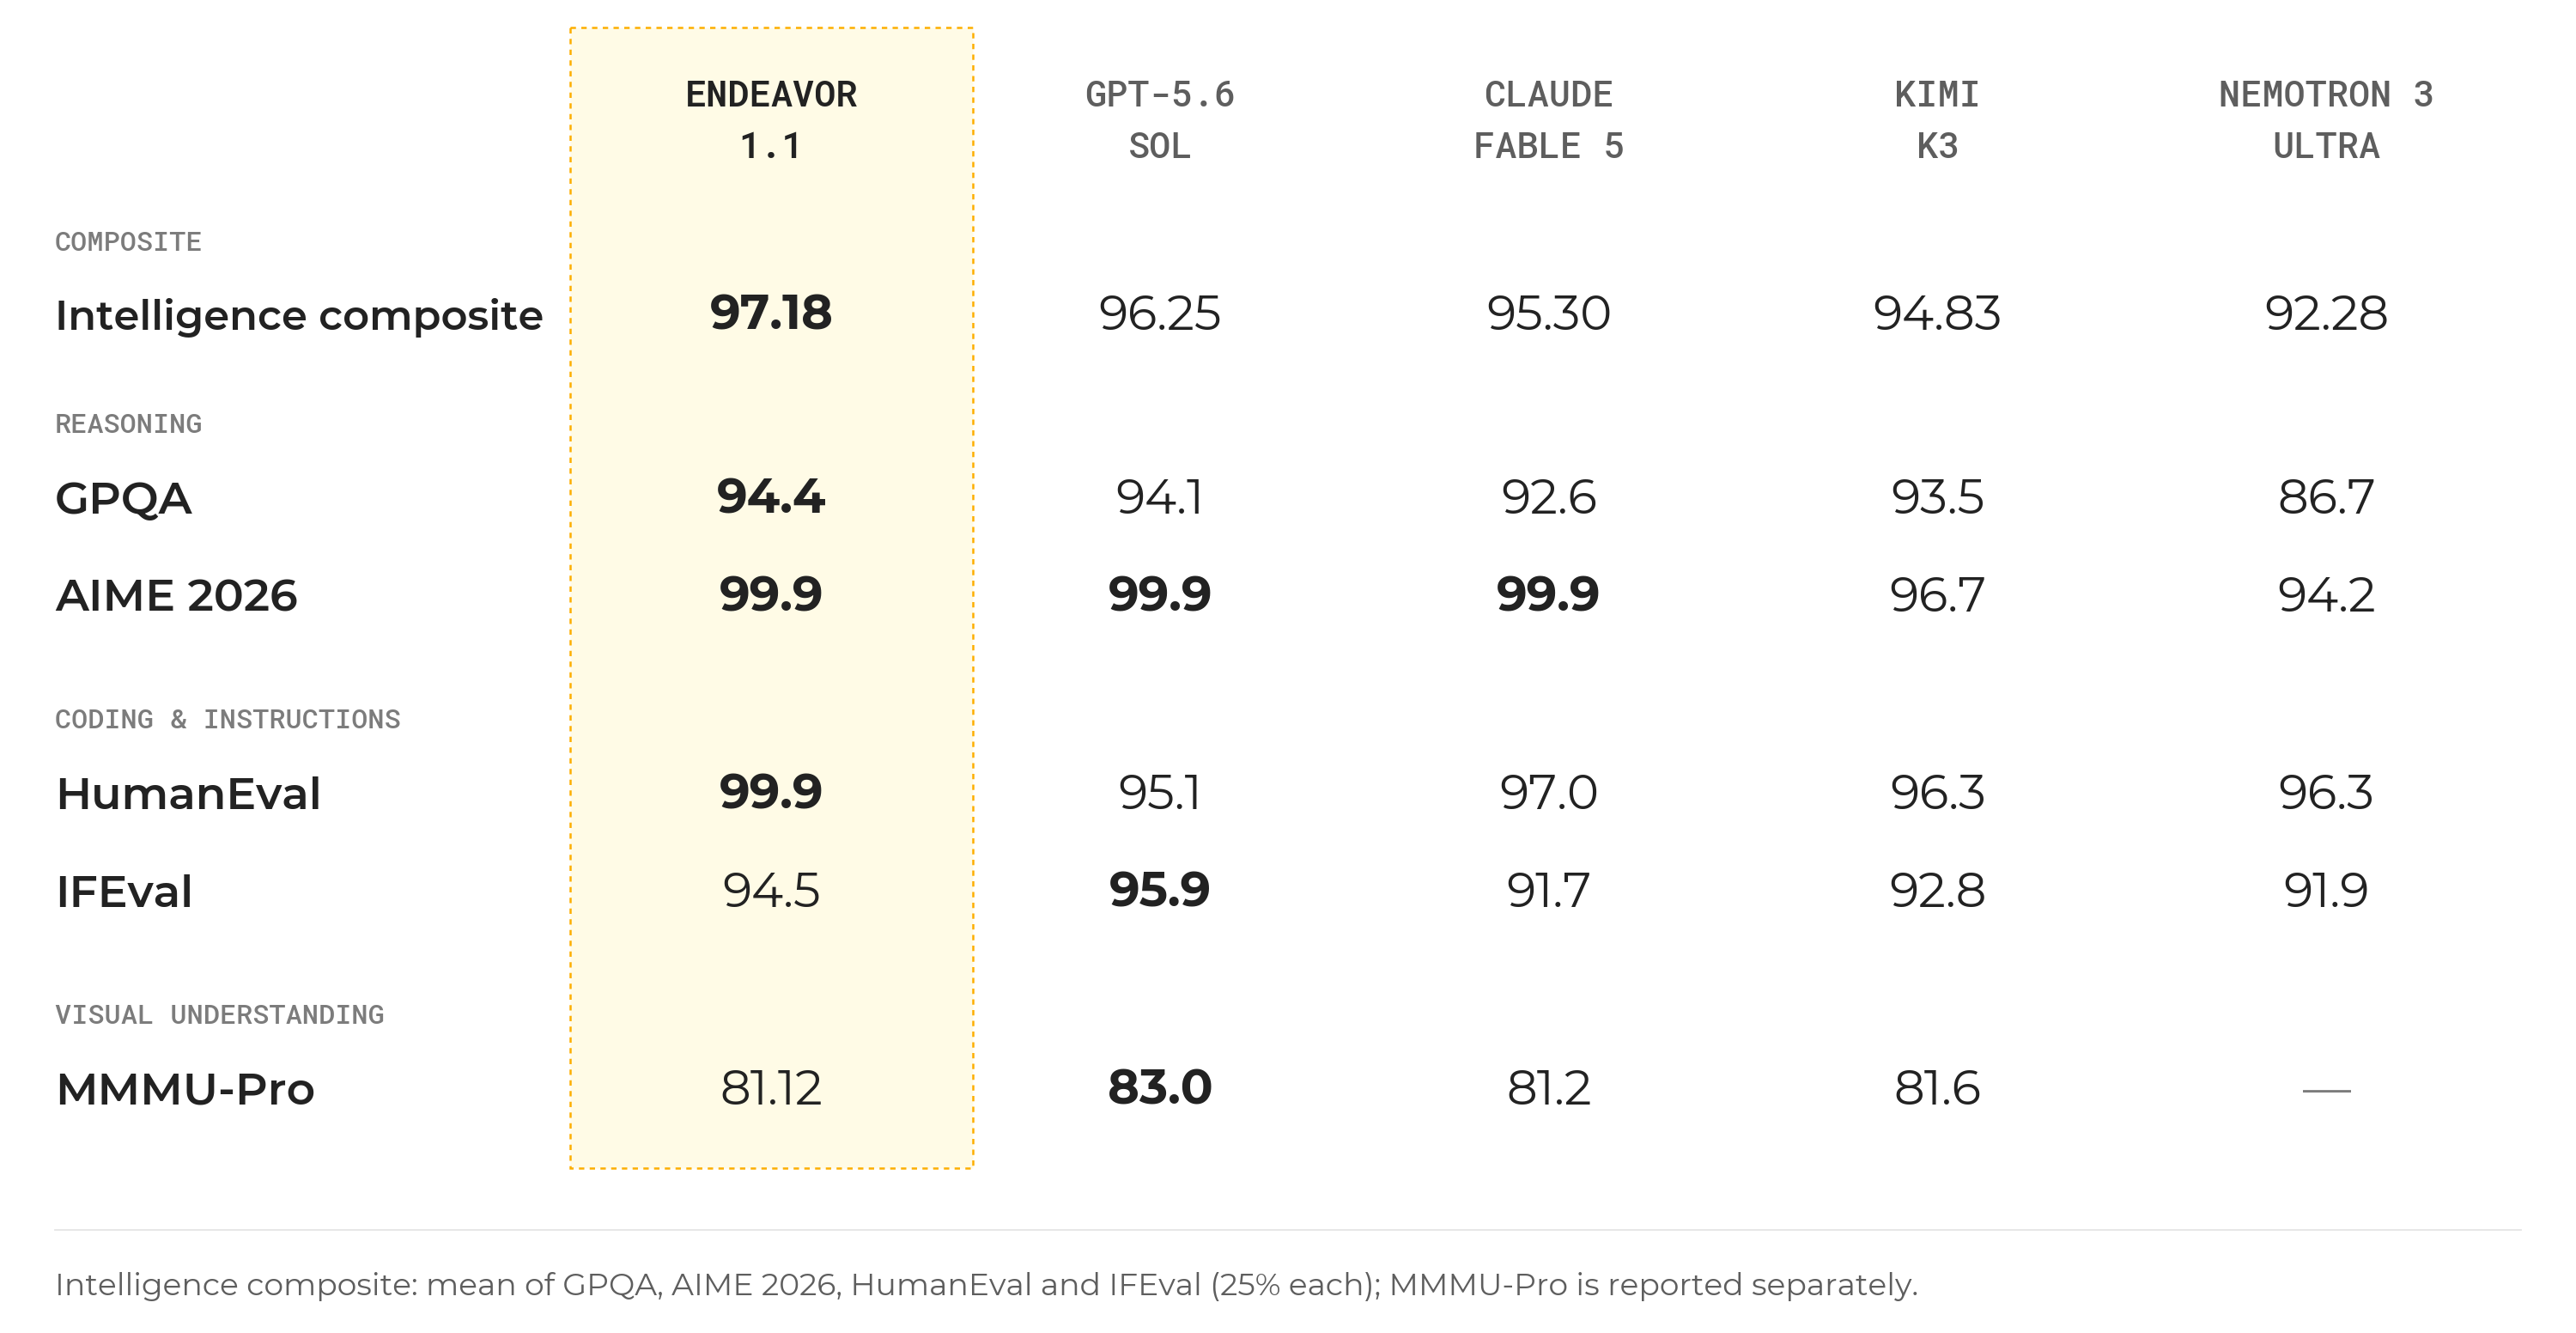
Endeavor 1.1 vs the models in Flower Labs' launch comparison
| Benchmark | Endeavor 1.1 | GPT-5.6 Sol | Claude Fable 5 | Kimi K3 | Nemotron 3 Ultra |
|---|---|---|---|---|---|
| Intelligence composite | 97.18 | 96.25 | 95.3 | 94.83 | 92.28 |
| GPQA | 94.4 | 94.1 | 92.6 | 93.5 | 86.7 |
| AIME 2026 | 99.9 | 99.9 | 99.9 | 96.7 | 94.2 |
| HumanEval | 99.9 | 95.1 | 97 | 96.3 | 96.3 |
| IFEval | 94.5 | 95.9 | 91.7 | 92.8 | 91.9 |
| MMMU-Pro | 81.12 | 83 | 81.2 | 81.6 | — |
This model's scores
- Intelligence composite (Flower: GPQA, AIME 2026, HumanEval, IFEval)97.18
- GPQA94.4%
- AIME 202699.9%
- HumanEval99.9%
- IFEval94.5%
- MMMU-Pro81.12%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- 97.18 on Flower's intelligence composite (GPQA, AIME 2026, HumanEval, IFEval), the top score in its launch comparison
- 99.9 on HumanEval and 99.9 on AIME 2026 in Flower's evaluation
- Image input alongside text, with 81.12 on MMMU-Pro
- Inference on GPUs located in the EU, alongside a global offering, with SLAs
- Deployable on premises or in a private cloud, so the model and workloads stay in your environment
- Readable thinking traces, and the right to keep outputs and traces and train your own models on them
Best for
- Reach for Endeavor 1.1 when you need a frontier-class model that must run on your own infrastructure or private cloud.
- Reach for it when inference has to stay on GPUs inside the European Union.
- Reach for it to collect reasoning traces and outputs from agent work and distil them into smaller in-house specialist models.
- Look elsewhere when you need self-service API sign-up or published per-token prices: access is by request.
Endeavor — every version
The full lineage of the Endeavor line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Endeavor 1.1current | 2026-11-03 | — | Proprietary |
| Endeavor 1.0 | 2026-09-01 | — | Proprietary |
FAQ
What is Endeavor 1.1?
A frontier-class generalist model from Flower Labs, released November 3, 2026. It follows Endeavor 1.0 with stronger reasoning, image input and the option of inference on GPUs located in the EU.
How does it compare with GPT-5.6 Sol and Claude Fable 5?
In Flower's own comparison it scores 97.18 on an equal-weighted composite of GPQA, AIME 2026, HumanEval and IFEval, against 96.25 for GPT-5.6 Sol and 95.30 for Claude Fable 5. GPT-5.6 Sol scores higher on IFEval (95.9 vs 94.5) and MMMU-Pro (83.0 vs 81.12).
What changed from Endeavor 1.0?
GPQA rose from 92.0 to 94.4 and HumanEval from 98.2 to 99.9, image input was added alongside text, and customers can now choose EU-located inference as well as Flower's global offering.
How do I get access?
Request access on Flower's website. Endeavor 1.1 runs as a Flower-managed service, in a private cloud or on premises; Flower publishes no self-service pricing.
Are the weights open?
No. Flower does not publish Endeavor's weights; on-premises deployment is arranged with Flower.