Overview
Fish Audio Drama 3 is the text-to-speech model Fish Audio released on 13 October 2026, with open weights on Hugging Face (fishaudio/drama-3), code in the fish-speech GitHub repository and an arXiv technical report. Fish Audio describes it as its most emotive model, built to turn a script with stage directions into a performance: one text can hold up to 16 characters, switched with speaker tags, and bracketed directions such as a whisper, a laugh or a mid-line change of tone land where the script places them. It speaks 83 languages, and the direction can be written in any language regardless of the language of the line.
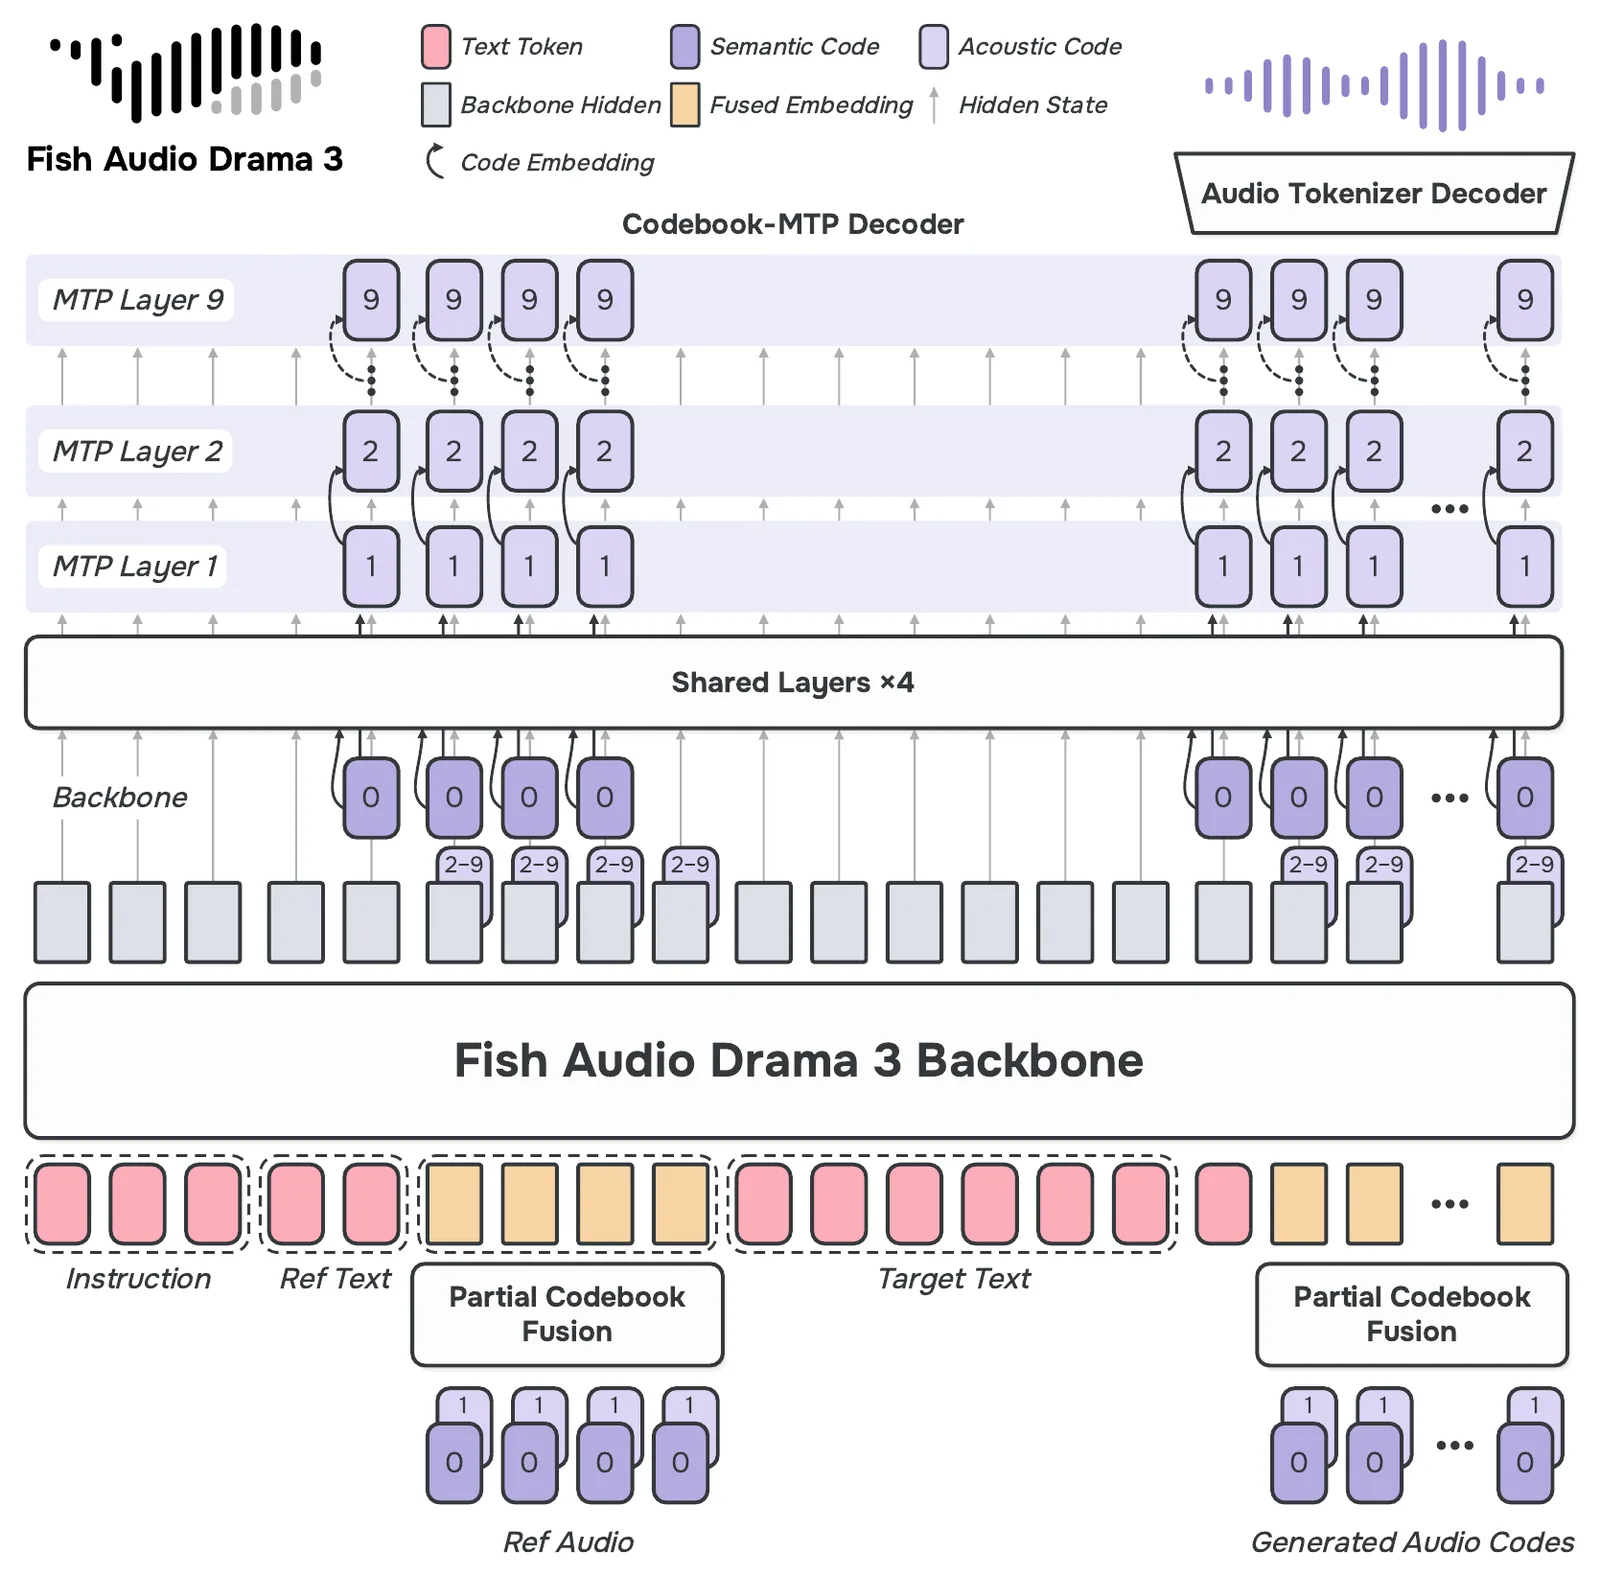
The backbone is a 35B-parameter mixture-of-experts language model that activates about 3B parameters per token (8 of 256 routed experts plus one shared expert), initialised from the language model of Qwen3.5-35B-A3B. Its 40 layers mix three Gated DeltaNet layers with one gated full-attention layer per block, so only one layer in four keeps a KV cache. A new codebook-MTP decoder replaces Fish Audio S2's per-frame fast autoregressive head and predicts the nine acoustic codebooks of each audio frame; the audio tokenizer is unchanged from S2 (44.1 kHz, 10 codebooks, about 21.5 frames per second). Training ran three pre-training stages, instruction fine-tuning and reinforcement learning against a single learned human-preference reward model instead of rule-based scores.
Fish Audio reports that on one NVIDIA H200 a single stream decodes at 271 frames per second, against 177 for Fish Audio S2, despite Drama 3 having more than seven times as many parameters. The model card lists streaming output with first audio in under 100 ms for a single stream, and the model is served through SGLang-Omni, which publishes a Drama 3 cookbook.
In Artificial Analysis' English Pronunciation Robustness test, published in Fish Audio's launch post, Drama 3 (listed as "Fish Audio Drama 3 Preview") ranked first with 93.2% of highlighted spans judged correctly pronounced by human reviewers, against 88.1% for Fish Audio S2.1 Pro. Its largest gains were on brand, place and technical names (95.9% against 87.3%) and on words whose reading depends on context (95.3% against 86.1%).
The weights are released under the Fish Audio Community License v1.0: research and non-commercial use are free, and commercial use is free for licensees with under US$500,000 in annual revenue. Larger companies, and anyone offering Drama 3 to others as a TTS, voice-cloning or inference service, need a separate license from Fish Audio, and cloning a real person's voice without consent is forbidden. On the Fish Audio API, Drama 3 is called through the same POST /v1/tts endpoint as S2.1 Pro with the model header set to drama-3, at a list price of $50 per million characters.
| Released | 2026-10-13 |
|---|---|
| License | Fish Audio Community License v1.0 |
| Weights | Open weights |
| Parameters | 35B total · ~3B active |
| Architecture | Mixture-of-Experts backbone (hybrid Gated DeltaNet + full attention) with a codebook-MTP audio decoder |
| Modalities | Text, Audio |
| Status | Generally available |
Benchmarks
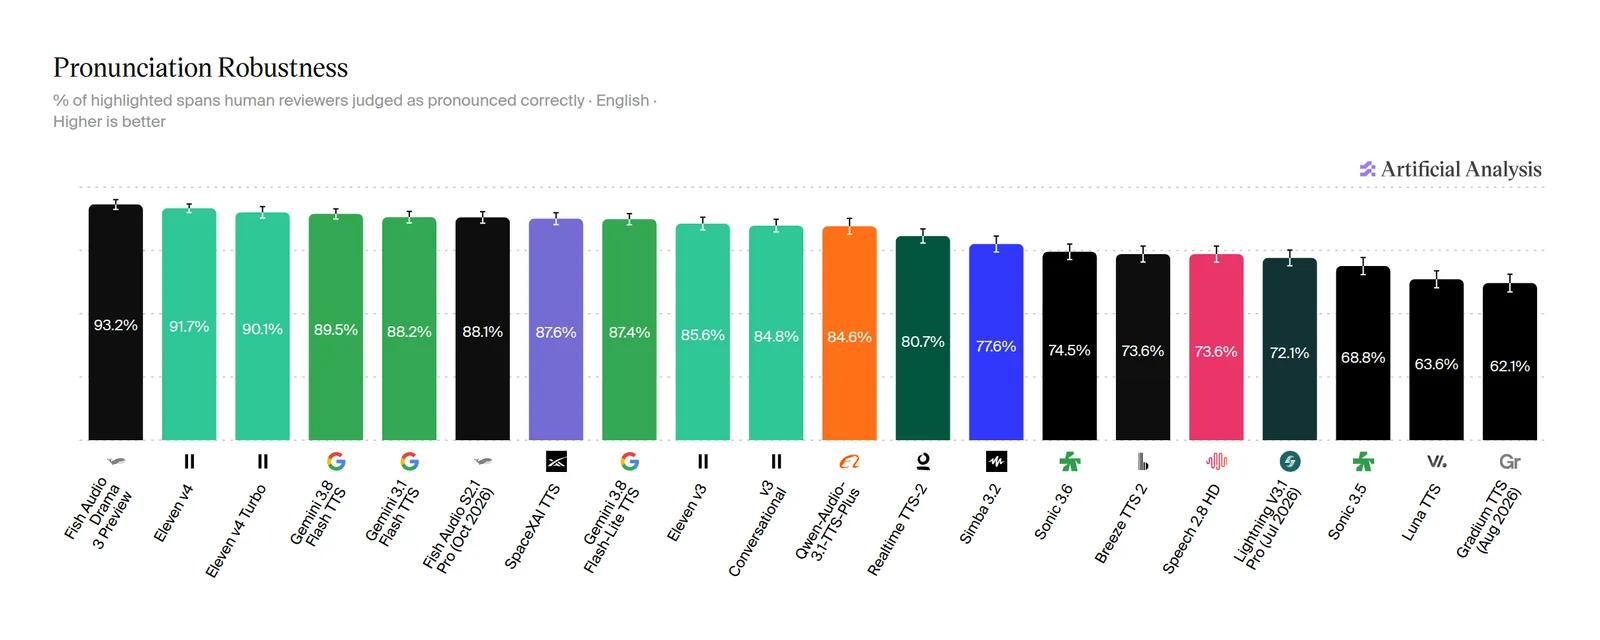
Fish Audio Drama 3 vs Fish Audio S2.1 Pro on Artificial Analysis' English Pronunciation Robustness test, as published by Fish Audio (October 2026)
| Benchmark | Fish Audio Drama 3 | Fish Audio S2.1 Pro |
|---|---|---|
| Names of brands, places, technical terms | 95.9% | 87.3% |
| Words whose reading depends on context | 95.3% | 86.1% |
| Shorthand (numbers, dates, units, notation) | 93.6% | 92.7% |
| Exact sequences (codes, paths, emails) | 86.3% | 79.4% |
| Overall | 93.2% | 88.1% |
This model's scores
- Artificial Analysis Pronunciation Robustness (English, overall)93.2%
- Pronunciation: brand, place and technical names95.9%
- Pronunciation: context-dependent words95.3%
- Pronunciation: shorthand (numbers, dates, units)93.6%
- Pronunciation: exact sequences (codes, paths, emails)86.3%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Pricing
| Input | $50 / 1M characters |
|---|
Fish Audio API list price for Drama 3; discounted 80% to $10 per 1M characters from 13 October to 12 November 2026. In the fish.audio app Drama 3 uses the same credits as S2.1 Pro.
Strengths
- Up to 16 speakers in a single text, assigned with speaker tags, for multi-character scenes
- Free-form bracketed directions and paired word-level tags such as <whisper> and <emphasis>, written in any language
- 83 languages, with phoneme input for English (CMU Arpabet), Chinese (pinyin) and Japanese (romaji)
- Ranked first in Artificial Analysis' English Pronunciation Robustness test at 93.2%, as published by Fish Audio
- Open weights: a 35B MoE with about 3B active per token, decoding 271 frames per second for a single stream on one H200
- Drop-in for S2.1 Pro API users: same endpoint, one model header
Best for
- Reach for it for audio drama, podcasts and dialogue scenes where several characters share one script
- Reach for it for character voiceovers and narration that need directed emotion — tears, anger, laughter, whispers — placed at exact points in a line
- Reach for it when you want to self-host an expressive TTS model and your use fits the Community License's research, non-commercial or under-US$500,000-revenue terms
- Reach for it for scripts with brand names, technical terms or numbers, where Fish Audio reports its strongest pronunciation results
How to access
| Provider | Model ID |
|---|---|
| Fish Audio API ↗ | drama-3 |
FAQ
What is Fish Audio Drama 3?
Fish Audio Drama 3 is an open-weight text-to-speech model Fish Audio released on 13 October 2026. It is a 35B mixture-of-experts model with about 3B parameters active per token that voices up to 16 characters in one text, follows bracketed stage directions such as whispers or laughs, and speaks 83 languages.
Can I use Fish Audio Drama 3 commercially?
The weights are under the Fish Audio Community License v1.0. Research and non-commercial use are free, and commercial use is free for licensees with under US$500,000 in annual revenue. Larger companies, or anyone offering Drama 3 to others as a TTS, voice-cloning or inference service, need a license from Fish Audio. Cloning a real person's voice without consent is forbidden.
How does Drama 3 compare with Fish Audio S2.1 Pro?
Fish Audio says Drama 3 is more emotive and follows direction more closely. On Artificial Analysis' English Pronunciation Robustness test, published by Fish Audio, Drama 3 scores 93.2% overall against 88.1% for S2.1 Pro. Fish Audio also reports 271 frames per second for a single stream on one H200, against 177 for S2.
How do I use Drama 3 through the API?
Send the existing POST /v1/tts request used for S2.1 Pro with the model header set to drama-3. Fish Audio's docs note that a missing or misspelled header falls back to s2.1-pro without an error. Multi-speaker requests pass one voice ID per speaker in reference_id and switch turns with <|speaker:N|> tags.
How much does Drama 3 cost on the Fish Audio API?
The list price is $50 per million characters. From 13 October to 12 November 2026 Fish Audio discounted it 80% to $10 per million characters. In the fish.audio app it uses the same credits as S2.1 Pro.
How do I run Drama 3 myself?
Download the weights from fishaudio/drama-3 on Hugging Face and use the code in the fish-speech GitHub repository. Fish Audio serves the model through SGLang-Omni, which publishes a Drama 3 cookbook.