
Overview
LongCat-2.5 is a native multimodal Mixture-of-Experts model from Meituan's LongCat team, built for long-horizon agentic tasks. It has 1.6 trillion total parameters with approximately 48 billion activated per token. The LongCat API Platform changelog lists it as available on November 2, 2026, following a LongCat-2.5-Preview on September 25, 2026; the weights are published on Hugging Face under the MIT license.
The model builds on LongCat-2.0 and combines visual understanding with agentic coding for complex codebase development, full-project builds, creative design and 3D tasks. Following LongCat-Next, native-resolution visual features are converted into discrete tokens and aligned with text in a shared semantic space. On the API it accepts images and videos alongside text, with a 1M-token context window and up to 256K output tokens.
Meituan's model card credits long-sequence training, large-scale agentic reinforcement learning on real-world engineering tasks, and multi-teacher learning (specialised agent, reasoning and interaction teachers distilled with full-vocabulary KL distillation and Tree Attention). It also says training and serving run on domestic AI accelerators: the expert weights and activations are quantized to W4A4 for native INT4 computation, and the published deployment guide targets NPUs through SGLang-FluentLLM.
LongCat-2.5 is a hybrid model with a thinking mode and a non-thinking mode, switched per request with enable_thinking. In Meituan's evaluation table it scores 88.4 on Terminal Bench v2.1, 91.9 on BrowseComp, 83.1 on MCP Atlas and 63.1 on HLE with tools, set against GPT-5.5, GPT-5.6-Sol, Claude Opus 4.8, Claude Opus 5, GLM-5.3, Kimi K3 and DeepSeek-V4.1-Flash. Meituan marks which competitor cells are cited from public reports; the unmarked scores, including every LongCat-2.5 figure, are in-house measurements it calls indicative only.
| Released | 2026-11-02 |
|---|---|
| License | MIT |
| Weights | Open weights |
| Parameters | 1.6T total · ~48B active |
| Context | 1M tokens (API) |
| Max output | 256K tokens (API) |
| Architecture | Mixture-of-Experts, native multimodal (discrete visual tokens), W4A4-quantized experts |
| Modalities | Text, Vision, Video |
| Status | Generally available on the LongCat API Platform (from November 2, 2026, after a LongCat-2.5-Preview on September 25, 2026). Open weights on Hugging Face under the MIT license. |
Benchmarks
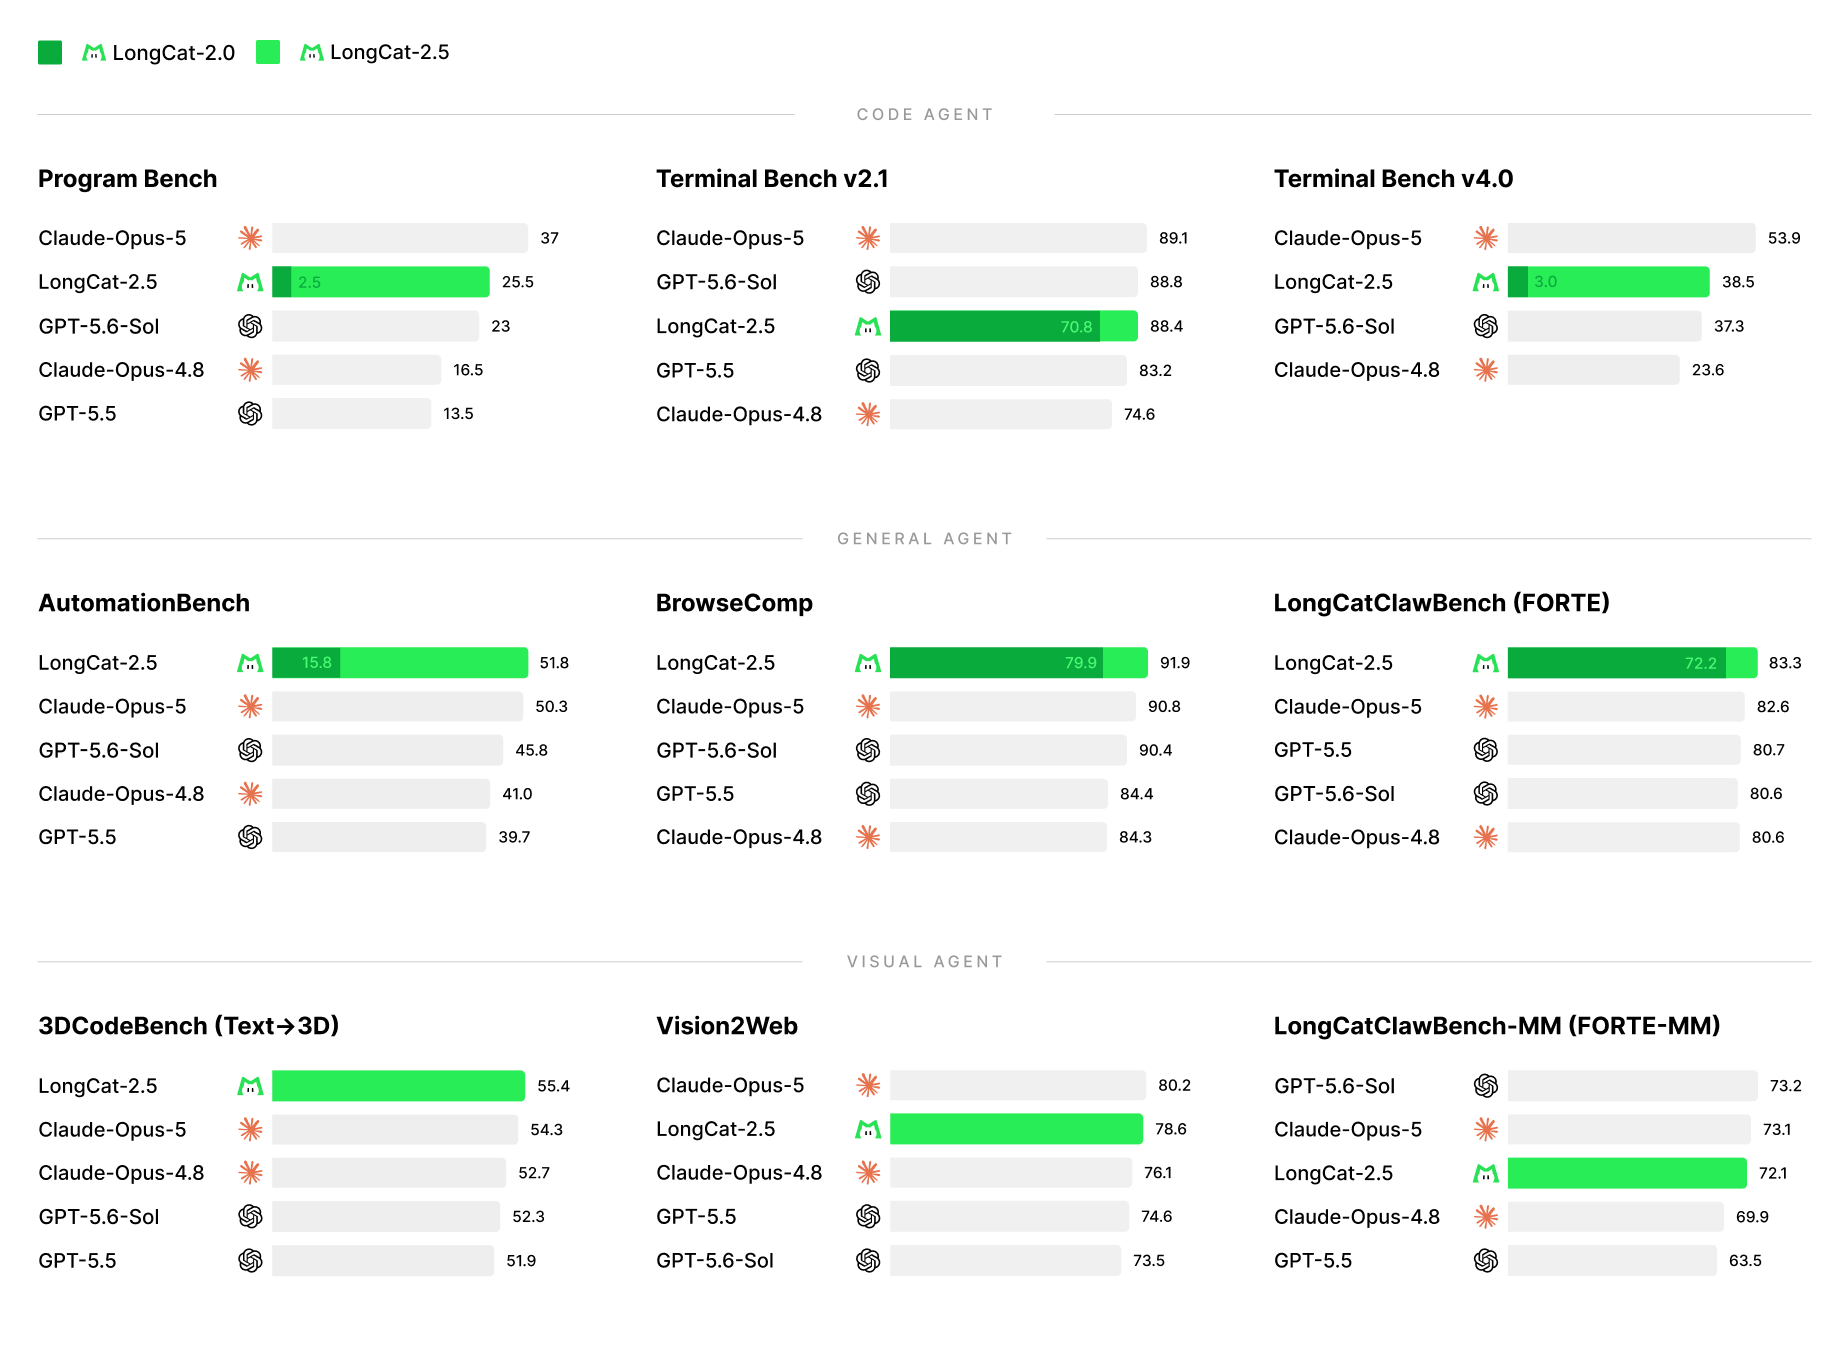
LongCat-2.5 vs LongCat-2.0 and leading models, transcribed from Meituan's model card. Meituan marks competitor cells cited from public reports; all other cells, including every LongCat-2.5 score, are its in-house measurements (indicative only). LongCat-2.5 was run in thinking mode.
| Benchmark | LongCat-2.5 | LongCat-2.0 | GPT-5.5 | GPT-5.6-Sol | Claude Opus 4.8 | Claude Opus 5 | GLM-5.3 | Kimi K3 | DeepSeek-V4.1-Flash |
|---|---|---|---|---|---|---|---|---|---|
| Terminal Bench v2.1 | 88.4 | 70.8 | 83.2 | 88.8 | 74.6 | 89.1 | 88.2 | 88.3 | 90.6 |
| Terminal Bench v4.0 | 38.5 | 3 | — | 37.3 | 23.6 | 53.9 | 41.8 | 12.6 | 31.2 |
| Program Bench (Almost Resolved) | 25.5 | 2.5 | 13.5 | 23 | 16.5 | 37 | 19 | 17.5 | 20.3 |
| DeepSWE (v1.1) | 64.6 | 9.7 | 67 | 72.7 | 59 | 68.8 | 66.9 | 67.5 | 74.2 |
| PaperBench | 82.1 | 45.2 | 80 | 83.3 | 72.9 | 79.1 | 73.7 | 77.5 | — |
| SWE Atlas - Codebase QnA | 58.3 | 33.1 | 45.4 | 46 | 57.3 | 63.2 | 58.3 | 54.3 | 55.2 |
| SWE Atlas - Refactoring | 55.2 | 35.7 | 44.8 | — | 46.7 | 51.9 | — | 49.5 | 56.7 |
| SWE Atlas - Test Writing | 47.8 | 28 | 42.6 | 45.9 | 49.6 | 62.2 | 42.2 | 42.2 | 48.9 |
| NL2Repo | 60.5 | 40.9 | — | 56.8 | 69.7 | 75.3 | 58 | 58 | 65.4 |
| LongCat AppDev (Internal) | 73.7 | 47.7 | — | 68.8 | — | 76.4 | 73.5 | 75.1 | — |
| BrowseComp | 91.9 | 79.9 | 84.4 | 90.4 | 84.3 | 90.8 | 81 | 91.2 | 91.5 |
| AutomationBench (v1.0.6) | 51.8 | 15.8 | 39.7 | 45.8 | 41 | 50.3 | 48.2 | 46.7 | 54.8 |
| HLE (w/ tools) | 63.1 | 37.5 | 52.2 | 58 | 57.9 | 64.7 | 62.5 | 56 | 63.9 |
| ALE (v1.1) | 38.5 | — | — | 30.3 | — | — | 26.2 | 35.2 | — |
| ResearchRubrics | 81 | 71.9 | — | 74.2 | — | 72.9 | 79.9 | 78.8 | 80.9 |
| MCP Atlas | 83.1 | 61.8 | 75.3 | 81.8 | 82.2 | 85.8 | 84.2 | 84.2 | 84.4 |
| JobBench | 65.4 | 44.4 | 38.3 | 45.4 | 48.4 | 66.7 | 61.4 | 52.9 | 63.2 |
| SkillsBench | 63.3 | 36.8 | 62.6 | 54.1 | 59.2 | 60.4 | 52.9 | — | 69.8 |
| GDPVal-AA rubrics | 84.8 | 72.9 | — | — | — | 87.7 | 87.7 | 86.6 | 86.8 |
| FrontierScience | 77 | 66 | — | — | — | 78 | 75 | 70 | 73 |
| SpreadsheetBench 2 | 34.9 | 24.1 | 30.2 | 33.3 | — | 33 | 35.8 | 34.8 | 33 |
| FinSearchComp (T3) | 63.4 | 42.4 | 62.2 | 62.2 | — | 64 | 62.2 | 64 | 64.3 |
| Claw-Eval (Pass^3) | 78.3 | 67.1 | — | 79.5 | 82 | 80.8 | 73.9 | 73.9 | — |
| LongCatClawBench (FORTE) | 83.3 | 72.2 | 80.7 | 80.6 | 80.6 | 82.6 | 85.6 | 86.3 | 73.5 |
| 3DCodeBench (Text→3D) | 55.4 | — | 51.9 | 52.3 | 52.7 | 54.3 | 53.4 | 49.3 | 53.3 |
| Vision2Web | 78.6 | — | 74.6 | 73.5 | 76.1 | 80.2 | 77.8 | 79 | 79.2 |
| CharXiv-RQ (w/ tools) | 90.2 | — | 89 | 89.1 | 89.9 | 89.3 | — | 91.3 | 87.7 |
| MathVision (w/ tools) | 96.5 | — | 96.8 | 97.8 | 97.1 | — | — | 97.8 | 97.4 |
| VideoMME | 85.2 | — | — | 89.5 | 86 | — | — | 90 | — |
| PosterBench | 77.4 | — | — | — | 82.3 | — | 82.4 | 76.8 | 75.3 |
| LongCatClawBench-MM (FORTE-MM) | 72.1 | — | 63.5 | 73.2 | 69.9 | 73.1 | 69 | 70.7 | 72.8 |
This model's scores
- BrowseComp91.9%
- Terminal Bench v2.188.4%
- MCP Atlas83.1%
- PaperBench82.1%
- Vision2Web78.6%
- HLE (w/ tools)63.1%
- DeepSWE (v1.1)64.6%
- NL2Repo60.5%
- AutomationBench (v1.0.6)51.8%
- Terminal Bench v4.038.5%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Pricing
| Input | $0.30 / 1M tokens |
|---|---|
| Cached input | $0.006 / 1M tokens |
| Output | $1.20 / 1M tokens |
LongCat API Platform discounted price, labelled limited-time (¥2 / ¥0.04 / ¥8 per 1M tokens in CNY).
Strengths
- 1.6T-parameter Mixture-of-Experts with about 48B active per token, released as MIT-licensed open weights
- Native multimodal input: images and videos alongside text
- 88.4 on Terminal Bench v2.1 and 91.9 on BrowseComp in Meituan's own evaluation
- 1M-token context and up to 256K output tokens on the LongCat API
- OpenAI- and Anthropic-compatible API endpoints, documented for Claude Code, Codex, Hermes Agent and other harnesses
- Hybrid thinking and non-thinking modes
Best for
- Reach for it for long-horizon coding agents — full-project builds and repository-scale work — driven from harnesses such as Claude Code or Codex.
- Reach for it for visual coding: turning screenshots, designs or video into working front-end or 3D code.
- Reach for it as a permissively licensed, self-hostable frontier-scale MoE if you have NPU infrastructure; the published deployment guide targets NPUs.
- Look elsewhere for small-footprint local use: at 1.6T total parameters the weights need multi-accelerator serving.
How to access
| Provider | Model ID |
|---|---|
| LongCat API Platform (OpenAI-compatible) ↗ | LongCat-2.5 |
| LongCat API Platform (Anthropic-compatible) ↗ | LongCat-2.5 |
FAQ
What is LongCat-2.5?
LongCat-2.5 is Meituan's native multimodal Mixture-of-Experts model for long-horizon agentic tasks, made available on the LongCat API Platform on November 2, 2026. It has 1.6 trillion total parameters with about 48 billion active per token and accepts text, images and video.
Is LongCat-2.5 open source?
The model weights are published on Hugging Face under the MIT license, which permits commercial use. Meituan's model card adds that the license grants no rights to Meituan trademarks or patents.
How much does the LongCat-2.5 API cost?
The LongCat API Platform lists a limited-time discounted price of $0.30 per 1M uncached input tokens, $0.006 per 1M cached input tokens and $1.20 per 1M output tokens, and says prices are subject to change.
How does LongCat-2.5 compare with Claude Opus 5 and GPT-5.6-Sol?
In Meituan's table LongCat-2.5 scores 88.4 on Terminal Bench v2.1 against 89.1 for Claude Opus 5 and 88.8 for GPT-5.6-Sol, and 91.9 on BrowseComp against 90.8 and 90.4. Claude Opus 5 leads it on Terminal Bench v4.0 (53.9 vs 38.5) and Program Bench (37.0 vs 25.5). LongCat-2.5's own scores are Meituan's in-house measurements.
What is the context window of LongCat-2.5?
The LongCat API Platform documents a 1M-token context window with a maximum output of 256K tokens.