
Overview
Qwen-Audio-3.1-TTS is the text-to-speech model in Qwen-Audio-3.1, the five-model speech release Alibaba's Qwen team announced on 23 September 2026 alongside Qwen-Audio-3.1-ASR, ASR-Next, TTS-Next and Realtime. In Alibaba Cloud Model Studio it is served as `qwen-audio-3.1-tts-flash`, a streaming model that Alibaba documents for real-time use such as voice assistants and customer service.
Alibaba's research page describes it as a production-oriented system built on a 12.5 Hz low-frame-rate speech tokenizer, which cuts autoregressive decoding cost, and a five-stage progressive training pipeline that pairs a language model with a flow-matching (FM) decoder and ends with reinforcement learning on both. The page lists 16 supported languages, seven of them added in this version, plus 20 Chinese dialect regions and one-pass synthesis of up to 3 minutes.
Control comes in two forms. Free-style natural-language instructions set role, emotion, speaking style, rate, timbre and accent, and 86 fine-grained inline tags adjust delivery at phrase and word level, including non-verbal events such as laughter, breathing, coughing and sighing. For voice cloning, Alibaba says the model stays robust when the reference recording is noisy, reverberant or unclear, without a separate denoising mode.
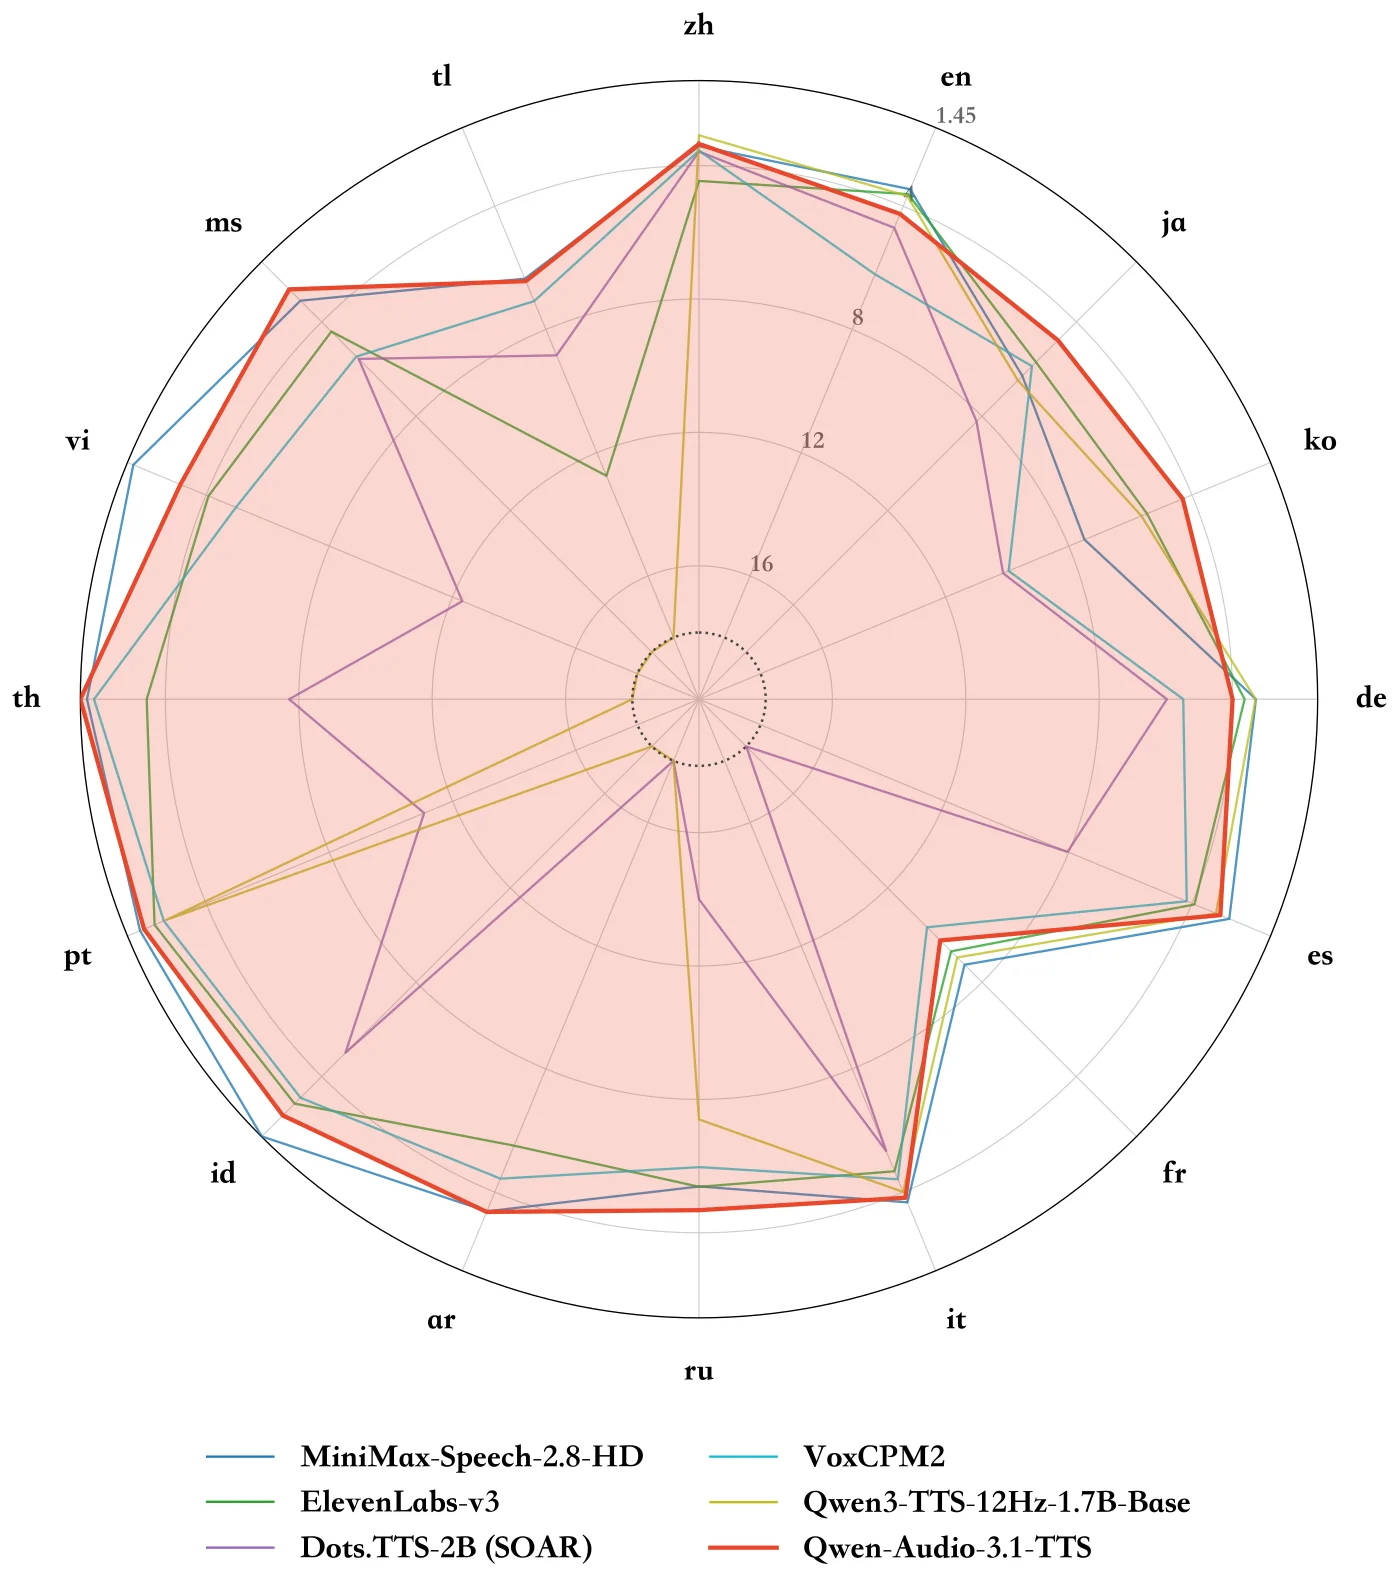
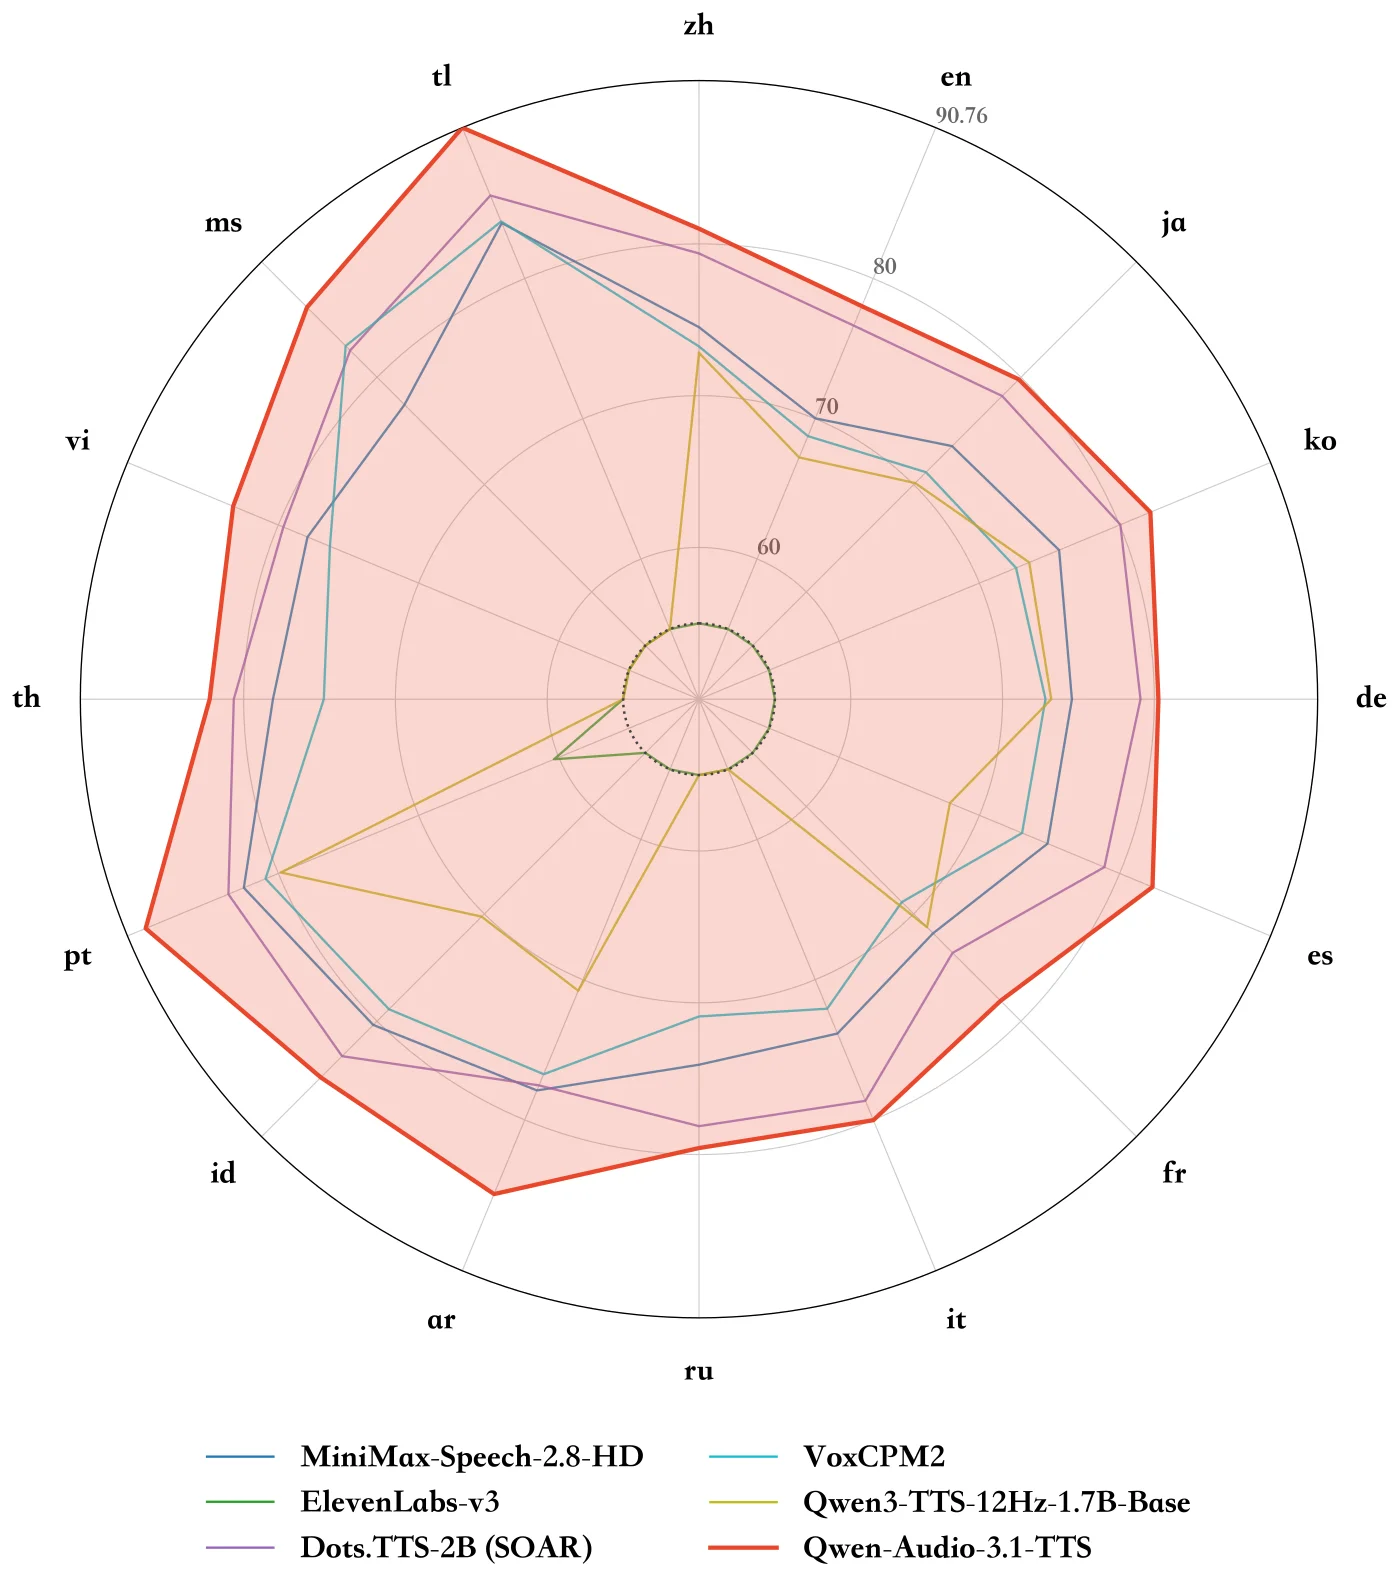
Alibaba's research page reports state-of-the-art results on many dimensions of SEED-TTS-Eval, CV3-Eval, instruction-following, long-form and robustness tests, and publishes CV3-Eval radar charts against MiniMax-Speech-2.8-HD, ElevenLabs-v3, Dots.TTS-2B (SOAR), VoxCPM2 and Qwen3-TTS-12Hz-1.7B-Base. It also states the model ranks first on the Artificial Analysis Text-to-Speech Leaderboard.
The release came with a price cut of about 70% for TTS, according to the Qwen launch post. Alibaba Cloud's price notice lists qwen-audio-3.1-tts-flash in the Singapore region at $0.23 per 1M input tokens and $1.87 per 1M output tokens from 22 September 2026 (UTC+8), replacing per-character billing of $0.15 per 10,000 characters.
| Released | 2026-09-23 |
|---|---|
| License | Proprietary (hosted API) |
| Weights | API only |
| Parameters | Not disclosed |
| Modalities | Text, Audio |
Benchmarks
Pricing
| Input | $0.23 / 1M tokens |
|---|---|
| Output | $1.87 / 1M tokens |
Singapore region rates for qwen-audio-3.1-tts-flash from 22 September 2026 (UTC+8). The China (Beijing) model page lists 1.5 CNY input and 12 CNY output per 1M tokens.
Strengths
- 16 languages (seven new in 3.1) and 20 Chinese dialect regions in one model
- Natural-language instructions for role, emotion, style, rate, timbre and accent, plus 86 inline tags for word-level control and non-verbal sounds
- Voice cloning that Alibaba says holds up with noisy, reverberant or unclear reference audio
- One-pass long-form synthesis of up to 3 minutes
- Streaming output for real-time assistants and customer-service voices
- $0.23 / $1.87 per 1M input / output tokens in Singapore after the September 2026 price cut
Best for
- Reach for it for voice assistants and customer-service agents that need streaming speech in several languages
- Reach for it for Chinese-market products that need dialect voices, such as Cantonese, Sichuan or Shanghai
- Reach for it for narration and dubbing directed by instruction rather than by picking a fixed voice
- Reach for Qwen-Audio-3.1-TTS-Next instead for podcasts, games and ads that need sound effects and ambience mixed with speech
How to access
| Provider | Model ID |
|---|---|
| Alibaba Cloud Model Studio ↗ | qwen-audio-3.1-tts-flash |
Qwen-Audio (speech) — every version
The full lineage of the Qwen-Audio (speech) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Qwen-Audio-3.1-TTScurrent | 2026-09-23 | — | Proprietary (hosted API) |
| Qwen-Audio-3.1-ASR | 2026-09-23 | 8K | Proprietary (hosted API) |
| Qwen-Audio-3.1-TTS-Next | 2026-09-22 | — | Proprietary (hosted API) |
FAQ
What is Qwen-Audio-3.1-TTS?
Qwen-Audio-3.1-TTS is Alibaba's hosted text-to-speech model from the Qwen-Audio-3.1 release of 23 September 2026. It is served in Alibaba Cloud Model Studio as qwen-audio-3.1-tts-flash and supports streaming synthesis, voice cloning, and control through instructions and inline tags.
Which languages and dialects does it support?
Alibaba's research page lists 16 languages, seven of them new in 3.1, and 20 Chinese dialect regions, including Cantonese, Sichuan, Shanghai and Northeast dialects.
Are the weights open?
No. Qwen-Audio-3.1-TTS is offered as a hosted API in Alibaba Cloud Model Studio, with no weight download.
What does it cost?
Alibaba Cloud's September 2026 price notice lists qwen-audio-3.1-tts-flash in Singapore at $0.23 per 1M input tokens and $1.87 per 1M output tokens from 22 September 2026 (UTC+8). The China (Beijing) page lists 1.5 CNY and 12 CNY per 1M tokens. The Qwen launch post describes the TTS cut as about 70%.
How does it compare with ElevenLabs and MiniMax?
Alibaba published CV3-Eval radar charts setting Qwen-Audio-3.1-TTS against MiniMax-Speech-2.8-HD, ElevenLabs-v3, Dots.TTS-2B, VoxCPM2 and Qwen3-TTS across 16 languages. On speaker similarity its outline sits outermost on every language; on content consistency it is close to the leaders, with MiniMax-Speech-2.8-HD ahead on some languages.