Overview
Beam is Reflection AI's first open-weight model, announced on October 5, 2026. It is a sparse Mixture-of-Experts language model with 501 billion total parameters, of which 23 billion are active per token, built for coding, reasoning and agentic work. Reflection AI describes Beam as the first model in a series.
Beam is a text model; Reflection AI says it can work with other modalities when they are represented as text. Midtraining extends its effective context length to 1M tokens, and its reinforcement-learning stage used a maximum context of 256K tokens.
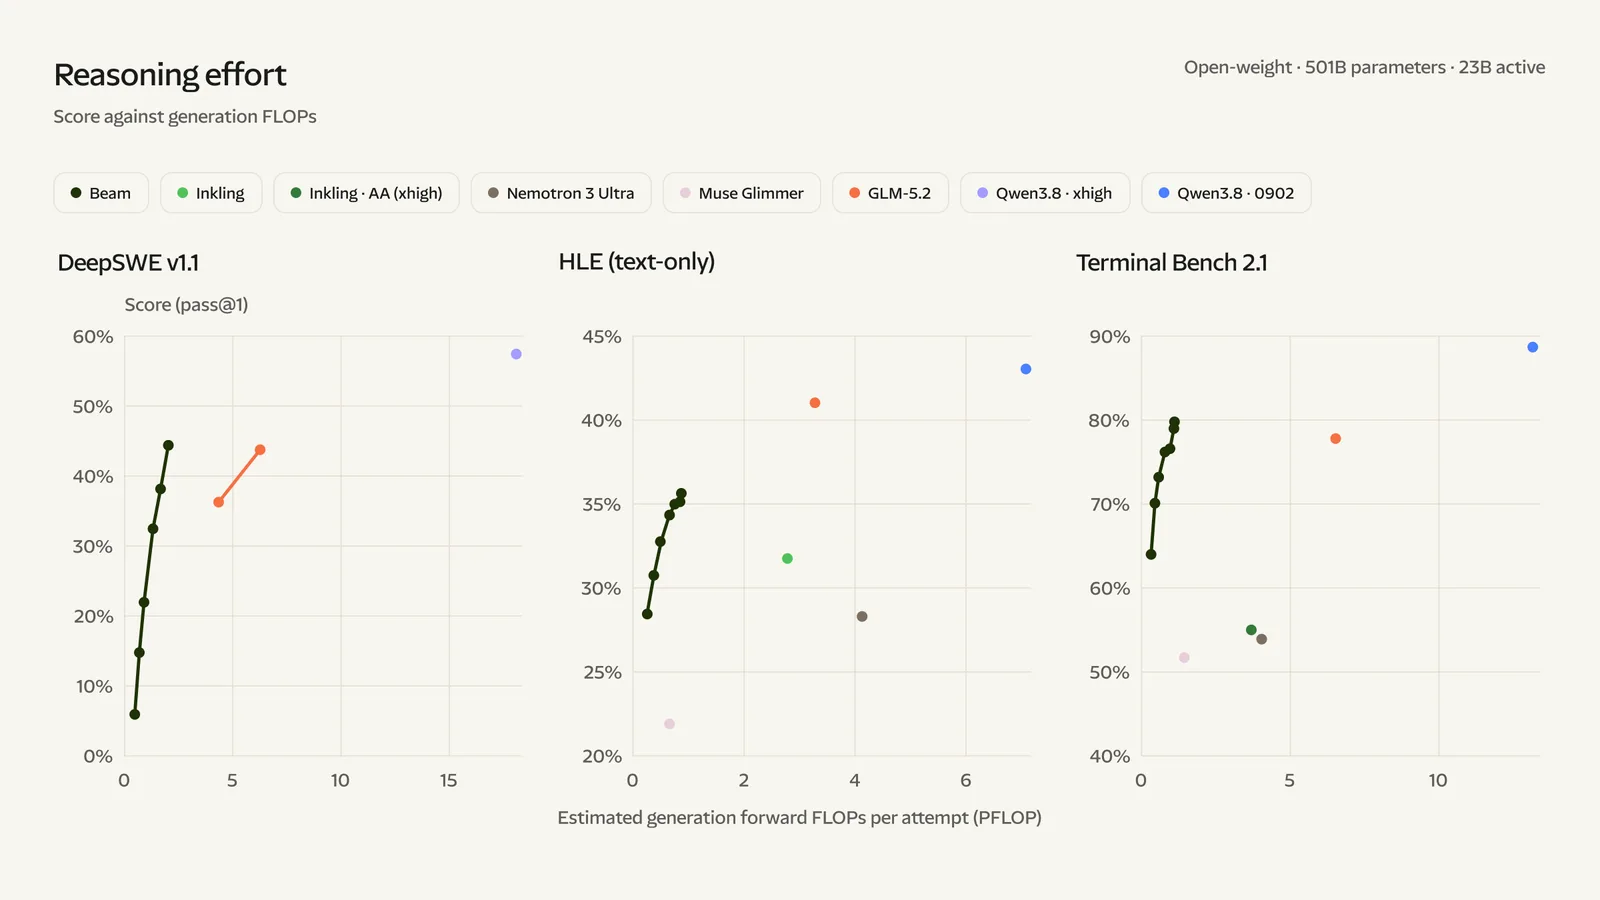
Reflection AI pretrained Beam on 23.8 trillion tokens in under four weeks on a cluster of 6,144 NVIDIA GB300 NVL72 GPUs. Its reinforcement-learning run generated over 100 million rollouts on 10.5K NVIDIA GB300 GPUs over four weeks of training.
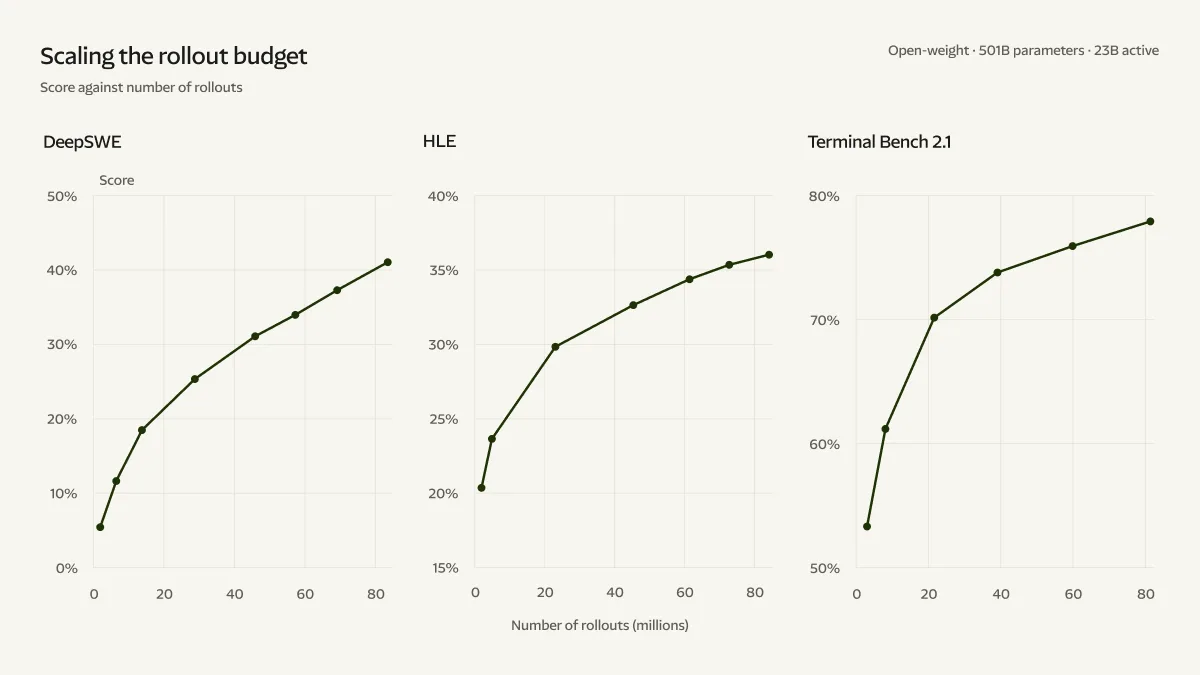
In Reflection AI's launch tables Beam scores 80.9 on SWE-bench Verified, 80.1 on Terminal Bench v2.1, 78.0 on SWE-bench Multilingual, 97.8 on AIME 2026 and 90.5 on GPQA Diamond, set against Inkling, Nemotron 3 Ultra, GLM 5.2, GLM 5.3, Kimi K3, Qwen 3.8 Max and DeepSeek V4.1 Flash. Reflection AI updated Beam's results on October 8, 2026; the table on this page uses the updated launch-post figures.
At announcement Beam was in final red-teaming and evaluation, open to a select group of users through a waitlist on Reflection AI's platform. Reflection AI says it will release the weights under the Apache 2.0 license later in October 2026, together with a technical report, a model card and developer artifacts.
| Released | 2026-10-05 |
|---|---|
| License | Apache-2.0 (announced — Reflection AI says it will release the weights under Apache 2.0 in October 2026) |
| Weights | API only |
| Parameters | 501B total · 23B active |
| Context | 1M tokens (effective context, extended in midtraining) |
| Architecture | Sparse Mixture-of-Experts |
| Modalities | Text |
| Status | Preview — early access for a select group of users through the waitlist at platform.reflection.ai; Reflection AI says the weights, technical report, model card and developer artifacts will be released later in October 2026. |
Benchmarks
Beam against open models, transcribed from Reflection AI's launch post (results updated October 8, 2026). Blank cells were not reported; Reflection AI used Artificial Analysis and DataCurve as sources for other models' evals.
| Benchmark | Beam | Inkling | Nemotron 3 Ultra | GLM 5.2 | GLM 5.3 | Kimi K3 | Qwen 3.8 Max | DeepSeek V4.1 Flash |
|---|---|---|---|---|---|---|---|---|
| DeepSWE v1.1 | 44.4 | — | — | 44 | 61 | 68 | 51 | 74.2 |
| SWE Bench Pro v2-Hard | 77.2 | 56.9 | — | — | 84.3 | 88.2 | — | — |
| SWE Bench Pro v1 | 65.5 | 54.3 | 46.4 | 62.1 | — | — | 67.7 | — |
| Terminal Bench v2.1 | 80.1 | 63.8 | 56.4 | 81 | 88.2 | 88.3 | 86.6 | 90.6 |
| SWE Atlas Codebase QnA | 34.6 | — | — | — | 61 | 68 | — | — |
| SWE-bench Multilingual | 78 | — | 67.7 | — | — | — | — | — |
| SWE-bench Verified | 80.9 | 77.6 | 70.7 | — | — | — | — | — |
| AIME 2026 | 97.8 | 97.1 | — | 99.2 | — | — | — | — |
| HLE (no tools) | 36.2 | 29.7 | 26.7 | 40.5 | 42.3 | 46.9 | 43.6 | 39.1 |
| SciCode | 49.7 | 46.1 | 44.6 | — | 59 | 58.7 | 52.1 | 52 |
| CritPT (AA) | 16.3 | 5.4 | 3.1 | 20.9 | 19.1 | 23.4 | 20 | 14.3 |
| GPQA Diamond | 90.5 | 87.2 | 87 | 91.2 | 91.7 | 93.5 | 92.6 | 90.9 |
| AutomationBench (public) | 37 | — | — | 26.2 | 48.2 | 46.7 | 39.8 | 54.8 |
| MCP Atlas | 78.7 | 76 | 63.1 | 77.8 | 84.2 | 82.3 | 84.5 | — |
| tau3 banking | 38 | 25 | 22.6 | 37.1 | — | 37.1 | 55.2 | — |
| BrowseComp (w/ context management) | 77.4 | 77.1 | 44.4 | — | — | 91.2 | — | — |
| DeepSearchQA (w/ context management) | 80.1 | — | — | — | — | 95 | — | — |
| AA-LCR | 79.3 | 77.3 | 79.3 | 78.3 | 79.7 | 88.7 | 80.3 | 84 |
| LongBench v2 | 65.5 | — | 61.9 | 64 | — | — | 66.3 | — |
| IFBench | 79.7 | 79.8 | 81.7 | 73.3 | — | — | 82.8 | — |
| AA Omniscience Index (public split, Reflection's runs) | 13 | 14.2 | 8.6 | — | 22.6 | — | — | 6.6 |
This model's scores
- AIME 202697.8%
- GPQA Diamond90.5%
- SWE-bench Verified80.9%
- Terminal Bench v2.180.1%
- IFBench79.7%
- AA-LCR79.3%
- MCP Atlas78.7%
- SWE-bench Multilingual78%
- BrowseComp (with context management)77.4%
- SWE-Bench Pro v2-Hard77.2%
- SWE-Bench Pro v165.5%
- SciCode49.7%
- DeepSWE v1.144.4%
- Humanity's Last Exam (no tools)36.2%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
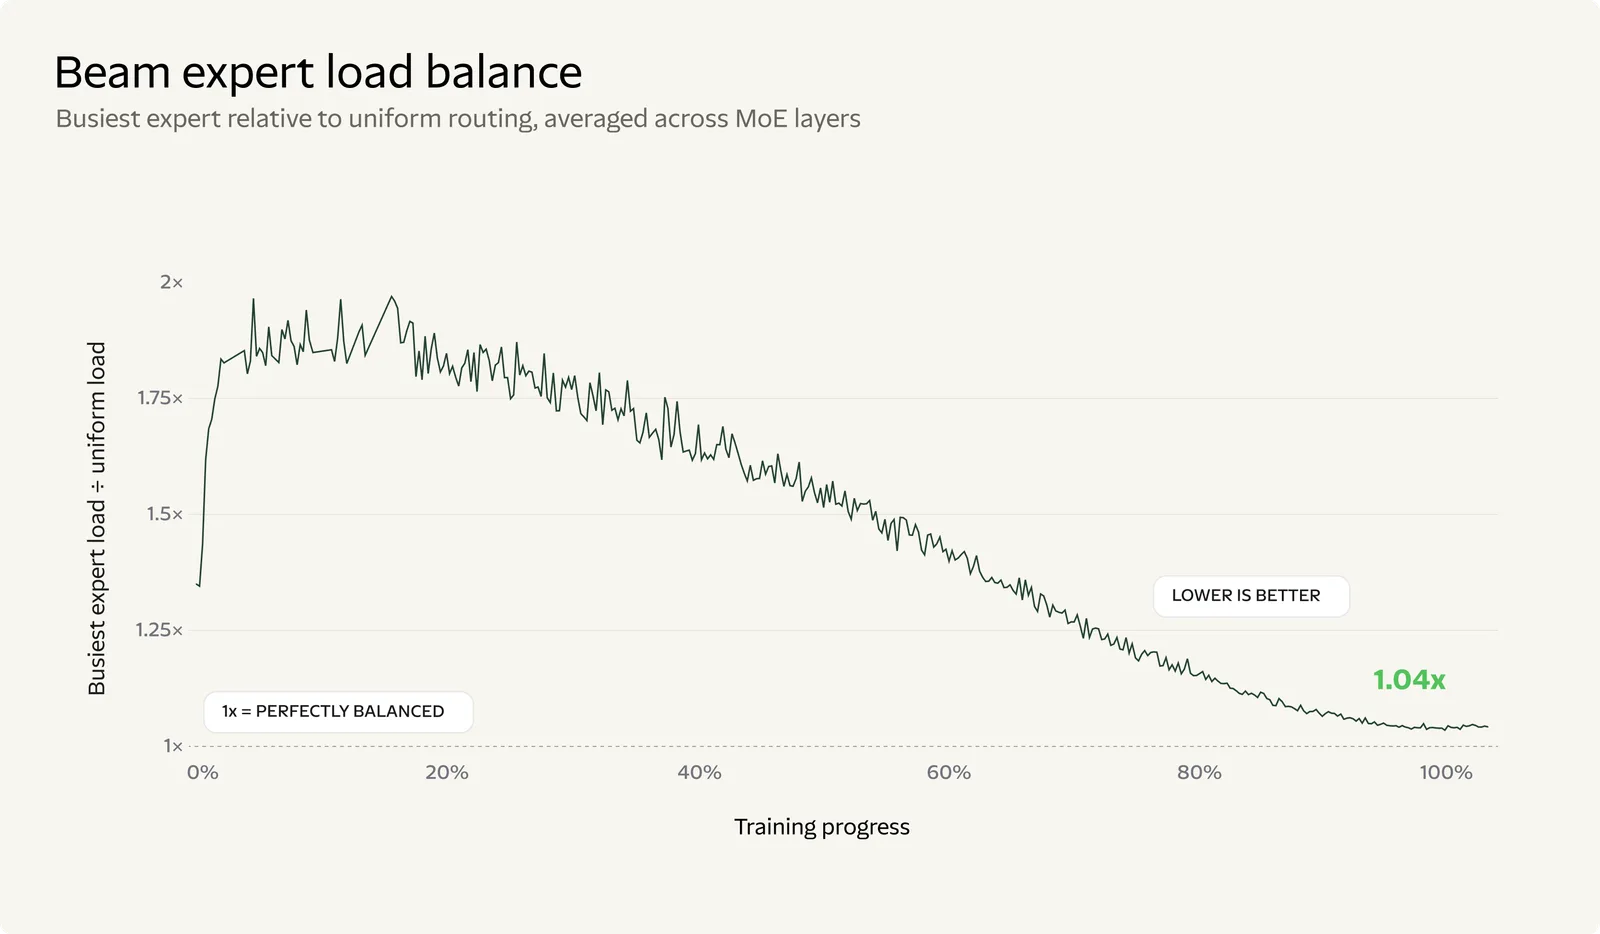
- Sparse MoE with 23B active of 501B total parameters
- 80.9 on SWE-bench Verified and 80.1 on Terminal Bench v2.1 in Reflection AI's launch table
- 97.8 on AIME 2026 and 90.5 on GPQA Diamond
- Effective context length of 1M tokens
- Weights announced under the permissive Apache 2.0 license
Best for
- Reach for it for agentic coding and terminal tasks once you have early access or the weights.
- Reach for it for self-hosted coding agents once the Apache 2.0 weights are released.
- Look elsewhere for image, audio or video input: Beam is a text-only model.
How to access
| Provider | Model ID |
|---|---|
| Reflection AI platform (early-access waitlist) ↗ | — |
FAQ
What is Reflection Beam?
Beam is Reflection AI's first open-weight model, announced on October 5, 2026. It is a sparse Mixture-of-Experts language model with 501B total and 23B active parameters, built for coding, reasoning and agentic tasks.
Can I download the Beam weights?
Not at announcement. Reflection AI says it will release the weights under the Apache 2.0 license later in October 2026, together with a technical report, model card and developer artifacts. Until then Beam is open to a select group of users through a waitlist on platform.reflection.ai.
What is Beam's context window?
Reflection AI says midtraining extends Beam's effective context length to 1M tokens. Its reinforcement-learning stage used a maximum context of 256K tokens.
How does Beam score on coding benchmarks?
In Reflection AI's launch tables Beam scores 80.9 on SWE-bench Verified, 80.1 on Terminal Bench v2.1, 78.0 on SWE-bench Multilingual, 77.2 on SWE Bench Pro v2-Hard and 44.4 on DeepSWE v1.1. On Terminal Bench v2.1 the same table lists 81.0 for GLM 5.2 and 86.6 for Qwen 3.8 Max.
How was Beam trained?
Reflection AI pretrained Beam on 23.8 trillion tokens in under four weeks on 6,144 NVIDIA GB300 NVL72 GPUs, then ran reinforcement learning that generated over 100 million rollouts on 10.5K GB300 GPUs over four weeks.