Sebastian Raschka · 2026-09-29 · notable
Sebastian Raschka — text classification from bag-of-words to Jev
Sebastian Raschka traces text classification from bag-of-words and naive Bayes to BERT and GPT, then tests Jev on IMDb reviews: 96.47% accuracy, close to a fine-tuned ModernBERT, for $0.65 across 25,000 reviews.
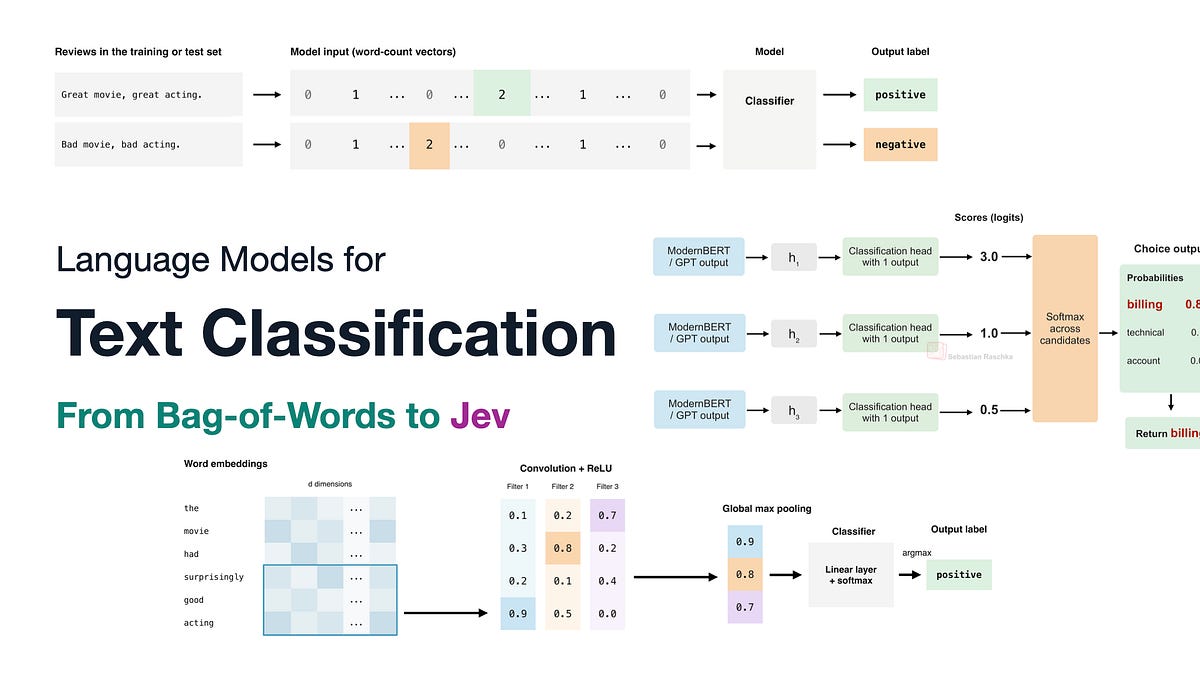
Sebastian Raschka puts Jev in the long history of text classifiers and tests it on IMDb.
What is it?
Text classification is the subject of Sebastian Raschka's 29 September 2026 article. The article walks from pre-transformer methods — bag-of-words, naive Bayes, logistic regression, RNNs and CNNs — through BERT, GPT and T5, and ends with Jev, TypeSafe's decision model.
How does it work?
On the IMDb review test set, Jev scores 96.47% accuracy, close to a fine-tuned ModernBERT, and classifies all 25,000 reviews in 22 minutes 24 seconds for $0.65. Raschka compares that with older baselines on the same data, then offers what he calls educated guesses about Jev's design: a small ModernBERT-like model trained on synthetic data with a method for calibrated decisions.
Why does it matter?
Raschka argues Jev is 'the ChatGPT moment for classification': one API that handles many classification tasks with no fine-tuning and returns calibrated probabilities. The history section also works as a single-page primer for anyone deciding between a fine-tuned encoder, a general LLM and a decision model.
Who is it for?
ML engineers choosing a text classifier