Overview
Atria Dawn is the full release of the Shanghai Artificial Intelligence Laboratory's agentic model, following Atria Dawn Preview of 11 September 2026. The project's GitHub README switched from the Preview to the full release on 14 October 2026, listing the Atria Dawn instruct and FP8 checkpoints as coming soon; the weights went up on Hugging Face and ModelScope on 23 October 2026 under the MIT licence. Like the Preview, it is built on the 744B-parameter MoE GLM-5.2 foundation model and aims at research and engineering work that needs continuous environmental understanding, tool use and multi-step task completion.
The model card frames the goal as driving open-ended problems toward executable, verifiable and reproducible results, covering the loop from problem analysis and solution design through tool use, code, experiments, result analysis and failure recovery. It keeps the Preview's four capability dimensions: Discovery (evidence retrieval, deep research, experimental plans), Creation (software, applications, games, visualisations, ML systems), Delivery (reports, presentations and other structured deliverables) and Cybersecurity (validating vulnerabilities, applying fixes and re-validating in authorised environments).
The practical change from the Preview is context: the model download table lists 512K tokens for both full-release checkpoints against 256K for the Preview. On the lab's own comparison the full release improves on the Preview on most rows — AutomationBench 54.7 (from 53.8), SkillsBench 67.8 (66.4), WideSearch 84.6 (81.9), MLE-bench Lite 88.2 (86.2), Terminal-Bench 2.1 81.0 (78.3), SWE-bench Pro 61.7 (59.6) — while BrowseComp slips from 92.5 to 91.3 and NL2Repo-Bench from 51.4 to 50.0. Against the named frontier peers it leads on AutomationBench, CyberGym, SkillsBench, WideSearch, BFCL v4, DeepSearchQA and Harvey LAB, and trails Claude Opus 5 and Qwen 3.8 Max on coding rows such as SWE-bench Pro and Terminal-Bench 2.1.
The endpoint takes text input only. Hosted access runs through the Intern Discovery API console for international and China regions, with OpenAI-compatible and Anthropic-compatible base URLs, and the README documents custom-provider setups for Codex, Claude Code and Kimi Code using the model id Atria-Dawn. For local serving it names SGLang v0.5.13.post1 or newer and vLLM v0.23.0 or newer, pointing at the GLM-5.2 deployment guides.
| Released | 2026-10-14 |
|---|---|
| License | MIT |
| Weights | Open weights |
| Parameters | 744B Mixture-of-Experts (built on the GLM-5.2 foundation model) |
| Context | 512K |
| Modalities | Text |
| Status | Generally available — hosted API from 14 October 2026; instruct and FP8 weights on Hugging Face and ModelScope from 23 October 2026 |
Benchmarks
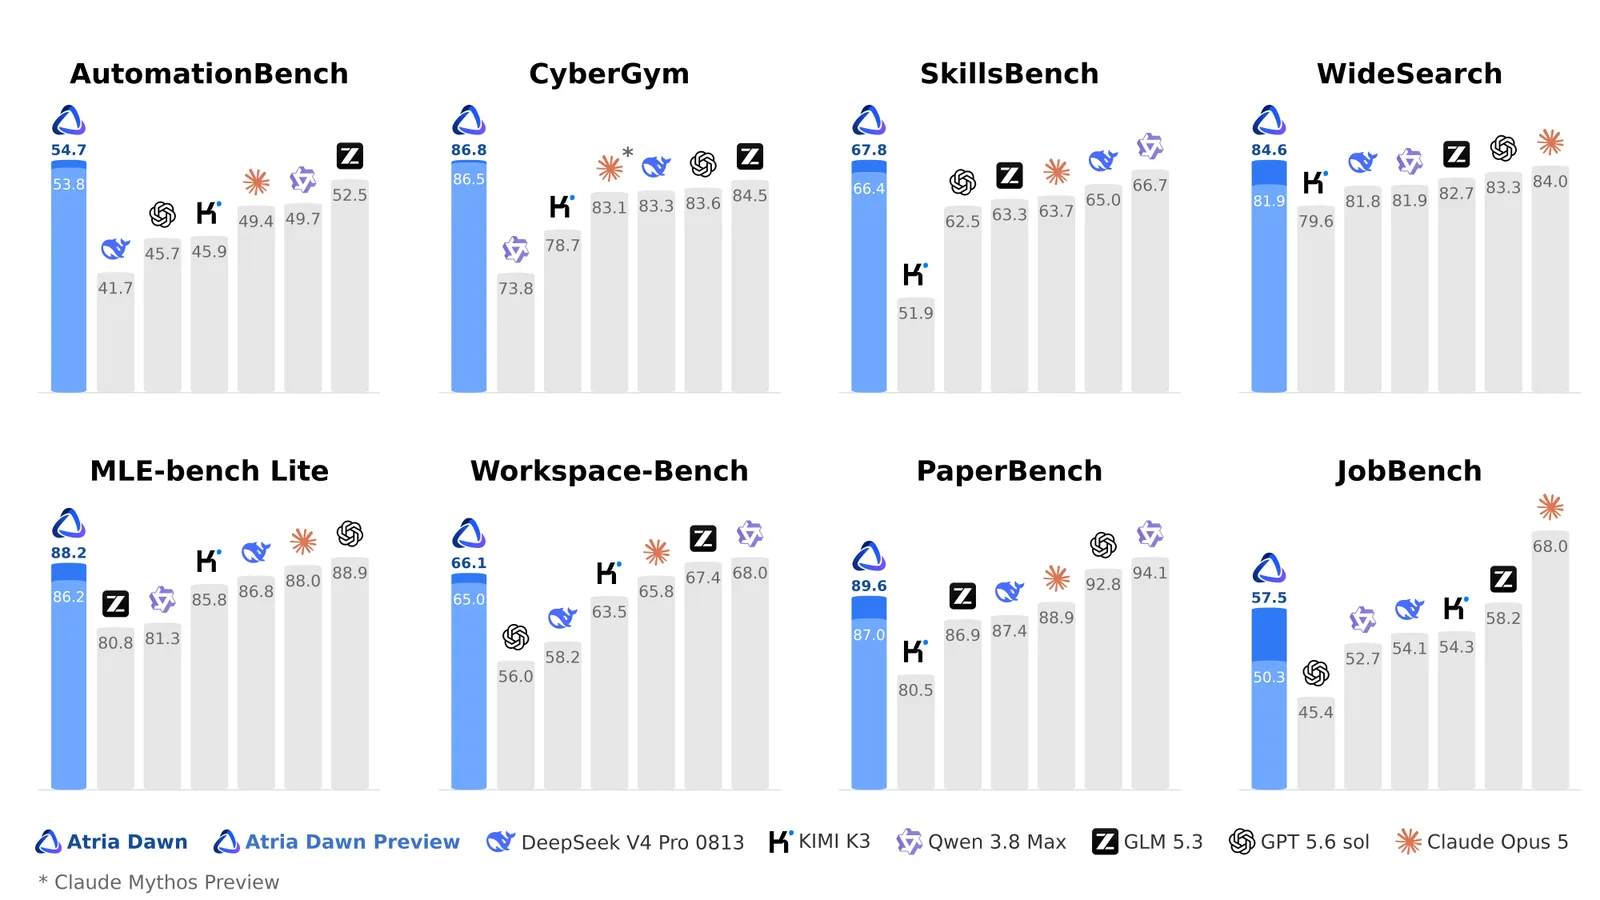
Atria Dawn against its Preview and named peers, as published on the Atria Dawn model card. GDPval is an Elo-style rating, not a percentage.
| Benchmark | Atria Dawn | Atria Dawn Preview | DeepSeek V4 Pro 0813 | Kimi K3 | Qwen 3.8 Max | GLM 5.3 | GPT-5.6 Sol | Claude Opus 5 |
|---|---|---|---|---|---|---|---|---|
| AutomationBench | 54.7 | 53.8 | 41.7 | 45.9 | 49.7 | 52.5 | 45.7 | 49.4 |
| CyberGym | 86.8 | 86.5 | 83.3 | 78.7 | 73.8 | 84.5 | 83.6 | — |
| SkillsBench | 67.8 | 66.4 | 65 | 51.9 | 66.7 | 63.3 | 62.5 | 63.7 |
| WideSearch | 84.6 | 81.9 | 81.8 | 79.6 | 81.9 | 82.7 | 83.3 | 84 |
| MLE-bench Lite | 88.2 | 86.2 | 86.8 | 85.8 | 81.3 | 80.8 | 88.9 | 88 |
| Workspace-Bench-Lite | 70 | 68.2 | 62.1 | 64.9 | 68.7 | 71.7 | 60.5 | 70.1 |
| Workspace-Bench | 66.1 | 65 | 58.2 | 63.5 | 68 | 67.4 | 56 | 65.8 |
| PaperBench | 89.6 | 87 | 87.4 | 80.5 | 94.1 | 86.9 | 92.8 | 88.9 |
| JobBench | 57.5 | 50.3 | 54.1 | 54.3 | 52.7 | 58.2 | 45.4 | 68 |
| GDPval | 1594.2 | 1583.8 | 1493.3 | 1606.8 | 1710.9 | 1643.1 | 1611.1 | 1714 |
| DeepResearch Bench II | 51.2 | 51.1 | 46.6 | 51.3 | 49.2 | 52.7 | 50.7 | 54.1 |
| SpreadsheetBench 2 | 33 | 31.5 | 29.3 | 35.8 | 34.9 | 32.1 | 32.7 | 33.6 |
| τ³-bench Banking | 43.3 | 41.2 | 44.3 | 37.1 | 55.2 | 40.2 | 46.9 | 48.7 |
| Terminal-Bench 2.1 | 81 | 78.3 | 77 | 84 | 89.6 | 86 | 86.2 | 90.2 |
| SWE-bench Pro | 61.7 | 59.6 | 58.4 | 62 | 65.3 | 60.3 | 59.8 | 76.5 |
| NL2Repo-Bench | 50 | 51.4 | 49.5 | 63.1 | 63.2 | 54.8 | 60.7 | 79.9 |
| Harbor-Index | 17.3 | 17.3 | 17 | 24.3 | 25.8 | 20 | 35.8 | 41 |
| DeepSWE | 49.3 | — | 54.9 | 70.6 | 67 | 67.3 | 70.6 | 72.6 |
| Harvey LAB | 27.5 | — | 6.7 | 25.4 | 24.2 | 22.5 | 5 | 22.7 |
| BFCL V4 | 78.4 | 77 | 71.4 | 69.1 | — | 74.1 | — | — |
| DeepSearchQA | 96.5 | 96 | — | 95.9 | — | 94.7 | 93.2 | — |
| OfficeQA Pro | 67.1 | — | 66.2 | 65.4 | 66.2 | 65.8 | 66.4 | 67.2 |
| BrowseComp | 91.3 | 92.5 | 83.4 | 91.2 | — | 89.6 | 92.2 | 90.8 |
This model's scores
- DeepSearchQA96.5%
- BrowseComp91.3%
- PaperBench89.6%
- MLE-bench Lite88.2%
- CyberGym86.8%
- WideSearch84.6%
- Terminal-Bench 2.181%
- BFCL V478.4%
- SkillsBench67.8%
- SWE-bench Pro61.7%
- AutomationBench54.7%
- DeepSWE49.3%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- MIT licence on a 744B-parameter MoE, with instruct and FP8 checkpoints downloadable from Hugging Face and ModelScope
- 512K-token context window, double the 256K of Atria Dawn Preview
- Highest score in the lab's comparison on AutomationBench (54.7), CyberGym (86.8), SkillsBench (67.8), WideSearch (84.6), BFCL v4 (78.4) and DeepSearchQA (96.5)
- OpenAI- and Anthropic-compatible hosted endpoints with documented Codex, Claude Code and Kimi Code configurations
- Documented SGLang and vLLM deployment paths for self-hosting
Best for
- Deep-research agents that gather evidence and turn a research question into an executable plan
- Long-running engineering and ML-experiment agents that need to run code and recover from failures
- Authorised security work: validating vulnerabilities, applying fixes and re-checking them
- Office and document delivery agents producing reports and spreadsheets from source material
How to access
| Provider | Model ID |
|---|---|
| Intern Discovery API (international) ↗ | Atria-Dawn |
| Intern Discovery API (China) ↗ | Atria-Dawn |
| Hugging Face (weights) ↗ | internlm/Atria-Dawn |
Atria (agentic) — every version
The full lineage of the Atria (agentic) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Atria Dawncurrent | 2026-10-14 | 512K | MIT |
| Atria Dawn Preview | 2026-09-11 | 256K | MIT |
FAQ
How is Atria Dawn different from Atria Dawn Preview?
Both are 744B MoE models built on GLM-5.2 under MIT. The full release doubles the context to 512K tokens and scores higher than the Preview on most rows of the lab's comparison, such as AutomationBench (54.7 vs 53.8), WideSearch (84.6 vs 81.9) and Terminal-Bench 2.1 (81.0 vs 78.3); BrowseComp and NL2Repo-Bench dip slightly.
When did it come out?
The project README moved from the Preview to the full release on 14 October 2026, with the weights listed as coming soon. The instruct and FP8 checkpoints were published on Hugging Face and ModelScope on 23 October 2026.
Is it multimodal?
No. The README states it accepts text input only; the endpoint rejects images with "400 Atria-Dawn is not a multimodal model", and the Codex, Claude Code and Kimi Code setup notes show how to strip image input on the client side.
How do I use it from a coding agent?
Point an OpenAI-compatible client at https://discovery-api.intern-ai.org.cn/v1, or an Anthropic-compatible client at https://discovery-api.intern-ai.org.cn, with the model id Atria-Dawn. The README gives ready configurations for Codex (Responses API), Claude Code and Kimi Code.
How do I run it locally?
The model card lists SGLang v0.5.13.post1 or newer and vLLM v0.23.0 or newer, each with a GLM-5.2 deployment guide. An FP8 checkpoint is published alongside the full-precision one.