Overview
Sage-A1.5 is a 35B Mixture-of-Experts agentic model from the InternScience team of the Shanghai Artificial Intelligence Laboratory, released by its Alpha-Innovator Lab. It builds on Qwen3.6-35B-A3B and on Agents-A1, the lab's 35B-A3B agent model open-sourced on June 26, 2026, and aims at long-horizon scientific problem solving. The Hugging Face repository was created on October 15, 2026 and the technical report went up on arXiv on October 20, 2026; the weights are on Hugging Face and ModelScope under Apache 2.0, with FP8 and GGUF editions in the same collection.
The model card frames the step from Agents-A1 as learning to organise work and revise its approach during execution, not only to solve single tasks, through three capabilities. Agentic orchestration splits a task across parallel subagents with isolated contexts. Agentic verification checks progress, validates evidence and revises strategy so the agent can abandon an unproductive search path; the project page describes it as an opt-in self-review in the model's own chain of thought with no external critic. Open scientific discovery moves from answering fixed questions to exploratory research with interactive analysis and inspectable research artifacts. The project page describes three training stages over a domain-grounded knowledge-action graph: full-domain supervised fine-tuning, domain-level teacher models and multi-teacher on-policy distillation.
On the lab's comparison table, Sage-A1.5 scores 95.1 on GAIA, 92.0 on XBench-DS-2510, 61.2 on SWE-bench Pro, 72.7 on SWE-bench Multilingual, 81.6 on IFBench, 55.1 on Humanity's Last Exam with tools and 90.0 on PinchBench. Against the other ~35B models in the table (Agents-A1, Qwen3.6-35B-A3B, Ornith-1.5) it leads most rows, with Agents-A1 ahead on GAIA (96.0), HiPhO and MatTools and Ornith-1.5 ahead on DeepResearch-Bench2. Against the larger Kimi-K3, GLM-5.3 and GPT-5.6-sol it trails on most coding and search rows but leads on FrontierScience-Olympiad (81.0 against 73.0 at best), FrontierScience-Research (48.3 against 26.7), CMT (80.0 against 50.0), IFBench and PinchBench. BrowseComp rises from 81.7 to 82.8 and DeepResearch-Bench2 from 43.7 to 47.5 with agentic orchestration turned on.
The model loads in Hugging Face Transformers and serves through vLLM or SGLang behind an OpenAI-compatible endpoint; the model card's standard vLLM command runs it on one GPU with the full 262,144-token context, the qwen3 reasoning parser and the qwen3_coder tool-call parser, and it documents a text-only mode that skips the vision encoder, multi-token-prediction speculative decoding, and a YaRN override that extends the context to 524,288 tokens. Recommended sampling is temperature 1.0, top_p 0.95, top_k 20 and presence_penalty 1.5. The card also links a free hosted trial at discovery.intern-ai.org.cn.
| Released | 2026-10-20 |
|---|---|
| License | Apache 2.0 |
| Weights | Open weights |
| Parameters | 35B Mixture-of-Experts (based on Qwen3.6-35B-A3B) |
| Context | 256K (512K with YaRN) |
| Architecture | Mixture-of-Experts vision-language model (qwen3_5_moe architecture) post-trained from Qwen3.6-35B-A3B and Agents-A1; native 262,144-token context, extendable to 524,288 with YaRN factor 2.0. |
| Modalities | Text, Vision |
| Status | Open weights on Hugging Face and ModelScope |
Benchmarks
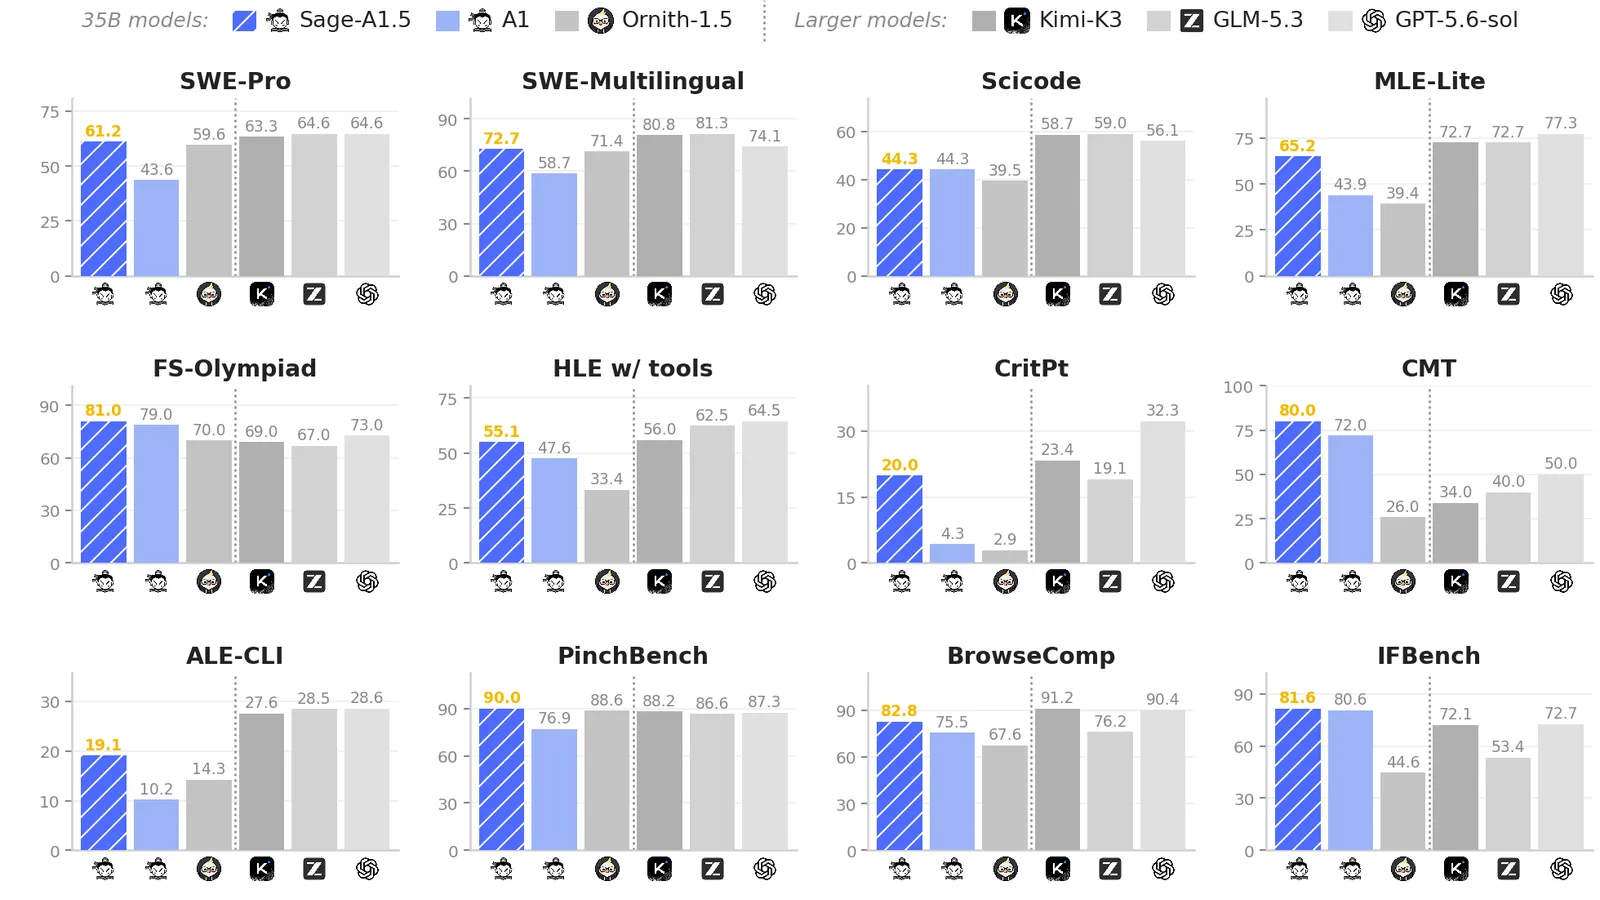
Sage-A1.5 against ~35B models and larger models, as published on its model card
| Benchmark | Sage-A1.5 | Agents-A1 | Qwen3.6-35B-A3B | Ornith-1.5 | Kimi-K3 | GLM-5.3 | GPT-5.6-sol |
|---|---|---|---|---|---|---|---|
| GAIA | 95.1 | 96 | 78.6 | 77.6 | 92.2 | 92.2 | 88.3 |
| BrowseComp (w/ agentic orchestration) | 82.8 | 75.5 | 67.9 | 67.6 | 91.2 | 76.2 | 90.4 |
| DeepResearch-Bench2 (w/ agentic orchestration) | 47.5 | 37.5 | 45.1 | 48.6 | 52.4 | 55.7 | 57.9 |
| XBench-DS-2510 | 92 | 86 | 71 | 80 | 85 | 84 | 90 |
| MLE-Lite | 65.2 | 43.9 | 37.9 | 39.4 | 72.7 | 72.7 | 77.3 |
| SciCode | 44.3 | 44.3 | 36.6 | 39.5 | 58.7 | 59 | 56.1 |
| SWE-bench Pro | 61.2 | 43.6 | 49.5 | 59.6 | 63.3 | 64.6 | 64.6 |
| SWE-bench Multilingual | 72.7 | 58.7 | 67.2 | 71.4 | 80.8 | 81.3 | 74.1 |
| IFBench | 81.6 | 80.6 | 64.4 | 44.6 | 72.1 | 53.4 | 72.7 |
| AA-LCR | 81 | 74.2 | 71.7 | 73.2 | 88.7 | 79.7 | 84 |
| FrontierScience-Olympiad | 81 | 79 | 60.3 | 70 | 69 | 67 | 73 |
| FrontierScience-Research | 48.3 | 40 | 2.9 | 6.7 | 21.7 | 16.7 | 26.7 |
| HiPhO | 45.3 | 46.4 | 37.7 | 39.5 | 42.4 | 39.7 | 46.2 |
| HLE w/ tools | 55.1 | 47.6 | 36.2 | 33.4 | 56 | 62.5 | 64.5 |
| CMT | 80 | 72 | 20 | 26 | 34 | 40 | 50 |
| CritPt | 20 | 4.3 | 0.3 | 2.9 | 23.4 | 19.1 | 32.3 |
| Agents' Last Exam (ALE-CLI) | 19.1 | 10.2 | 3.81 | 14.3 | 27.6 | 28.5 | 28.6 |
| VitaBench | 45.4 | 38.7 | 35.6 | 44.6 | 59 | 58.7 | 46.8 |
| PinchBench | 90 | 76.9 | 88.1 | 88.6 | 88.2 | 86.6 | 87.3 |
| ChemCOTBench | 66.5 | 64 | 59.3 | 53.8 | 82.5 | 78.3 | 77.9 |
| MatTools | 42.6 | 47.1 | 15.9 | 38.6 | 24.3 | 53.2 | 45.6 |
| OmniDocBench | 91.5 | 89.5 | 89.9 | 89.6 | 91.1 | — | 85.8 |
This model's scores
- GAIA95.1%
- XBench-DS-251092%
- PinchBench90%
- BrowseComp (with agentic orchestration)82.8%
- IFBench81.6%
- FrontierScience-Olympiad81%
- SWE-bench Multilingual72.7%
- SWE-bench Pro61.2%
- Humanity's Last Exam (with tools)55.1%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- 95.1 on GAIA and 92.0 on XBench-DS-2510 for long-horizon search at 35B
- 61.2 on SWE-bench Pro and 72.7 on SWE-bench Multilingual, up from 43.6 and 58.7 for Agents-A1
- Leads Kimi-K3, GLM-5.3 and GPT-5.6-sol on FrontierScience-Olympiad (81.0), FrontierScience-Research (48.3) and CMT (80.0) in the lab's table
- Parallel subagent orchestration that lifts BrowseComp from 81.7 to 82.8 and DeepResearch-Bench2 from 43.7 to 47.5
- Native 256K context, extendable to 512K with YaRN, and image input
- Apache 2.0 weights that serve on one GPU with vLLM or SGLang, plus FP8 and GGUF editions
Best for
- Reach for Sage-A1.5 as a self-hosted research agent that searches, reads and cross-checks sources over long runs.
- Reach for it for scientific work such as physics, chemistry and materials problems, where the lab's table shows it ahead of much larger models on FrontierScience and CMT.
- Reach for it as a local coding agent that fits on one GPU, with 61.2 on SWE-bench Pro in the lab's harness.
- Turn on agentic orchestration for deep-research tasks that split into parallel threads.
- Look to larger models such as GLM-5.3 or GPT-5.6-sol for the hardest coding and Humanity's Last Exam work, where they score higher in the same table.
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (weights) ↗ | InternScience/Sage-A1.5 |
| ModelScope (weights) ↗ | InternScience/Sage-A1.5 |
FAQ
What is Sage-A1.5?
A 35B Mixture-of-Experts agentic model from Shanghai AI Lab's InternScience team, released in October 2026 under Apache 2.0. It builds on Qwen3.6-35B-A3B and the lab's Agents-A1 and targets long-horizon scientific problem solving.
What does it add over Agents-A1?
The model card names three capabilities: agentic orchestration (parallel subagents with isolated contexts), agentic verification (checking progress and evidence and changing strategy) and open scientific discovery. In the lab's table SWE-bench Pro rises from 43.6 to 61.2, MLE-Lite from 43.9 to 65.2 and CritPt from 4.3 to 20.0.
How does it compare with larger models?
In the lab's table it trails Kimi-K3, GLM-5.3 and GPT-5.6-sol on most coding and search benchmarks, but leads all three on FrontierScience-Olympiad (81.0), FrontierScience-Research (48.3), CMT (80.0), IFBench (81.6) and PinchBench (90.0).
How long is the context window?
262,144 tokens natively. The model card shows how to extend it to 524,288 tokens with YaRN (factor 2.0) in vLLM or SGLang.
How do I run it?
Load InternScience/Sage-A1.5 with Hugging Face Transformers, or serve it with vLLM (vllm serve InternScience/Sage-A1.5 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder) or SGLang for an OpenAI-compatible endpoint. FP8 and GGUF editions are in the Hugging Face collection.