
What is vLLM?
vLLM is a library for running and serving large language models. It loads models from Hugging Face and exposes them either as a Python API for batch generation or as an OpenAI-compatible HTTP server. It sits in the Serving & Deployment category of the Models & Inference tools and is open-source, written in Python and licensed Apache-2.0.
Overview
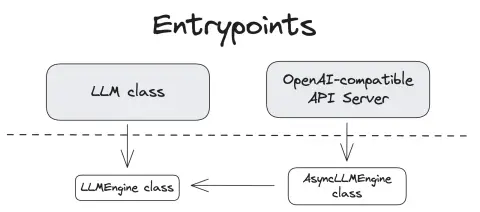
vLLM is a library for running and serving large language models. It loads models from Hugging Face and exposes them either as a Python API for batch generation or as an OpenAI-compatible HTTP server. It was originally developed in the Sky Computing Lab at UC Berkeley and is now maintained by a large open-source community.
It is built for teams that need to serve many requests at the same time without running out of GPU memory. Its PagedAttention technique manages the attention key/value cache more efficiently, and continuous batching keeps the GPU busy by adding and removing requests on the fly. It supports 200+ model architectures, including decoder-only LLMs, mixture-of-expert models, and multimodal models.
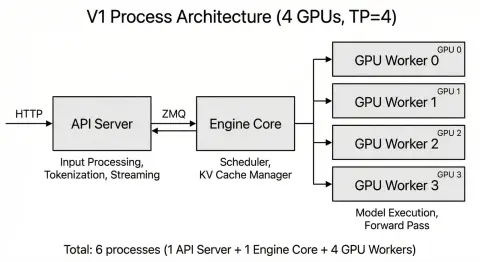
Within the inference and serving category, vLLM sits at the high-throughput serving end. You point it at a model, and it handles batching, memory management, streaming, and an API surface so you can focus on your application instead of the serving plumbing.
What it does
- PagedAttention manages attention key/value memory efficiently, reducing waste and fitting more concurrent requests in GPU memory
- Continuous batching, chunked prefill, and prefix caching keep throughput high under load
- OpenAI-compatible API server, plus Anthropic Messages API and gRPC support
- Wide quantization support including FP8, INT8, INT4, GPTQ/AWQ, and GGUF
- Tensor, pipeline, data, expert, and context parallelism for distributed inference
- Runs on NVIDIA and AMD GPUs, x86/ARM/PowerPC CPUs, and other hardware via plugins
Getting started
Install vLLM, then either generate text from Python or start an OpenAI-compatible server.
Install vLLM
Install with uv (recommended) or pip. A GPU with a matching CUDA setup is the common target.
uv pip install vllmRun offline batched inference
Load a model and generate text for a list of prompts directly in Python.
from vllm import LLM, SamplingParams

prompts = [
    "Hello, my name is",
    "The capital of France is",
]
sampling_params = SamplingParams(temperature=0.8, top_p=0.95)

llm = LLM(model="facebook/opt-125m")
outputs = llm.generate(prompts, sampling_params)

for output in outputs:
    print(output.prompt, output.outputs[0].text)
Start an OpenAI-compatible server
Serve a model over HTTP at http://localhost:8000 with chat and completion endpoints that match the OpenAI API.
vllm serve Qwen/Qwen2.5-1.5B-InstructCommands and code are distilled from the project's own documentation — always check the official repo for the latest.
When to use it
- Serving a chat or completion model to many users at once behind an OpenAI-compatible API
- Running high-volume offline batch generation over large prompt sets
- Hosting open-weight Hugging Face models on your own GPUs instead of a paid API
- Scaling a single large model across multiple GPUs with tensor or pipeline parallelism
Version history
Every verified update to vLLM that AI/TLDR tracked, newest first — each links to our coverage and the official changeset.
- 2026-11-01v0.33.0
Block-diffusion drafters (DFlash, DSpark) stop reserving draft slots, an opt-in lossy FLy verifier and a ROCm `--monokernel` decode path speed up generation, and a `/v1/decisions` endpoint lands. 927 commits from 389 contributors; release builds are now CUDA 13.0 only, and Medusa and the MLP speculator are removed.
- 2026-09-22v0.30.0
Fast Start adds a per-GPU weight-cache daemon, so a restarting engine maps post-quantized weights over CUDA IPC via `--load-format ipc_cache` instead of reloading from disk. 762 commits from 315 contributors also bring Gumbel-max watermarking, the HiSparse host-memory KV tier, and DeepSeek-V4.1-Flash and GLM-5.3-Flash support. Scale-out endpoints now need `--enable-scale-out`.
- 2026-09-09v0.29.0
Model Runner V2 becomes the default for all models, and ten deprecated architectures (Arctic, Chameleon, MPT and others) are removed. 594 commits from 277 contributors add Hy4-preview and Qwen3.8-Flash-Next support; `python -m vllm.entrypoints.openai.api_server` is deprecated in favour of `vllm serve`.
- 2026-08-26v0.28.0
vLLM v0.28.0 lands 584 commits from 270 contributors: a Kimi K3 speed push (decode context parallelism, fused kernels, expert sharding saving ~17 GiB per GPU) plus end-to-end sparse MLA for DeepSeek V4.
- 2026-04-27v0.20.0
752 commits from 320 contributors: DeepSeek V4 support, FlashAttention 4 as the default MLA prefill backend, TurboQuant 2-bit KV cache for 4x capacity, and CUDA 13 plus PyTorch 2.11 as defaults.
vLLM in the news
- 2026-11-01MAJORvLLM v0.33.0 — faster speculative decoding, and CUDA 13 builds only
- 2026-10-29MAJORMistral Large 4 open weights — Le Chonk lands on Hugging Face
- 2026-10-12NOTABLEIntel GPU D270 — an inference card with up to 480 GB of LPDDR5X
- 2026-09-22MAJORvLLM v0.30.0 — engine restarts skip the disk with a GPU weight cache
- 2026-09-20MAJORHemmingway-1 — a 27B open model tuned for everyday messages
- 2026-09-09MAJORvLLM v0.29.0 — Model Runner V2 becomes the default for every model
- 2026-09-08NOTABLECohere megakernel — one CUDA file serves North Mini Code faster than vLLM
- 2026-08-28MAJORGLM-5.3 weights go public — Z.ai's 753B coding model lands on Hugging Face
From the AI/TLDR release feed — every item is source-verified when it ships.
How vLLM compares
vLLM alongside other open-source serving & deployment tools AI/TLDR tracks, ranked by GitHub stars.
| Tool | Stars | What it does |
|---|---|---|
| Transformers | ★ 168k | Hugging Face Transformers is a Python framework that defines and runs state-of-the-art pretrained models for text, vision, audio, and multimodal tasks, for both inference and training. |
| vLLM | ★ 96.2k | Fast, memory-efficient inference and serving for large language models |
| SGLang | ★ 38.4k | A serving framework for LLMs and multimodal models that boosts throughput by reusing shared prompt prefixes across requests. |
| Modular Platform | ★ 30.1k | Modular's AI platform: the MAX inference framework with an OpenAI-compatible serving endpoint and GPU kernel library, plus the Mojo language and compiler. |
| DeepInfer | ★ 25k | DeepSeek's own large-scale inference framework for its models, with expert parallelism, confidence-scheduled speculative decoding and NVIDIA plus Ascend support. |
| TensorRT-LLM | ★ 15k | NVIDIA's library that compiles LLMs into optimized engines for the fastest inference on its data-center GPUs. |
| OpenLLM | ★ 12.6k | A tool to run any open-source LLM as an OpenAI-compatible API endpoint locally or in the cloud. |
| LMCache | ★ 12.3k | A KV-cache layer that stores and shares cached attention state across engines and requests to cut repeated computation. |