
Overview
ERNIE 5.5 Flash Base is an open-weight language model from Baidu, published on Hugging Face and ModelScope on November 5, 2026. It is a sparse Mixture-of-Experts model with 280B total parameters and 14B activated per token, pre-trained from scratch on 33.5 trillion tokens with a training context of up to 128K; fine-tuning and inference support a 1M-token context. It is a text-only model released in FP8 and BF16 safetensors.
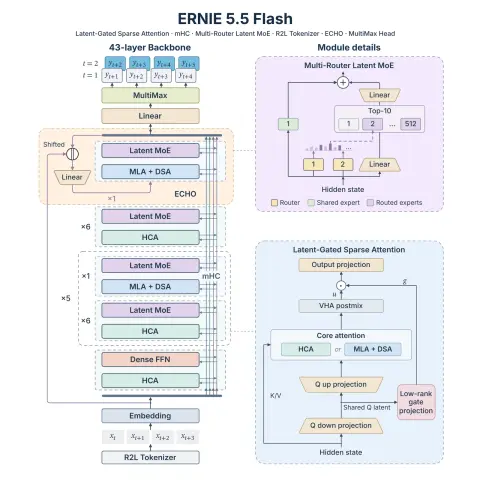
The architecture has 43 layers: one dense FFN layer and 42 Multi-Router Latent MoE layers, each with 512 routed experts (top-10) plus one shared expert. Attention is hybrid: 37 layers use Heavily Compressed Attention (HCA), which caches one entry per 128 tokens, and 6 layers use Multi-head Latent Attention with sparse attention (MLA + DSA). Baidu also describes Virtual Head Attention, an ECHO layer that reuses the backbone's final layer for multi-token prediction and as a speculative-decoding draft, manifold-constrained Hyper-Connections in place of the standard residual stream, a MultiMax output head and a ≈200K-entry BPE tokenizer that groups digits right-to-left. The model was trained with the Muon optimizer.
This is the checkpoint at the end of pre-training, before any mid- or post-training: it is not an instruction-tuned chat model and is served through the completions endpoint. Baidu positions it as a starting point for domain adaptation, instruction tuning and reinforcement-learning research, and says its pre-training data emphasizes repository-scale code and long-context understanding.
In Baidu's model card, evaluated with one pipeline against DeepSeek-V4-Flash-Base (284B-A13B), Hy3-preview-Base (295B-A21B) and MiMo-V2.5-Base (310B-A15B), it scores 93.3 on MMLU, 78.4 on MMLU-Pro, 60.2 on GPQA, 82.3 on HumanEval+ and 91.7 on RepoQA. It does not lead every row: DeepSeek-V4-Flash-Base is ahead on ChineseSimpleQA, INCLUDE-lite, HELMET-Rerank and InfiniteBench, and Hy3-preview-Base on BBH (CoT) and FullStackBench.
The weights are released under the ERNIE 5.5 Flash Base Model License Agreement v1.0. Non-commercial use is free; commercial use is free of model license charges for operators whose related annual revenue is at or below US$50 million, provided they display "Powered by ERNIE" and send Baidu a one-time use notice. Above that threshold, commercial use needs Baidu's separate written authorization.
| Released | 2026-11-05 |
|---|---|
| License | ERNIE 5.5 Flash Base Model License Agreement v1.0 |
| Weights | Open weights |
| Parameters | 280B total · 14B active |
| Context | 128K (max training) / 1M (fine-tuning & inference) |
| Architecture | Mixture-of-Experts, 43 layers (1 dense + 42 MoE), hybrid MLA + Heavily Compressed Attention |
| Modalities | Text |
| Status | Open weights (pre-trained base checkpoint, FP8 and BF16) on Hugging Face and ModelScope. Baidu's launch post states that a post-trained ERNIE 5.5 Flash will follow, with no date given at release. |
Benchmarks
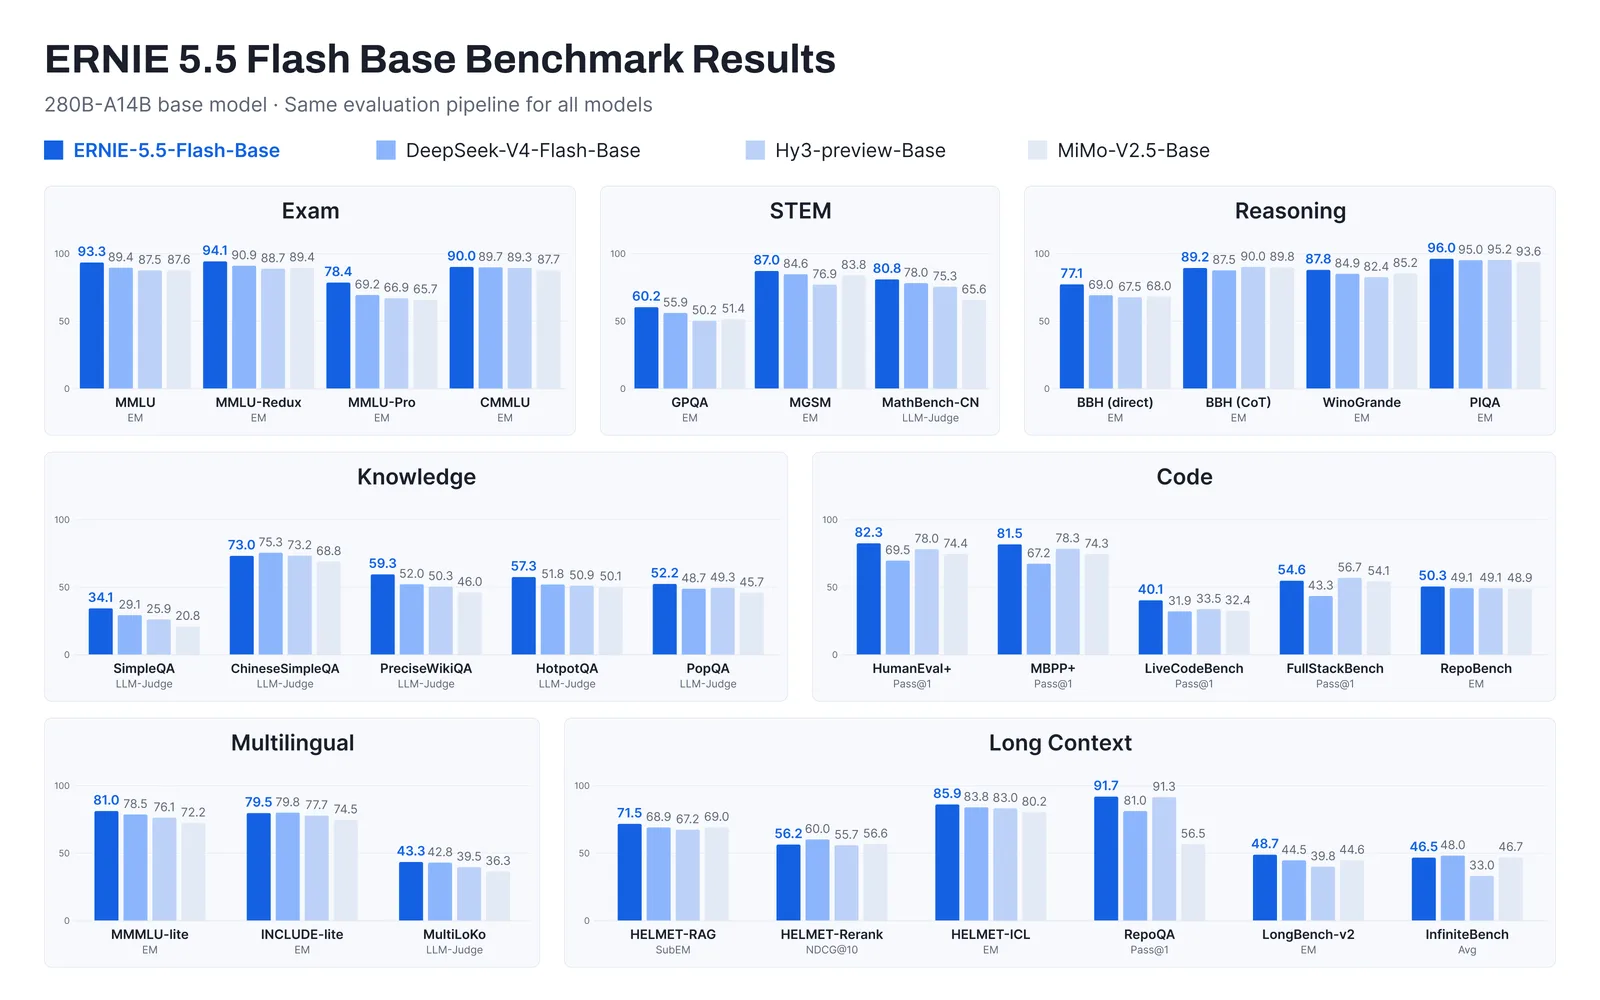
ERNIE 5.5 Flash Base against other open MoE base models, transcribed from Baidu's model card. All models evaluated with the same pipeline, prompts and few-shot settings.
| Benchmark | ERNIE-5.5-Flash-Base (280B-A14B) | DeepSeek-V4-Flash-Base (284B-A13B) | Hy3-preview-Base (295B-A21B) | MiMo-V2.5-Base (310B-A15B) |
|---|---|---|---|---|
| MMLU (5-shot) | 93.3 | 89.4 | 87.5 | 87.6 |
| MMLU-Redux (5-shot) | 94.1 | 90.9 | 88.7 | 89.4 |
| MMLU-Pro (5-shot) | 78.4 | 69.2 | 66.9 | 65.7 |
| CMMLU (5-shot) | 90 | 89.7 | 89.3 | 87.7 |
| SimpleQA (10-shot) | 34.1 | 29.1 | 25.9 | 20.8 |
| ChineseSimpleQA (10-shot) | 73 | 75.3 | 73.2 | 68.8 |
| PreciseWikiQA (10-shot) | 59.3 | 52 | 50.3 | 46 |
| HotpotQA (10-shot) | 57.3 | 51.8 | 50.9 | 50.1 |
| PopQA (10-shot) | 52.2 | 48.7 | 49.3 | 45.7 |
| GPQA (5-shot) | 60.2 | 55.9 | 50.2 | 51.4 |
| MGSM (8-shot CoT) | 87 | 84.6 | 76.9 | 83.8 |
| MathBench-CN (5-shot) | 80.8 | 78 | 75.3 | 65.6 |
| BBH direct (3-shot) | 77.1 | 69 | 67.5 | 68 |
| BBH CoT (3-shot) | 89.2 | 87.5 | 90 | 89.8 |
| WinoGrande (5-shot) | 87.8 | 84.9 | 82.4 | 85.2 |
| PIQA (5-shot) | 96 | 95 | 95.2 | 93.6 |
| MMMLU-lite (5-shot) | 81 | 78.5 | 76.1 | 72.2 |
| INCLUDE-lite (5-shot) | 79.5 | 79.8 | 77.7 | 74.5 |
| MultiLoKo (5-shot) | 43.3 | 42.8 | 39.5 | 36.3 |
| HumanEval+ (Pass@1) | 82.3 | 69.5 | 78 | 74.4 |
| MBPP+ (Pass@1) | 81.5 | 67.2 | 78.3 | 74.3 |
| LiveCodeBench (Pass@1) | 40.1 | 31.9 | 33.5 | 32.4 |
| FullStackBench (Pass@1) | 54.6 | 43.3 | 56.7 | 54.1 |
| RepoBench (EM) | 50.3 | 49.1 | 49.1 | 48.9 |
| HELMET-RAG (SubEM) | 71.5 | 68.9 | 67.2 | 69 |
| HELMET-Rerank (NDCG@10) | 56.2 | 60 | 55.7 | 56.6 |
| HELMET-ICL (many-shot) | 85.9 | 83.8 | 83 | 80.2 |
| RepoQA (Pass@1) | 91.7 | 81 | 91.3 | 56.5 |
| LongBench-v2 (EM) | 48.7 | 44.5 | 39.8 | 44.6 |
| InfiniteBench (Avg) | 46.5 | 48 | 33 | 46.7 |
This model's scores
- PIQA96%
- MMLU93.3%
- RepoQA91.7%
- CMMLU90%
- HumanEval+82.3%
- MMLU-Pro78.4%
- GPQA60.2%
- LongBench-v248.7%
- LiveCodeBench40.1%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- 280B-total / 14B-active MoE with a 1M-token context for fine-tuning and inference
- Released as a raw pre-trained base in FP8 and BF16, for custom instruction tuning and RL
- 93.3 MMLU, 78.4 MMLU-Pro and 82.3 HumanEval+ in Baidu's base-model comparison
- Day-one serving recipes for SGLang and vLLM (via the vLLM-ERNIE plugin)
Best for
- Reach for it as a starting checkpoint for domain adaptation, instruction tuning or reinforcement-learning research on a large open MoE.
- Reach for it for long-context and repository-scale code work when you plan to post-train the model yourself.
- Look elsewhere for a ready-to-use chat assistant or image input: this is a text-only base model with no instruction tuning.
FAQ
What is ERNIE 5.5 Flash Base?
ERNIE 5.5 Flash Base is an open-weight Mixture-of-Experts language model from Baidu, released on November 5, 2026. It has 280B total parameters with 14B active per token, was pre-trained on 33.5 trillion tokens, and supports a 1M-token context for fine-tuning and inference.
Is ERNIE 5.5 Flash Base a chat model?
No. It is the checkpoint at the end of pre-training, before any mid- or post-training, so it has no instruction tuning and is served through the completions endpoint. Baidu's launch post says a post-trained ERNIE 5.5 Flash will follow.
Can ERNIE 5.5 Flash Base be used commercially?
Under the ERNIE 5.5 Flash Base Model License Agreement v1.0, commercial use is free of model license charges when the operator's related annual revenue is at or below US$50 million, provided the product displays "Powered by ERNIE" and the operator sends Baidu a one-time use notice. Above US$50 million, separate written authorization from Baidu is required. Non-commercial use is free.
How do I run ERNIE 5.5 Flash Base?
Baidu's model card gives serving recipes for SGLang (a prebuilt Docker image and `sglang serve --model-path baidu/ERNIE-5.5-Flash-Base`) and for vLLM with the vLLM-ERNIE plugin (`vllm serve baidu/ERNIE-5.5-Flash-Base`). Both accept up to 1,048,576 tokens of context. Weights come in FP8 and BF16 on Hugging Face and ModelScope.
How does ERNIE 5.5 Flash Base compare with DeepSeek-V4-Flash-Base?
In Baidu's same-pipeline comparison it scores 78.4 vs 69.2 on MMLU-Pro, 82.3 vs 69.5 on HumanEval+ and 91.7 vs 81.0 on RepoQA. DeepSeek-V4-Flash-Base is ahead on ChineseSimpleQA (75.3 vs 73.0), INCLUDE-lite, HELMET-Rerank and InfiniteBench.