
Overview
Gemini 3.8 Flash-Lite TTS is the lower-cost text-to-speech model Google released on 23 September 2026 alongside Gemini 3.8 Flash TTS. It is served in the Gemini API as `gemini-3.8-flash-lite-tts`. Google describes it as "built for high-volume, cost-efficient scale", and points it at dubbing and voice agents.
It shares the voice system of the Flash model. The speech-generation docs list the prebuilt studio voices, an Extended Voice Library (Google's post counts more than 2,000 production-ready voices), voice design from a natural-language description, and voice replication from a 30-second sample after a recorded consent check. A single request can stage two speakers with prebuilt voices. The docs list 101 supported languages, against 130 for Flash TTS.
Every clip carries an imperceptible SynthID watermark, and replicated voices get C2PA content credentials. Google says voice replication is not available in Illinois, Texas, the EEA, the UK, Switzerland or India.
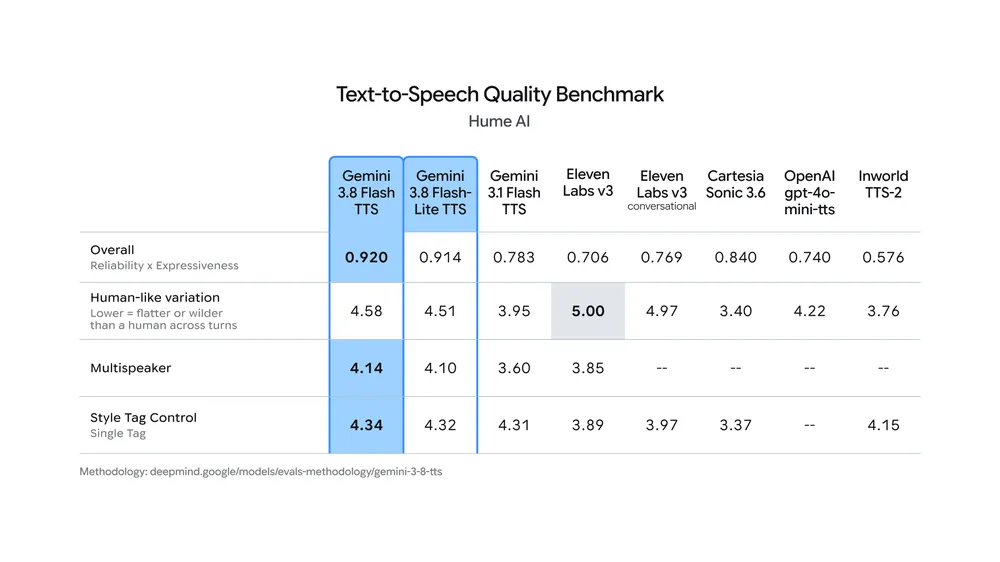
In the benchmark tables Google published at launch, Flash-Lite TTS scores 0.914 overall on Hume AI's text-to-speech quality benchmark, just behind Flash TTS at 0.920 and ahead of Cartesia Sonic 3.6 at 0.840. On the Voice Arena leaderboard it leads in English (1087), Brazilian Portuguese (1134) and Vietnamese (1156).
At launch it is available in the Gemini API, Google AI Studio and Google Vids, with the Gemini Enterprise API listed as coming soon. Launch pricing in the Gemini API is $0.50 per 1M text input tokens and $6.00 per 1M audio output tokens through 31 December 2026, rising to $1.00 and $12.00 from 1 January 2027; a free tier is also listed.
| Released | 2026-09-23 |
|---|---|
| License | Proprietary |
| Weights | API only |
| Parameters | Not disclosed |
| Modalities | Text, Audio |
| Status | Generally available |
Benchmarks
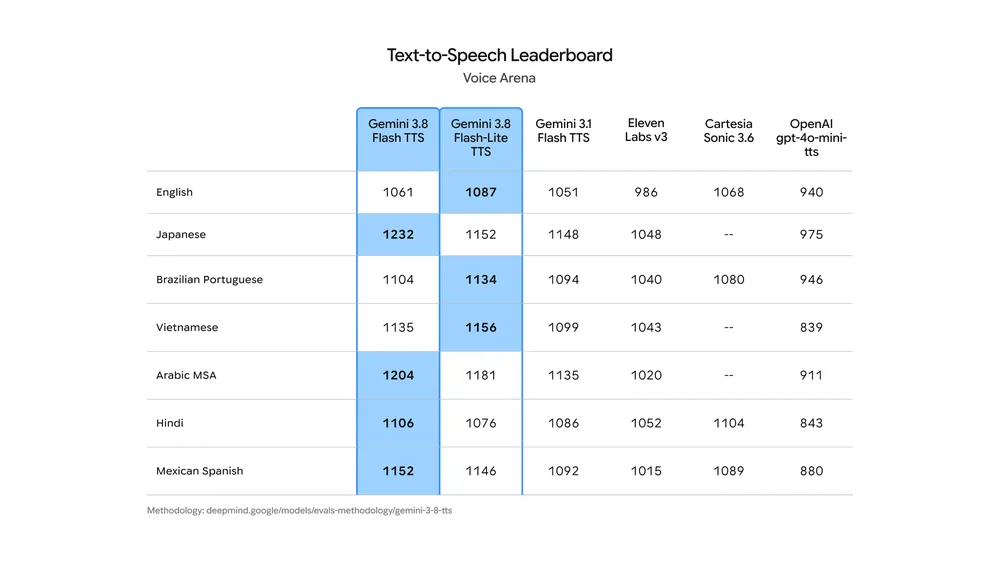
Voice Arena text-to-speech leaderboard ratings by language, as published by Google at launch (23 September 2026). Higher is better; a null cell was not reported.
| Benchmark | Gemini 3.8 Flash TTS | Gemini 3.8 Flash-Lite TTS | Gemini 3.1 Flash TTS | ElevenLabs v3 | Cartesia Sonic 3.6 | OpenAI gpt-4o-mini-tts |
|---|---|---|---|---|---|---|
| English | 1061 | 1087 | 1051 | 986 | 1068 | 940 |
| Japanese | 1232 | 1152 | 1148 | 1048 | — | 975 |
| Brazilian Portuguese | 1104 | 1134 | 1094 | 1040 | 1080 | 946 |
| Vietnamese | 1135 | 1156 | 1099 | 1043 | — | 839 |
| Arabic (MSA) | 1204 | 1181 | 1135 | 1020 | — | 911 |
| Hindi | 1106 | 1076 | 1086 | 1052 | 1104 | 843 |
| Mexican Spanish | 1152 | 1146 | 1092 | 1015 | 1089 | 880 |
Pricing
| Input | $0.50 / 1M tokens |
|---|---|
| Output | $6.00 / 1M tokens |
Text input / audio output launch rates for gemini-3.8-flash-lite-tts through 31 December 2026; from 1 January 2027 the list price is $1.00 / $12.00. Batch is half ($0.25 / $3.00 at launch rates). A free tier is listed.
Strengths
- 0.914 overall on Hume AI's text-to-speech quality benchmark in Google's published table, second only to Gemini 3.8 Flash TTS (0.920) and ahead of Cartesia Sonic 3.6 (0.840)
- Top Voice Arena rating in English (1087), Brazilian Portuguese (1134) and Vietnamese (1156) in Google's launch table
- $6.00 per 1M audio output tokens at launch rates, against $9.00 for Flash TTS
- Voice design from a written description and voice replication from a 30-second sample, gated by a recorded consent check
- 101 languages and 2,000+ ready-made voices, with two-speaker scenes in a single request
- SynthID watermark on every clip, plus C2PA content credentials on replicated voices
Best for
- Reach for it for dubbing large volumes of video or audio content into many languages
- Reach for it for voice agents, where cost per spoken minute matters more than line-by-line direction
- Reach for it for English, Brazilian Portuguese or Vietnamese speech, where it tops Google's Voice Arena table
- Reach for Gemini 3.8 Flash TTS instead when a performance needs detailed creative direction or one of its 130 languages
How to access

| Provider | Model ID |
|---|---|
| Gemini API (Google AI Studio) ↗ | gemini-3.8-flash-lite-tts |
Gemini TTS (text-to-speech) — every version
The full lineage of the Gemini TTS (text-to-speech) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Gemini 3.8 Flash TTScurrent | 2026-09-23 | — | Proprietary |
| Gemini 3.8 Flash-Lite TTS | 2026-09-23 | — | Proprietary |
FAQ
What is Gemini 3.8 Flash-Lite TTS?
Gemini 3.8 Flash-Lite TTS is a text-to-speech model Google released on 23 September 2026 and serves in the Gemini API as gemini-3.8-flash-lite-tts. Google built it for high-volume, cost-efficient speech such as dubbing and voice agents.
How does it differ from Gemini 3.8 Flash TTS?
It covers 101 languages rather than 130 and costs $6.00 rather than $9.00 per 1M audio output tokens at launch rates. In Google's Hume AI quality table it scores 0.914 overall against 0.920 for Flash TTS, and it tops the Voice Arena table in English, Brazilian Portuguese and Vietnamese.
Can it design or clone voices?
Yes. It shares the Flash model's voice options: prebuilt voices, an extended library of more than 2,000 voices, voice design from a text description, and voice replication from a 30-second sample after a recorded consent check. Replication is not offered in Illinois, Texas, the EEA, the UK, Switzerland or India.
What does it cost?
The Gemini API pricing page lists $0.50 per 1M text input tokens and $6.00 per 1M audio output tokens through 31 December 2026, and $1.00 / $12.00 from 1 January 2027. Batch runs at half price, and a free tier is listed.
Where can I use it?
At launch it is available in the Gemini API, Google AI Studio and Google Vids, with the Gemini Enterprise API listed as coming soon.