Overview
Hemmingway-1 is a 27B-parameter model from Hemmingway, published on Hugging Face under the Altworld organisation on September 20, 2026. It is built on Qwen3.8-27B and tuned for the writing people do every day: text messages, emails, the awkward note to a colleague. The model card's pitch is that when you ask for a text to your landlord you get the text, not three options, a preamble and notes about the options.
The weights were first posted under Apache-2.0 and relicensed on September 22, 2026 to CC BY-NC 4.0: free for personal, research and other non-commercial use, with commercial use by separate agreement. The model card lists a 262,144-token context and gives vLLM and Transformers recipes for running it locally.
Hemmingway also serves the model itself. The hosted API is OpenAI-compatible at https://hemmingway.io/v1 under the model id hemmingway-27b, accepts image parts as well as text, has thinking switched on by default, and caps a reply at 32,768 tokens including thinking. There are web, desktop and mobile apps alongside it.
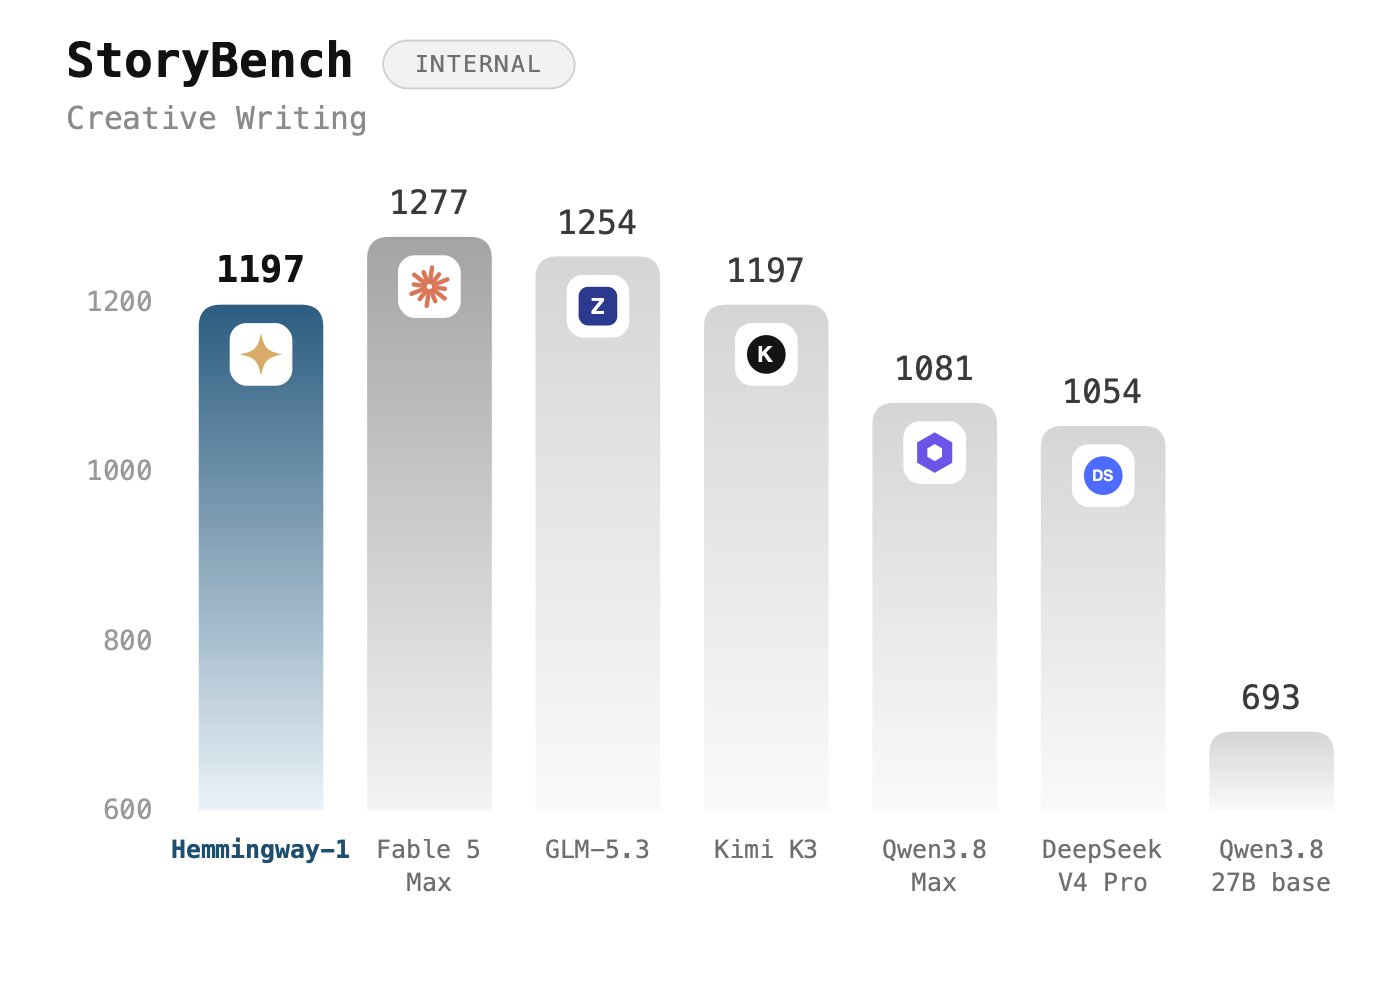
Three of the benchmarks on the model card (CommunicationBench, Human-Likeness and StoryBench) are Hemmingway's own, and the card says so: blind pairwise matchups run in both orders, judged by a model that was not one of the contestants. The fourth, EQ-Bench 4, is the public emotional-intelligence benchmark, where Hemmingway reports a third-place score of 1330.
| Released | 2026-09-20 |
|---|---|
| License | CC BY-NC 4.0 (commercial use by agreement) |
| Weights | Open weights |
| Parameters | 27B |
| Context | 262,144 tokens |
| Max output | 32,768 tokens on the hosted API (thinking included) |
| Architecture | Fine-tune of Qwen3.8-27B |
| Modalities | Text, Vision |
| Status | Generally available |
Benchmarks
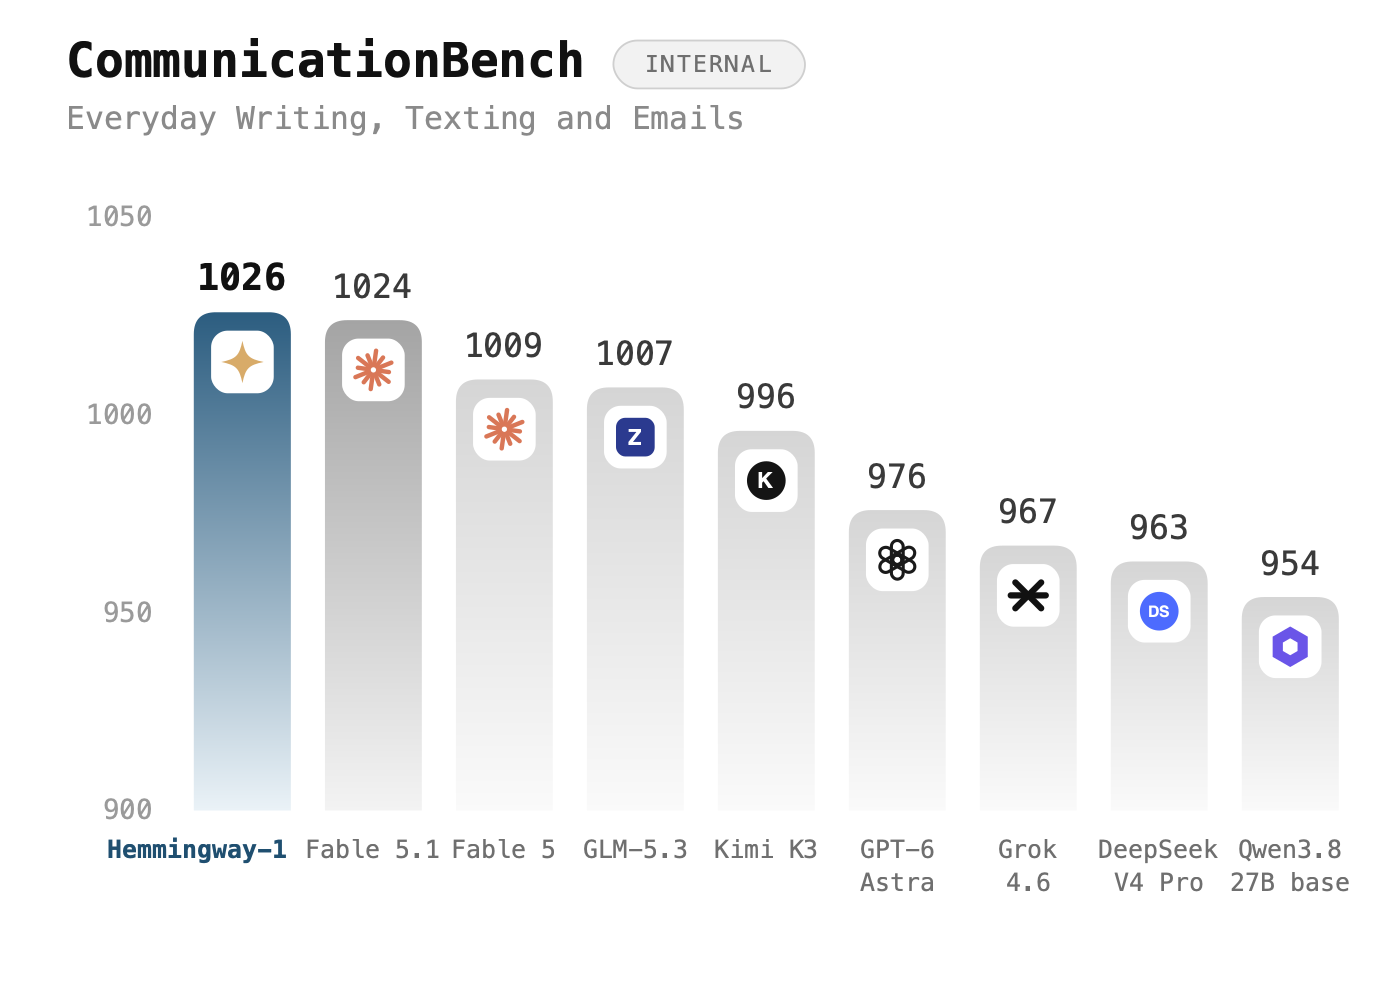
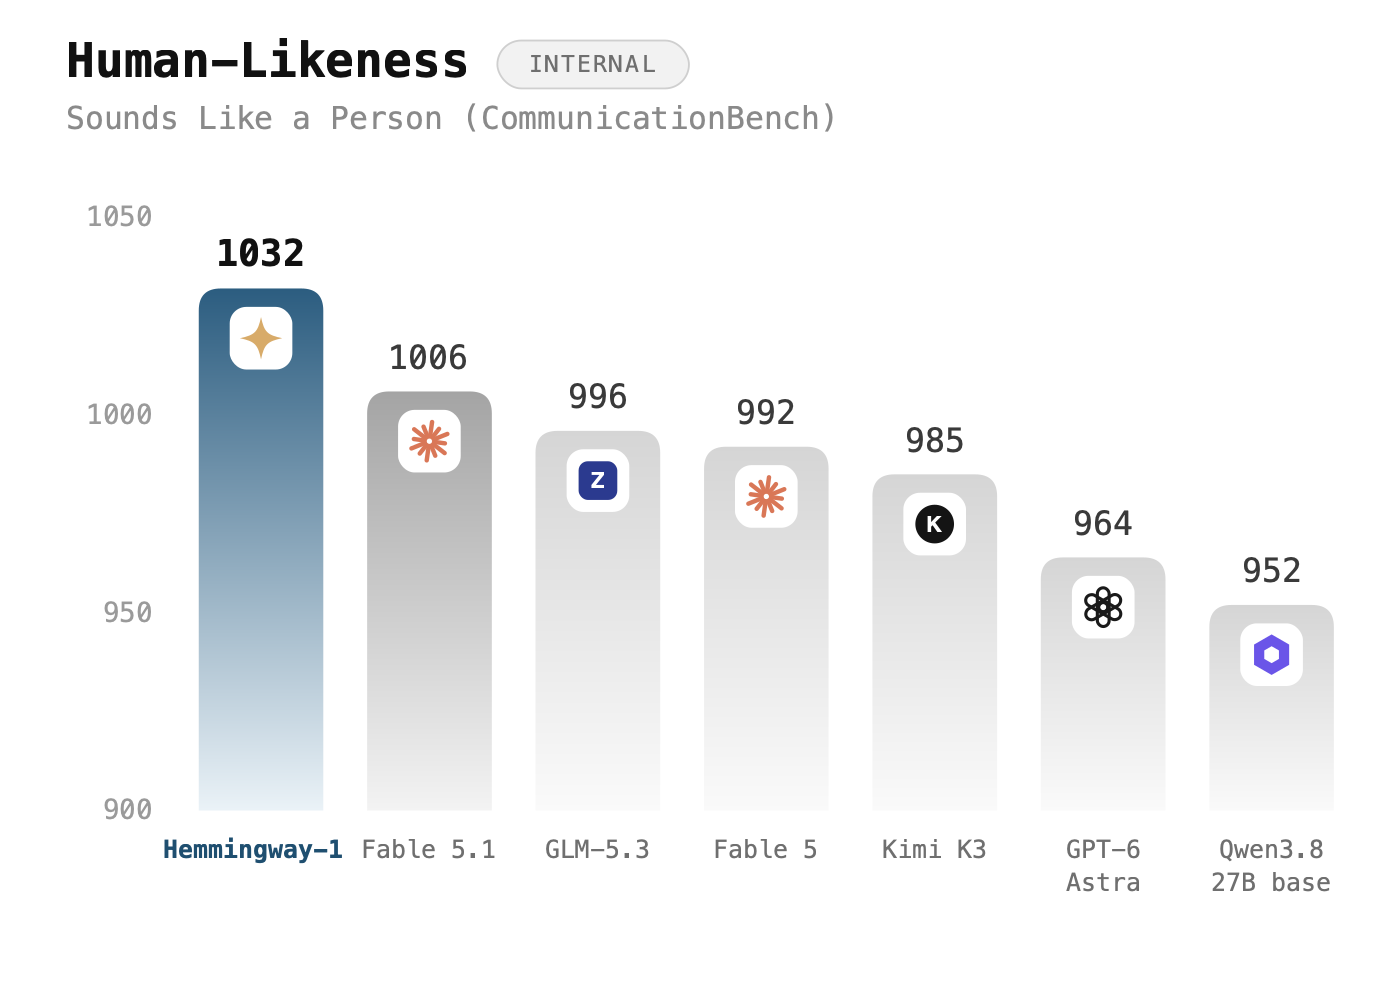
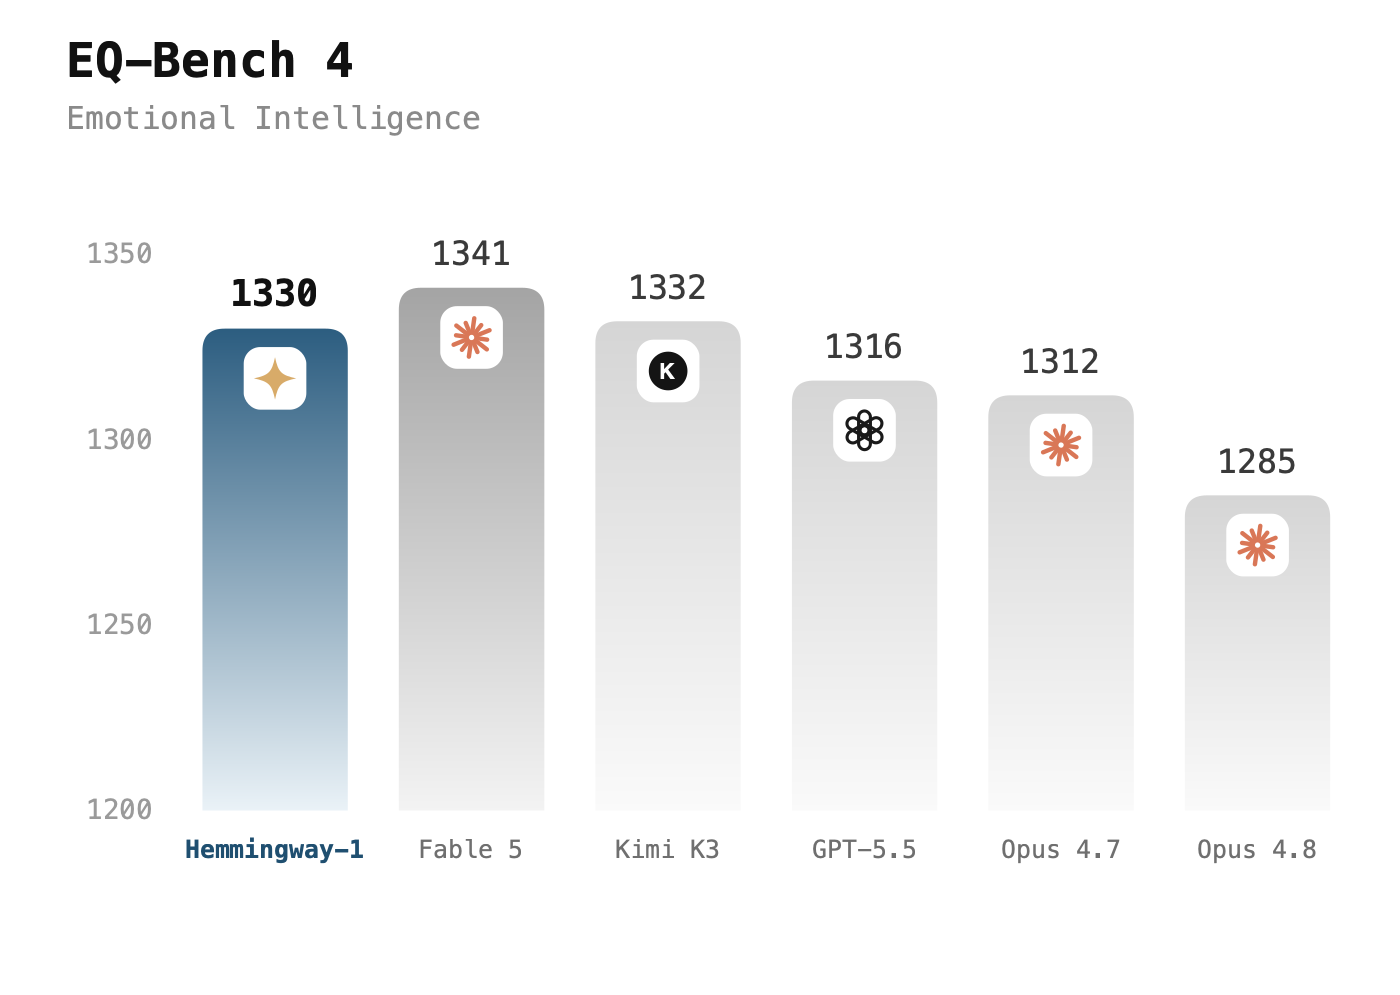
Hemmingway-1 against the models on its own model card. CommunicationBench and Human-Likeness are Hemmingway's internal benchmarks; EQ-Bench 4 is public.
| Benchmark | Hemmingway-1 | Fable 5.1 | Fable 5 | GLM-5.3 | Kimi K3 | GPT-6 Astra | Grok 4.6 | DeepSeek V4 Pro | Qwen3.8 27B (base) |
|---|---|---|---|---|---|---|---|---|---|
| CommunicationBench (everyday writing, internal) | 1026 | 1024 | 1009 | 1007 | 996 | 976 | 967 | 963 | 954 |
| Human-Likeness (internal) | 1032 | 1006 | 992 | 996 | 985 | 964 | — | — | 952 |
| Replies wrapped in commentary (lower is better, internal) | 39% | 67% | 93% | 93% | 92% | 4% | 22% | — | 19% |
| EQ-Bench 4 (public) | 1330 | — | 1341 | — | 1332 | — | — | — | — |
Pricing
| Input | $0.24 / 1M tokens |
|---|---|
| Cached input | $0.024 / 1M tokens |
| Output | $0.90 / 1M tokens |
Hosted hemmingway-27b API; the open weights are free for non-commercial use.
Strengths
- Tops Hemmingway's own CommunicationBench of 80 everyday writing requests at 1026, ahead of Fable 5.1 (1024), GLM-5.3 (1007), Kimi K3 (996) and GPT-6 Astra (976)
- Scores 1032 on the Human-Likeness rerun of those matchups, 26 points clear of Fable 5.1 at 1006
- Wraps 39% of replies in commentary or options, against 93% for Fable 5 and GLM-5.3 and 92% for Kimi K3 in the same test
- 1330 on the public EQ-Bench 4, above GPT-5.5 (1316), Opus 4.7 (1312) and Opus 4.8 (1285)
- Open weights with a 262,144-token context, plus an OpenAI-compatible hosted API that also reads images
Best for
- Reach for it when you need a message, email or reply drafted in a natural voice rather than a list of options with commentary.
- Reach for it when you want a self-hostable 27B writing model for personal or research use under a non-commercial licence.
- Reach for it when an app already speaks the OpenAI Chat Completions format and you want to swap in a writing-tuned model by changing the base URL and model id.
- Look elsewhere for adversarial storytelling and long story turns, where the model card's own category breakdown shows it losing to the story-focused models.
How to access
| Provider | Model ID |
|---|---|
| Hemmingway API ↗ | hemmingway-27b |
| Hugging Face (weights) ↗ | Altworld/Hemmingway-1 |
FAQ
What is Hemmingway-1 built on?
Hemmingway-1 is a 27B-parameter fine-tune of Qwen3.8-27B, tuned for everyday writing such as messages, emails and notes to colleagues. The model card lists a 262,144-token context.
Can I use Hemmingway-1 commercially?
Not without an agreement. The weights are licensed CC BY-NC 4.0, which allows personal, research and other non-commercial use with credit; commercial use needs a separate agreement with Hemmingway. The weights were briefly posted under Apache-2.0 on release day and relicensed on September 22, 2026.
How much does the Hemmingway-1 API cost?
The hosted API charges $0.24 per million input tokens, $0.024 per million cached input tokens and $0.90 per million output tokens. It is OpenAI-compatible at https://hemmingway.io/v1 with the model id hemmingway-27b, and a reply is capped at 32,768 tokens including thinking.
How does Hemmingway-1 compare with larger models?
On Hemmingway's own CommunicationBench it scores 1026, ahead of Fable 5.1 (1024), GLM-5.3 (1007), Kimi K3 (996) and GPT-6 Astra (976). On the public EQ-Bench 4 it scores 1330, behind Fable 5 (1341) and Kimi K3 (1332). On the internal StoryBench it ties Kimi K3 at 1197, below Fable 5 Max and GLM-5.3.