Overview
Index-Translate-35B-A3B-preview is the largest text model in Index-Translate, a family of multilingual translation models from Bilibili's Index LLM team. It is a Mixture-of-Experts model with 35B total and 3B active parameters, built on Qwen3.5, and it translates text across 150 languages. The team released it on September 30, 2026 alongside 2B and 9B siblings, a technical report and an online demo, with weights on Hugging Face and ModelScope under the Apache 2.0 license. It is labelled a preview: the project's to-do list still has an official version of the 35B-A3B model as an open item.
Beyond plain translation of sentences, articles and subtitles, the model is trained to follow translation instructions. The model card splits these into hard constraints (enforced glossaries, preserving JSON, CSV and markdown structure, code blocks and placeholders such as {variable}) and soft constraints (tone such as formal, casual or social-media style, and disambiguating a term's sense from its domain). It also targets social and cultural language: community aliases, playful spellings, memes and other nonliteral expressions.
Training starts from a shared multilingual mid-training recipe of 167.77B tokens that mixes general text, monolingual text, parallel translations and pivot-organised multilingual groups. Specialist models for general translation, instruction following and meme translation then get their own SFT and reinforcement learning (XCOMET-XXL plus language-validity and adequacy judgments for translation, Rubric-as-Reward for instructions), and the specialists are combined by parameter interpolation followed by multi-teacher on-policy distillation (MOPD) for task types that stay weak after merging.
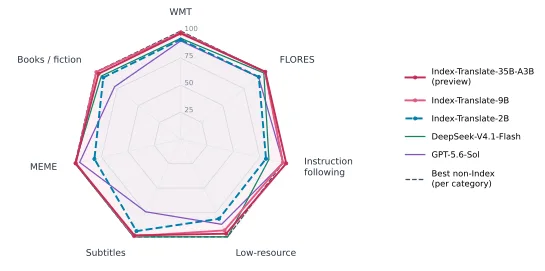
In the technical report's main table, the 35B-A3B preview has the highest FLORES COMET-22 (0.8794) and instTrans IFscore (0.8336) of all compared systems, which include Hy-MT2-30B-A3B, TranslateGemma-12B, Qwen3.5-35B-A3B, DeepSeek-V4.1-Flash, GPT-5.6-Sol and Gemini 3.5 Flash Lite. GPT-5.6-Sol leads on the WMT26 Judge score (89.10 against 76.76) and IFMTBench IFscore, and Hy-MT2-30B-A3B leads on WMT24++ and IFMTBench XCOMET-XXL. On low-resource directions (FLORES_minor_pair, 62 languages) it scores 0.8168 COMET-22 with 2.4% of outputs in the wrong language.
The model is served with vLLM or another OpenAI-compatible server that supports Qwen3.5 MoE; the card's example runs vllm serve with a 32,768-token context, greedy decoding and thinking disabled, and the project's translate.py client adds flags for glossaries, hard and soft constraints and genre. On October 3, 2026 the team published GGUF, FP8 and NVFP4 builds, and on October 4, 2026 a free OpenAI-compatible public API for the 35B-A3B model at index-translate.bilibili.com.
| Released | 2026-09-30 |
|---|---|
| License | Apache-2.0 |
| Weights | Open weights |
| Parameters | 35B total · 3B active |
| Context | 262,144 tokens (max_position_embeddings in the shipped config); the card's vLLM example serves 32,768 |
| Architecture | Mixture-of-Experts transformer built on Qwen3.5 (Qwen3.5 MoE architecture), translation-specialised through multilingual mid-training, specialist SFT and RL, expert interpolation and multi-teacher on-policy distillation |
| Modalities | Text |
| Status | Preview |
Benchmarks
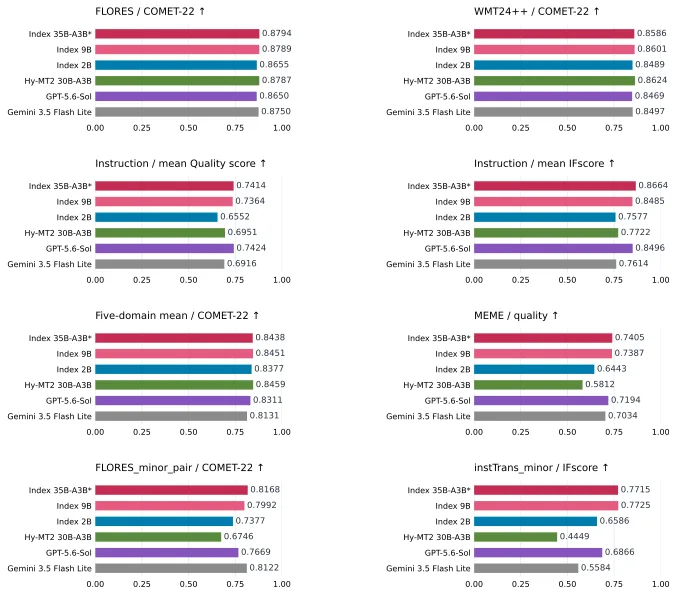
Index-Translate-35B-A3B-preview against its siblings, similarly sized MoE models and larger translation models and APIs, from the technical report's main table as reproduced on the model card. WMT26 Judge is 0–100; every other column is 0–1. Higher is better.
| Benchmark | Index-Translate-35B-A3B (preview) | Index-Translate-9B | Index-Translate-2B | Hy-MT2-30B-A3B | TranslateGemma-12B | North-Small-Translate (218B-A25B) | Qwen3.5-35B-A3B | DeepSeek-V4.1-Flash | GPT-5.6-Sol | Gemini 3.5 Flash Lite |
|---|---|---|---|---|---|---|---|---|---|---|
| FLORES COMET-22 | 0.8794 | 0.8789 | 0.8655 | 0.8787 | 0.8732 | 0.8784 | 0.857 | 0.8762 | 0.865 | 0.875 |
| WMT24++ COMET-22 | 0.8586 | 0.8601 | 0.8489 | 0.8624 | 0.8524 | 0.8578 | 0.829 | 0.851 | 0.8469 | 0.8497 |
| WMT26 Judge (0–100) | 76.76 | 75.35 | 60.26 | 66.81 | 71.19 | 68.37 | 71.33 | 83.55 | 89.1 | 79.52 |
| instTrans Quality | 0.6901 | 0.6771 | 0.5391 | 0.5725 | 0.4515 | 0.5697 | 0.369 | 0.6068 | 0.6902 | 0.6068 |
| instTrans IFscore | 0.8336 | 0.8209 | 0.7569 | 0.6415 | 0.3068 | 0.5294 | 0.5204 | 0.6374 | 0.7624 | 0.6374 |
| IFMTBench XCOMET-XXL | 0.7926 | 0.7957 | 0.7712 | 0.8177 | 0.8023 | 0.7657 | 0.7589 | 0.7817 | 0.7946 | 0.7764 |
| IFMTBench IFscore | 0.8991 | 0.876 | 0.7584 | 0.9029 | 0.2892 | 0.8635 | 0.7822 | 0.909 | 0.9367 | 0.8854 |
| Vertical mean (5 domains) | 0.8438 | 0.8451 | 0.8377 | 0.8459 | 0.8347 | 0.8357 | 0.8267 | 0.8432 | 0.8311 | 0.8131 |
| MEME | 0.7405 | 0.7387 | 0.6443 | 0.5812 | 0.4281 | 0.6836 | 0.6447 | 0.7424 | 0.7194 | 0.7034 |
This model's scores
- FLORES COMET-220.8794
- WMT24++ COMET-220.8586
- instTrans IFscore0.8336
- WMT26 Judge76.76
- MEME0.7405
- C-Eval77.6%
- MMMLU71.9%
- GPQA Diamond49.1%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- Open weights under Apache 2.0, with only 3B of 35B parameters active per token
- Text translation across 150 languages
- Follows glossary, format-preservation, placeholder and style instructions in a canonical instTrans prompt format
- Highest FLORES COMET-22 (0.8794) and instTrans IFscore (0.8336) among all systems in the technical report
- Low-resource FLORES_minor_pair COMET-22 of 0.8168 with a 2.4% off-target rate
- Official GGUF, FP8 and NVFP4 builds plus a free OpenAI-compatible public API
Best for
- Reach for it for self-hosted translation of articles, subtitles and UI strings where a glossary must be enforced word for word.
- Reach for it for translating structured content (JSON, CSV, markdown, code with placeholders) without breaking the structure.
- Reach for it for social-media and community text full of memes, aliases and slang, which the MEME benchmark targets.
- Look elsewhere for speech, syllable-count-controlled dubbing or full-document translation: the family's Index-Echo, Index-Homura and Index-NativeLong models cover those, and the card points to them.
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (weights) ↗ | IndexTeam/Index-Translate-35B-A3B-preview |
| ModelScope (weights) ↗ | IndexTeam/Index-Translate-35B-A3B-preview |
| Index-Translate public API (OpenAI-compatible) ↗ | Index-Translate-35B-A3B |
FAQ
What is Index-Translate-35B-A3B-preview?
It is an open-weight translation model from Bilibili's Index LLM team: a Mixture-of-Experts model with 35B total and 3B active parameters, built on Qwen3.5, that translates text across 150 languages and follows terminology, formatting and style instructions. It was released as a preview on September 30, 2026 under the Apache 2.0 license.
How does it compare with GPT-5.6-Sol and DeepSeek-V4.1-Flash?
In the technical report's main table it leads both on FLORES COMET-22 (0.8794 against 0.8650 and 0.8762) and instTrans IFscore (0.8336 against 0.7624 and 0.6374). GPT-5.6-Sol scores higher on the WMT26 Judge (89.10 against 76.76) and IFMTBench IFscore (0.9367 against 0.8991), and DeepSeek-V4.1-Flash is slightly higher on MEME (0.7424 against 0.7405).
What kinds of translation instructions does it follow?
Hard constraints such as an enforced glossary, keeping JSON, CSV or markdown structure, code blocks and placeholders like {variable} intact; and soft constraints such as a formal, casual or social-media tone, or picking the right sense of a term for its domain.
How do I run it?
Serve it with a vLLM build that supports Qwen3.5 (the card's example is vllm serve IndexTeam/Index-Translate-35B-A3B-preview --max-model-len 32768) and call the OpenAI-compatible endpoint with temperature 0 and thinking disabled, or use the translate.py client from the bilibili/Index-Translate GitHub repository. GGUF, FP8 and NVFP4 builds are also published, and a free OpenAI-compatible API is available at index-translate.bilibili.com.
Why is it called a preview?
The model card says all 35B-A3B results refer to the preview model evaluated in the technical report, and the project's GitHub to-do list still includes releasing the official version of Index-Translate-35B-A3B.