
Overview
Ling-3.1-flash is a language model from inclusionAI, the team behind Ant Group's artificial-general-intelligence programme. Ant Ling announced it on 30 September 2026 as a model of about 560 billion total parameters with about 25 billion activated per token and a context window of up to 1 million tokens. It is the successor in the Ling line to Ling-3.0-flash, a 124B model with 5.1B active parameters, so it is several times larger in both total and active parameters.
Unlike earlier Ling releases, Ling-3.1-flash did not ship with downloadable weights. It launched as a free hosted trial, including on OpenRouter as inclusionai/ling-3.1-flash, and TechNode reported that inclusionAI planned to release it as open source after the trial. In October 2026 inclusionAI published the weights on Hugging Face under the MIT License: the instruct model as inclusionAI/Ling-3.1-flash, the pre-training checkpoint as Ling-3.1-flash-base, and an upgraded post-trained checkpoint as Ling-3.1-flash-1019. The model card recommends SGLang or vLLM for serving, on eight H200 GPUs or four GB300s.
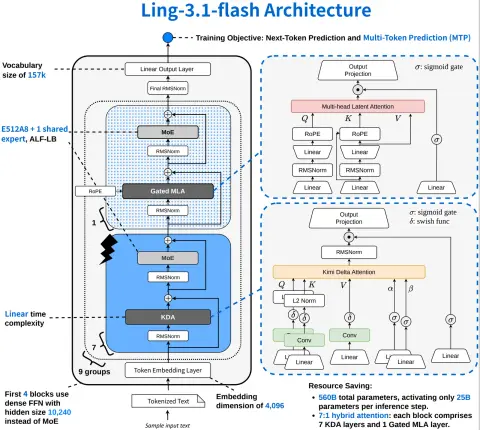
The model card describes a hybrid-linear Mixture-of-Experts. Each block stacks seven Kimi Delta Attention (KDA) layers, which run in linear time, with one Gated Multi-head Latent Attention layer, for 63 KDA and 9 Gated MLA layers in total. The first four layers use a dense feed-forward network; the rest route each token to 8 of 512 experts plus one shared expert. It has a 157,184-token vocabulary and is trained with next-token and multi-token prediction.
Ling-3.1-flash-1019 is the same 560B / 25B-active model with further post-training aimed at science and real-world agent tasks. inclusionAI's model card reports its AA-Briefcase score rising from 1,397 to 1,524, AutomationBench-AA from 62% to 68%, CritPt from 18% to 26% and SciCode from 54% to 57%, and a score of 44 on the Artificial Analysis Intelligence Index v4.3.2, up from 41 for the original checkpoint.
Ant Ling positions the model across work, coding and healthcare. Its launch post headlines 1,673 Elo on GDPval-AA v2.1, 75.16 on FrontierSWE and 65.35 on HealthBench Professional, and its published chart sets Ling-3.1-flash against GPT-5.6 Sol, Claude Opus 5, Kimi K3, GLM 5.3, GLM 5.3 flash and DeepSeek-V4.1-Flash on twelve benchmarks spanning agentic work, terminal and software engineering, cybersecurity, finance, healthcare and multi-turn instruction following. Ant Ling notes that HealthBench Professional was evaluated in its AQ environment, and that Ling-3.1-flash's healthcare capabilities can only be experienced in AQ.
| Released | 2026-09-30 |
|---|---|
| License | MIT |
| Weights | Open weights |
| Parameters | 560B total · 25B activated per token (Mixture-of-Experts) |
| Context | 1M tokens |
| Max output | 262,144 tokens (OpenRouter, Novita endpoint) |
| Architecture | Hybrid-linear Mixture-of-Experts: 63 Kimi Delta Attention + 9 Gated MLA layers (7:1), 512 routed experts with 8 active plus 1 shared |
| Modalities | Text |
| Status | Open weights (MIT) on Hugging Face; launched 30 September 2026 as a free hosted trial |
Benchmarks
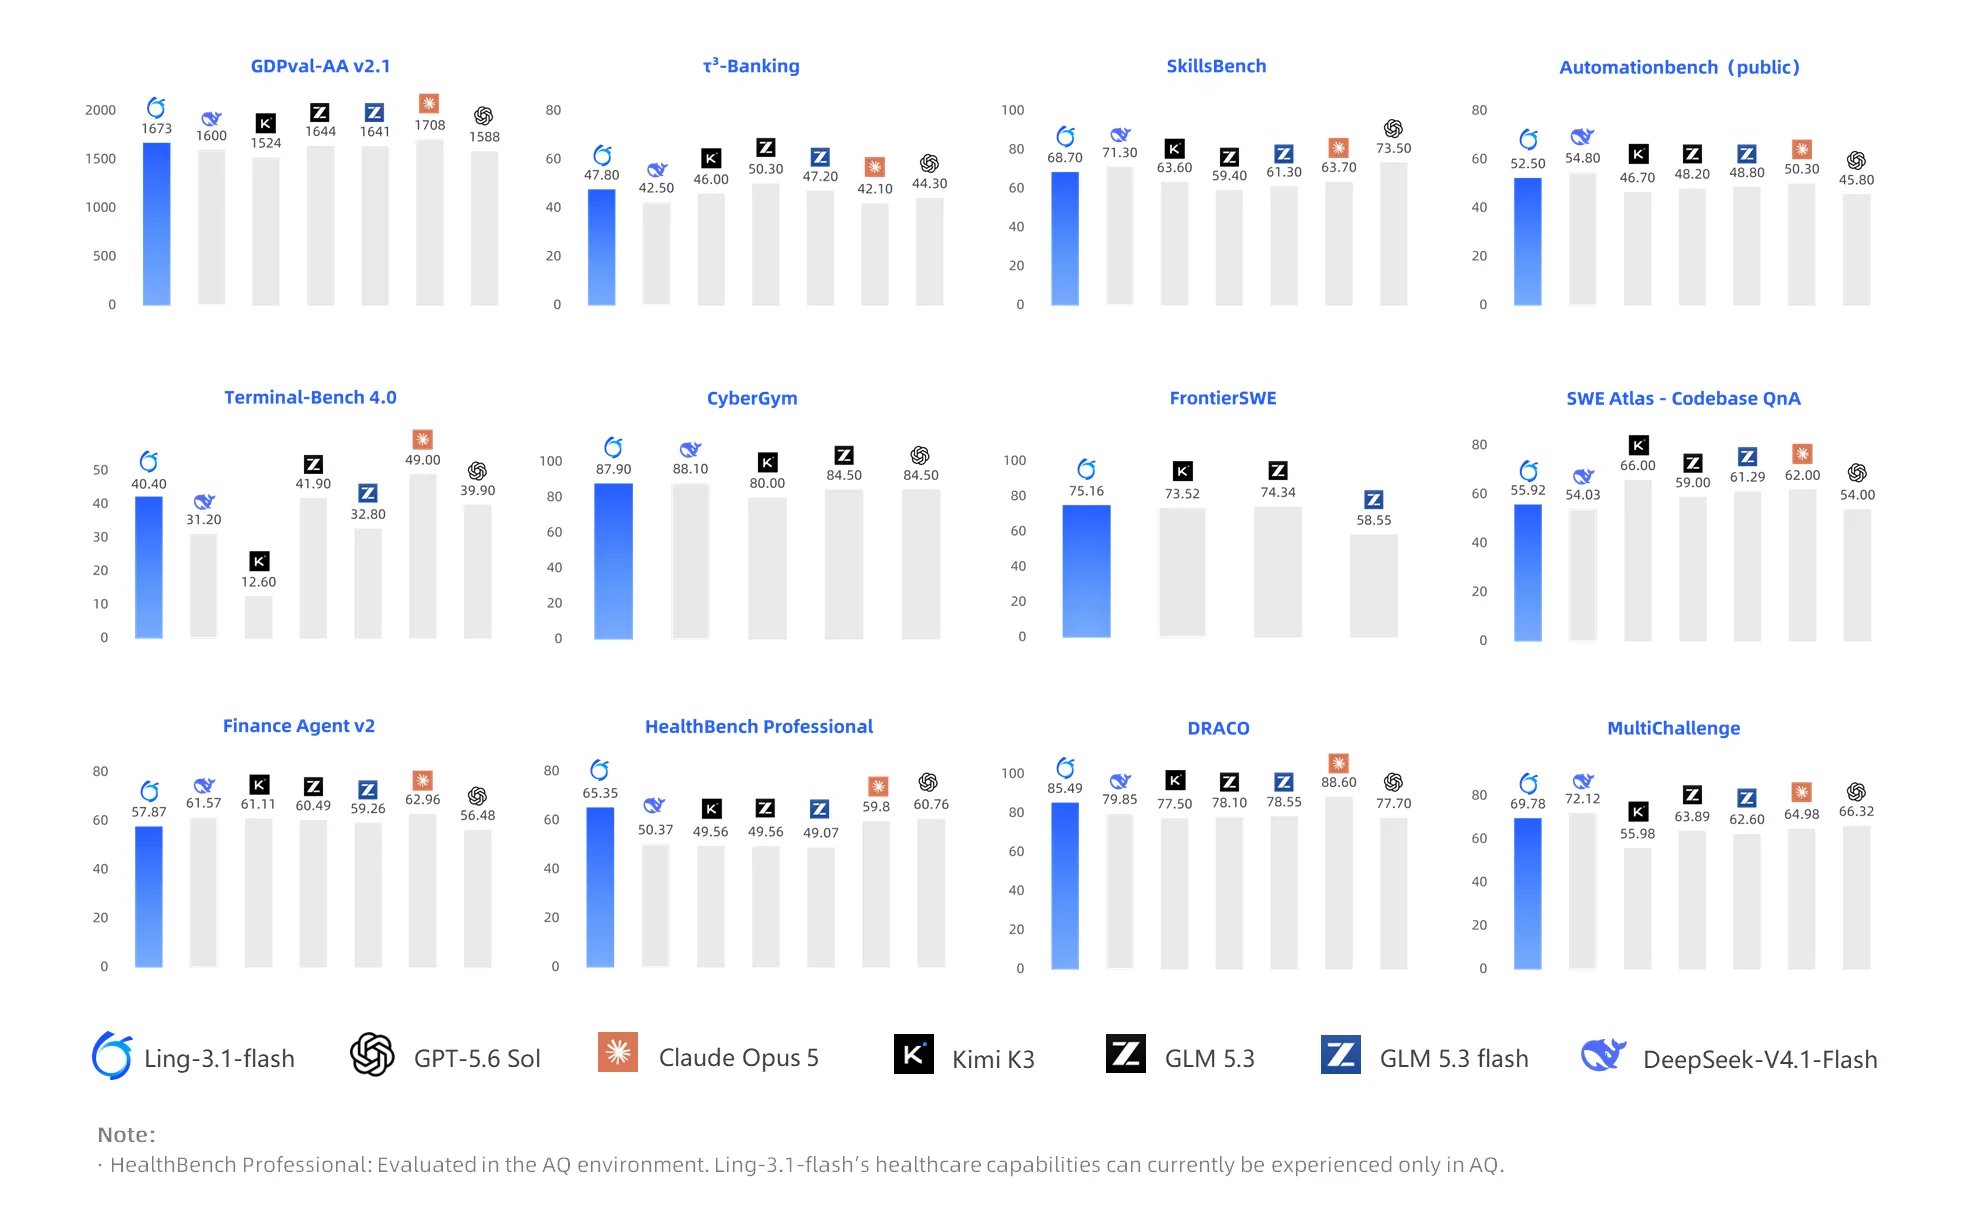
Ling-3.1-flash against the models in Ant Ling's launch chart. A dash means the model was not shown for that benchmark. GDPval-AA is an Elo rating; all other rows are scores.
| Benchmark | Ling-3.1-flash | GPT-5.6 Sol | Claude Opus 5 | Kimi K3 | GLM 5.3 | GLM 5.3 flash | DeepSeek-V4.1-Flash |
|---|---|---|---|---|---|---|---|
| GDPval-AA v2.1 | 1673 Elo | 1588 Elo | 1708 Elo | 1524 Elo | 1644 Elo | 1641 Elo | 1600 Elo |
| τ³-Banking | 47.8 | 44.3 | 42.1 | 46 | 50.3 | 47.2 | 42.5 |
| SkillsBench | 68.7 | 73.5 | 63.7 | 63.6 | 59.4 | 61.3 | 71.3 |
| Automationbench (public) | 52.5 | 45.8 | 50.3 | 46.7 | 48.2 | 48.8 | 54.8 |
| Terminal-Bench 4.0 | 40.4 | 39.9 | 49 | 12.6 | 41.9 | 32.8 | 31.2 |
| CyberGym | 87.9 | 84.5 | — | 80 | 84.5 | — | 88.1 |
| FrontierSWE | 75.16 | — | — | 73.52 | 74.34 | 58.55 | — |
| SWE Atlas - Codebase QnA | 55.92 | 54 | 62 | 66 | 59 | 61.29 | 54.03 |
| Finance Agent v2 | 57.87 | 56.48 | 62.96 | 61.11 | 60.49 | 59.26 | 61.57 |
| HealthBench Professional | 65.35 | 60.76 | 59.8 | 49.56 | 49.56 | 49.07 | 50.37 |
| DRACO | 85.49 | 77.7 | 88.6 | 77.5 | 78.1 | 78.55 | 79.85 |
| MultiChallenge | 69.78 | 66.32 | 64.98 | 55.98 | 63.89 | 62.6 | 72.12 |
This model's scores
- FrontierSWE75.16%
- HealthBench Professional65.35%
- CyberGym87.9%
- DRACO85.49%
- Terminal-Bench 4.040.4%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- 560B total parameters with only 25B active per token, according to inclusionAI's model card
- 1M-token context window
- MIT-licensed weights on Hugging Face, including a base checkpoint for further training
- Led every model in Ant Ling's published launch chart on HealthBench Professional (65.35) and FrontierSWE (75.16)
- Hybrid-linear attention: seven of every eight attention layers run in linear time
Best for
- Agentic office and knowledge work of the kind GDPval-AA measures
- Software-engineering agents working in terminals and real codebases
- Healthcare question answering, which Ant Ling says is available through its AQ environment
- Finance and banking agent workflows
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (weights) ↗ | inclusionAI/Ling-3.1-flash |
| OpenRouter ↗ | inclusionai/ling-3.1-flash |
Ling (open-weight) — every version
The full lineage of the Ling (open-weight) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Ling-3.1-flashcurrent | 2026-09-30 | 1M | MIT |
| Ling-3.0-tiny | 2026-08 | — | MIT |
| Ling-3.0-flash | 2026-08-02 | 256K | MIT |
FAQ
Is Ling-3.1-flash open source?
Yes, since October 2026. It launched on 30 September 2026 as a free hosted trial without downloadable weights. inclusionAI then published the weights on Hugging Face under the MIT License: Ling-3.1-flash, the base checkpoint Ling-3.1-flash-base, and the upgraded Ling-3.1-flash-1019.
How many parameters does Ling-3.1-flash have?
About 560 billion total parameters, with about 25 billion activated per token, according to Ant Ling. It is a Mixture-of-Experts model, so only a fraction of the weights run for each token.
How long a context does Ling-3.1-flash support?
1 million tokens, according to inclusionAI's model card. During the launch trial it was served at a shorter 262,144-token window; on OpenRouter the Novita endpoint serves the full 1M-token context with up to 262,144 output tokens.
How can I try Ling-3.1-flash?
Download the weights from Hugging Face (inclusionAI/Ling-3.1-flash, or the upgraded Ling-3.1-flash-1019) and serve them with SGLang or vLLM, which the model card recommends on eight H200 GPUs. It is also available as a hosted model on OpenRouter as inclusionai/ling-3.1-flash. It was free during the two-week launch trial; OpenRouter lists paid endpoints after it.
How does Ling-3.1-flash compare with other models?
In Ant Ling's own launch chart it scored highest of the seven models shown on HealthBench Professional (65.35) and FrontierSWE (75.16), while Claude Opus 5 led on GDPval-AA v2.1, Terminal-Bench 4.0 and DRACO, and GPT-5.6 Sol led on SkillsBench. These are the maker's figures.