
Overview
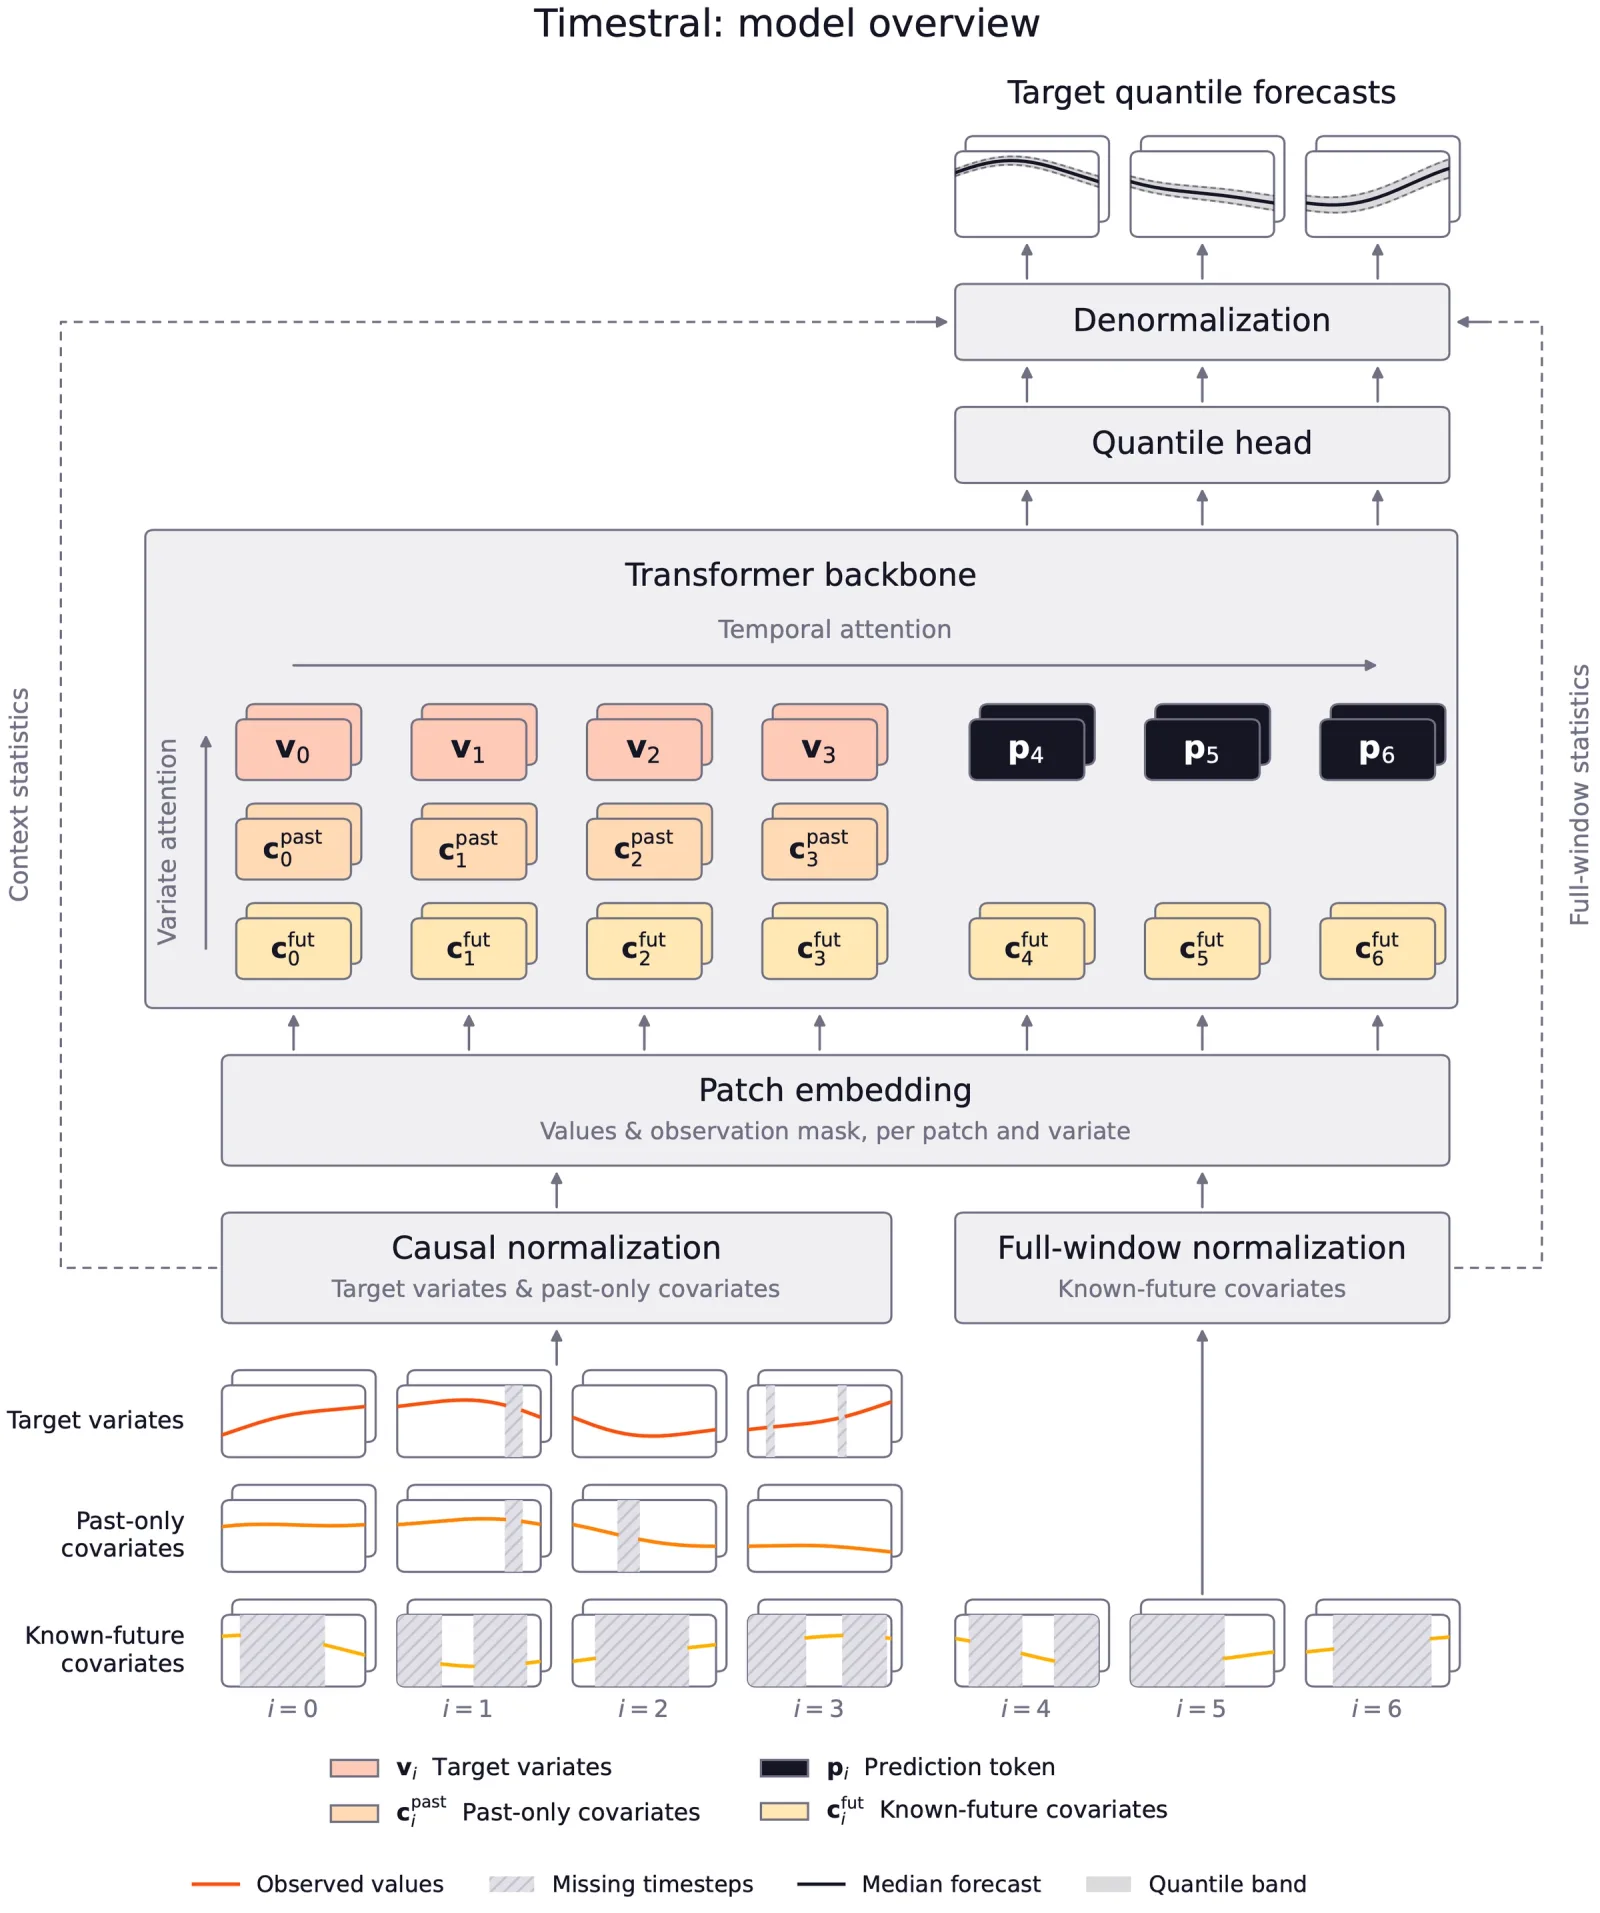
Timestral 1.0 is Mistral AI's first family of time-series foundation models, announced on October 15, 2026. It comes in four sizes — 5M, 28M, 123M and 209M parameters — that share one architecture and training recipe, and it forecasts the future values of one series or of several related series zero-shot, without training on your data first. Every forecast is probabilistic: the model returns 21 quantiles from 0.01 to 0.99 rather than a single line.
The models read up to 32,768 past time steps and forecast up to 1,024 steps in one forward pass, with longer horizons produced block by block. Alongside the target series they accept past-only covariates and known-future covariates (such as a holiday calendar), and missing values can be passed as NaN. Mistral describes two design ideas: Decoupled Horizon Forecasting, which keeps the full history in the sequence and reads it with learned forecast tokens, and covariate-aware attention, which gives each series a role so information flows only from covariates to targets. Most of the training data is synthetic — simple processes with trends, seasonality and noise, combined into multivariate series — followed by post-training on real and synthetic data with a four-times-longer context.
Timestral is built for CPUs inside existing data pipelines. On an 8-thread server CPU, Mistral reports 10 ms per forecast for the 5M model and 140 ms for the 209M model; the 123M model comes within 0.2% of the 209M score at about three-quarters of its latency. The weights are on Hugging Face under a Modified MIT license, the inference code is on GitHub under Apache 2.0, and Mistral Forge is offered for fine-tuning with domain-specific covariates. A technical report was announced as forthcoming at launch.
| Released | 2026-10-15 |
|---|---|
| License | Modified MIT (weights) · Apache-2.0 (inference code) |
| Weights | Open weights |
| Parameters | 5M · 28M · 123M · 209M |
| Context | 32,768 time steps |
| Max output | 1,024 steps per forward pass (longer horizons block by block) |
| Architecture | Patch-based transformer with temporal and variate attention (209M: 24 layers, embedding dimension 768, 32-step patches) and a 21-quantile output head |
| Modalities | Time series |
| Status | Public preview in Mistral's docs (model id timestral-1-0); open weights on Hugging Face |
Benchmarks
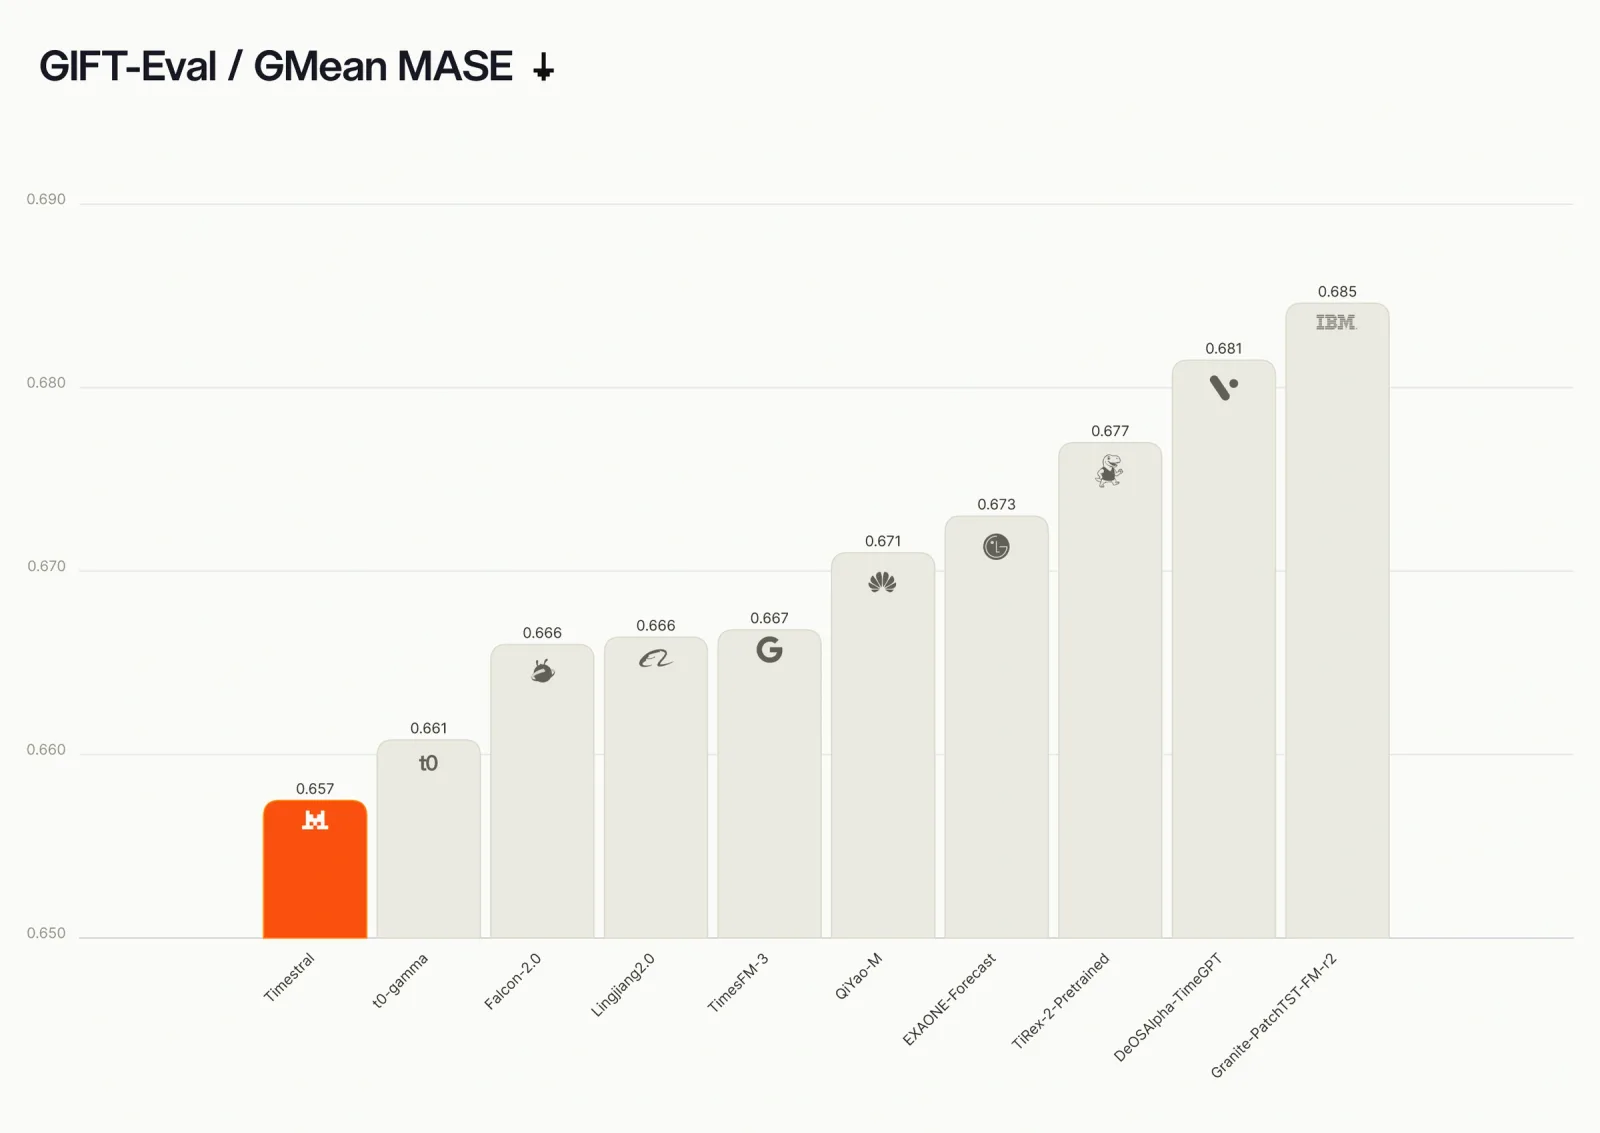
Zero-shot forecasting scores as published on the Timestral-209M model card. MASE and CRPS: lower is better; skill scores: higher is better.
| Benchmark | Timestral-209M | t0-gamma | TimesFM-3 | Toto-2.0-2.5B | Chronos-2 |
|---|---|---|---|---|---|
| GIFT-Eval MASE (lower is better) | 0.658 | 0.661 | 0.667 | 0.696 | 0.698 |
| GIFT-Eval CRPS (lower is better) | 0.446 | 0.452 | 0.456 | 0.476 | 0.485 |
| TIME MASE (lower is better) | 0.626 | 0.637 | 0.64 | 0.642 | 0.662 |
| TIME CRPS (lower is better) | 0.522 | 0.534 | 0.536 | 0.539 | 0.556 |
| fev-bench SQL skill score (higher is better) | 50.39 | 49.42 | 48.99 | 44.42 | 47.28 |
| fev-bench MASE skill score (higher is better) | 39.49 | 37.99 | 37.82 | 32.54 | 35.5 |
This model's scores
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- Zero-shot probabilistic forecasts: 21 quantiles per step, no per-dataset training
- Handles univariate and multivariate targets plus past-only and known-future covariates in one model
- Long history: up to 32,768 time steps of context, 1,024-step horizon per pass
- Small enough for CPU inference — 10 ms (5M) to 140 ms (209M) per forecast on an 8-thread server CPU, as reported by Mistral
- Open weights in four sizes for on-prem, VPC or air-gapped deployment
- Timestral-209M leads the comparison on Mistral's model card on GIFT-Eval, TIME and fev-bench against t0-gamma, TimesFM-3, Toto-2.0-2.5B and Chronos-2
Best for
- Reach for it to forecast demand, sales or capacity across many related series with uncertainty bands, without fitting a model per series.
- Reach for it to forecast sensor, energy or load readings where known-future covariates such as calendars or schedules matter.
- Reach for the 5M or 28M size when the forecast runs inside a latency-bound CPU pipeline with no GPU available.
- Reach for it when data cannot leave your infrastructure and the model has to run on-prem or air-gapped.
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (open weights) ↗ | mistralai/Timestral-209M |
| Mistral docs ↗ | timestral-1-0 |
FAQ
What is Timestral?
Timestral is Mistral AI's family of time-series foundation models, released on October 15, 2026 in 5M, 28M, 123M and 209M sizes. The models give zero-shot probabilistic forecasts — 21 quantiles per step — for univariate or multivariate series, with optional past-only and known-future covariates.
Which Timestral size should I use?
Mistral reports that Timestral-123M comes within 0.2% of the 209M model's score at about three-quarters of its latency, that the 28M model is about five times faster than the 209M model, and that the 5M model answers in 10 ms on an 8-thread server CPU. Smaller sizes suit tight latency budgets; the 209M model posts the best scores on the model card.
How do I run Timestral?
Install the inference package with `pip install git+https://github.com/mistralai/timestral.git` (Python 3.10+, PyTorch 2.4+), load a checkpoint with `TimestralForecaster.from_pretrained("mistralai/Timestral-209M")` and call `model.forecast(context, prediction_length=96)`; the result exposes the median and any quantile. It runs on CPU or GPU.
How does Timestral compare with TimesFM and Chronos?
On the Timestral-209M model card it scores a GIFT-Eval MASE of 0.658 and CRPS of 0.446 (lower is better), against 0.667 / 0.456 for TimesFM-3 and 0.698 / 0.485 for Chronos-2. Mistral also says the 28M model beats Chronos-2, which is about four times larger, on GIFT-Eval and TIME.
Is Timestral open source?
The inference code is on GitHub under Apache 2.0 and the weights are on Hugging Face under a Modified MIT license, which adds a clause prohibiting use that infringes third-party rights. All four checkpoints can be downloaded and run on your own servers, including air-gapped setups.