Overview
Voxtral Transcribe 3 is the speech-to-text half of Mistral's Voxtral 3 release on October 20, 2026. It comes as three models on the Mistral API: Voxtral Small Transcribe 3, the most accurate; Voxtral Mini Transcribe 3, a 4B-parameter model for cheaper batch transcription; and Voxtral Mini Transcribe Realtime 3, which streams transcripts over a WebSocket at sub-500 ms latency. Mistral lists the batch models at 50+ languages, including the 24 official EU languages, and the realtime model at 35+.
All three identify who said what (diarization) and accept context biasing: key terms and free-form text that raise recall on names and domain vocabulary without fine-tuning. The realtime model adds end-of-turn detection, so a voice agent knows when the speaker has finished, and a configurable delay from 80 ms to 2,400 ms that trades latency for accuracy. Small Transcribe 3 also handles translation, spoken Q&A, summarisation and function calling, and both batch models return timestamps through the /v1/audio/transcriptions endpoint.
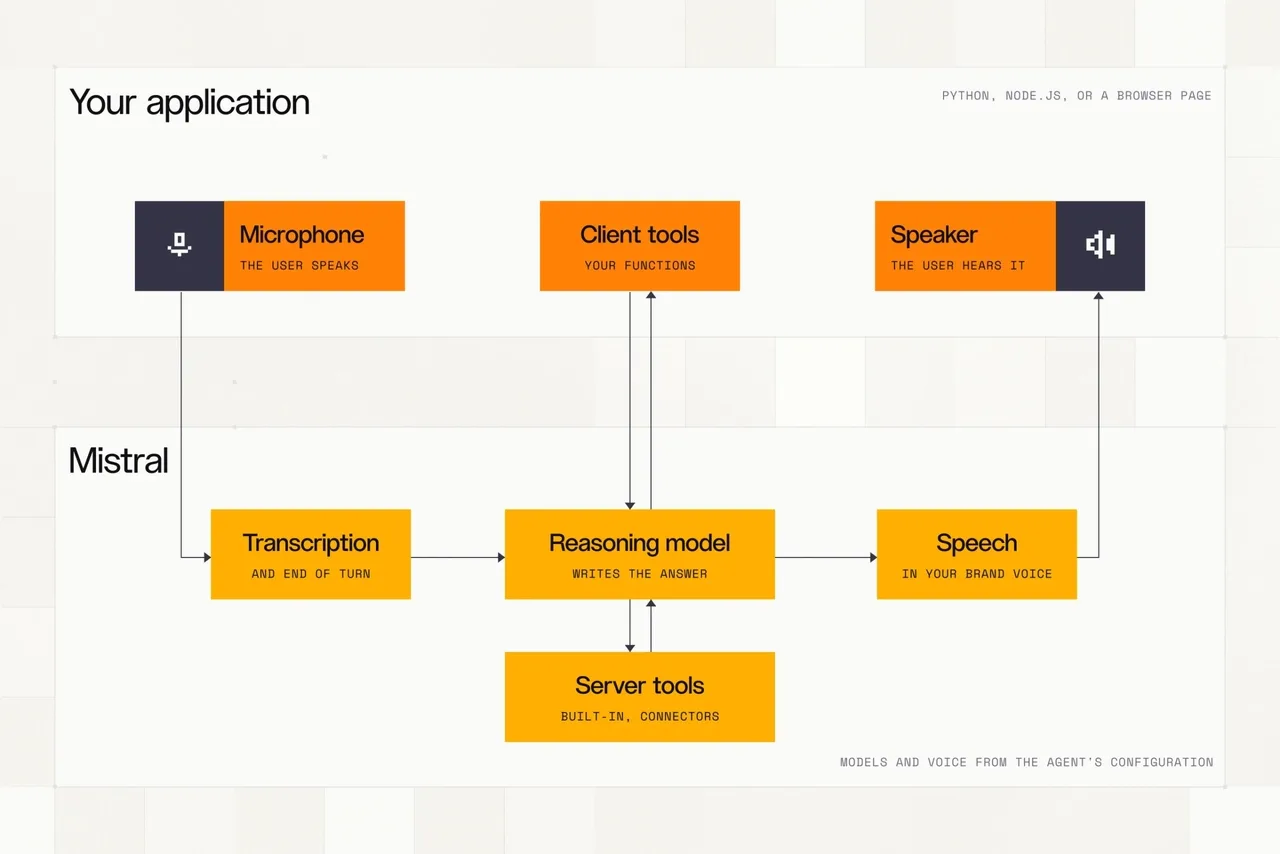
The realtime model is the listening stage of Mistral's new voice agent SDK, built on LiveKit: Voxtral Mini Transcribe Realtime 3 transcribes, Mistral Small reasons and calls tools, and Voxtral TTS 3 speaks the reply, with Mistral quoting under one second per turn. On Mistral's FLEURS table, Small Transcribe 3 posts 4.0% word error rate with the language specified (4.1% auto-detected), level with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%), GPT Transcribe (5.6%) and Whisper large-v3 (14.9%).
| Released | 2026-10-20 |
|---|---|
| License | Proprietary (Mistral Premier) |
| Weights | API only |
| Parameters | Mini Transcribe 3: 4B (Small and Mini Realtime not disclosed) |
| Context | 32K tokens (Small and Mini Transcribe 3) |
| Modalities | Audio, Text |
| Status | Public preview on the Mistral API (Premier models), released October 20, 2026. |
Benchmarks
Mistral's batch transcription comparison from the Voxtral 3 launch post (October 20, 2026). FLEURS rows are macro-average WER over 45 languages (CER for Japanese, Korean, Thai and Chinese); diarization is macro-average cpWER over AMI-IHM, AMI-SDM, Switchboard, CallHome and AISHELL-4. Lower is better on every row.
| Benchmark | Voxtral Small Transcribe 3 | Voxtral Mini Transcribe 3 | Microsoft AI Transcribe 2 | Scribe v2 | Gemini 3.5 Transcribe | GPT Transcribe | Whisper large-v3 |
|---|---|---|---|---|---|---|---|
| FLEURS 45 WER · language specified | 4% | 4.5% | 4% | 4.9% | 4.5% | 5.6% | 14.9% |
| FLEURS 45 WER · language auto-detected | 4.1% | 4.6% | 4.1% | 4.9% | 6.1% | 6.3% | 16% |
| Diarization cpWER | 18.4% | 18.6% | 20.3% | 23% | 38.4% | — | — |
This model's scores
- Earnings-22 keyphrase recall with context (Small)94.6%
- Earnings-22 keyphrase recall without context (Small)81.4%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Pricing
| Input | $0.0035–$0.008 / minute of audio |
|---|
Mini Transcribe 3 $0.0035, Small Transcribe 3 $0.004, Mini Transcribe Realtime 3 $0.008 per minute on the Mistral API.
Strengths
- 4.0% FLEURS word error rate for Small Transcribe 3 across 45 languages, 4.5% for the 4B Mini
- Lowest diarization error in Mistral's comparison: 18.4% cpWER (Small) and 18.6% (Mini) against 20.3% for Microsoft AI Transcribe 2
- Context biasing lifts Small's Earnings-22 keyphrase recall from 81.4% to 94.6%
- Streaming model with end-of-turn detection and an 80–2,400 ms latency setting
- Batch transcription from $0.0035 per minute (Mini) and $0.004 (Small)
Best for
- Reach for Small Transcribe 3 for multi-speaker recordings — meetings, interviews, call-centre audio — where who-said-what matters as much as the words.
- Reach for Mini Transcribe 3 for high-volume batch transcription where a 4B model at $0.0035 per minute is enough.
- Reach for Mini Transcribe Realtime 3 as the ear of a voice agent or live captioning, where end-of-turn detection and a tunable delay matter.
- Pass context biasing terms when audio is full of product names, tickers or jargon that a general model would mishear.
How to access
| Provider | Model ID |
|---|---|
| Mistral API — Small Transcribe 3 ↗ | voxtral-small-transcribe-3-0 |
| Mistral API — Mini Transcribe 3 ↗ | voxtral-mini-transcribe-3-0 |
| Mistral API — Mini Transcribe Realtime 3 ↗ | voxtral-mini-transcribe-realtime-3-0 |
FAQ
Which Voxtral Transcribe 3 model should I use?
Small Transcribe 3 is Mistral's most accurate model (4.0% FLEURS WER, 18.4% diarization cpWER) at $0.004 per minute. Mini Transcribe 3 is a 4B model at $0.0035 per minute with 4.5% WER. Mini Transcribe Realtime 3 streams transcripts with a configurable 80–2,400 ms delay and end-of-turn detection for live use, at $0.008 per minute.
Are the Voxtral Transcribe 3 weights open?
No weights were published with the October 20, 2026 release. The three models are Premier models in public preview on the Mistral API; Mistral offers self-deployment or private-cloud installs on request.
What is context biasing?
You pass key terms and free-form text with the audio so the model favours them when it transcribes. On Mistral's Earnings-22 keyphrase test, it raised Small Transcribe 3's recall from 81.4% to 94.6%.
How accurate is the realtime model?
On Mistral's 35-language FLEURS realtime test, Voxtral Mini Transcribe Realtime 3 scores 5.7% WER at a 2,400 ms delay, 6.0% at 960 ms, 6.4% at 480 ms and 7.4% at 240 ms, against 5.8% for Microsoft AI Transcribe 2 Streaming, 8.4% for GPT Live Transcribe and 8.7% for Scribe v2 Realtime.