Overview
Voxtral TTS 3 is the text-to-speech half of Mistral's Voxtral 3 release on October 20, 2026, launched alongside the Voxtral Transcribe 3 speech-to-text models and a voice agent SDK. It is served on the Mistral API as voxtral-mini-tts-3-0 through the same /v1/audio/speech endpoint as its predecessor, in public preview as a Premier model, and it can be tried in the Mistral Studio playground. The launch post's pricing table calls it Voxtral Speech 3.
Delivery can be directed: the docs list 34 emotion tags and 2 pace tags, and the launch post describes custom prompt instructions, contextual speech that follows the tone of the conversation, and a vocabulary library with phoneme hints for rare words. Voices come from presets, from zero-shot cloning of a short reference, or from professional voice cloning, which Mistral says reproduces a speaker's character and style from about 30 minutes of audio. The model streams with about 90 ms to first audio and supports five output formats. The launch post describes 35+ languages and 50+ dialects; the model's docs page lists 9 supported languages.
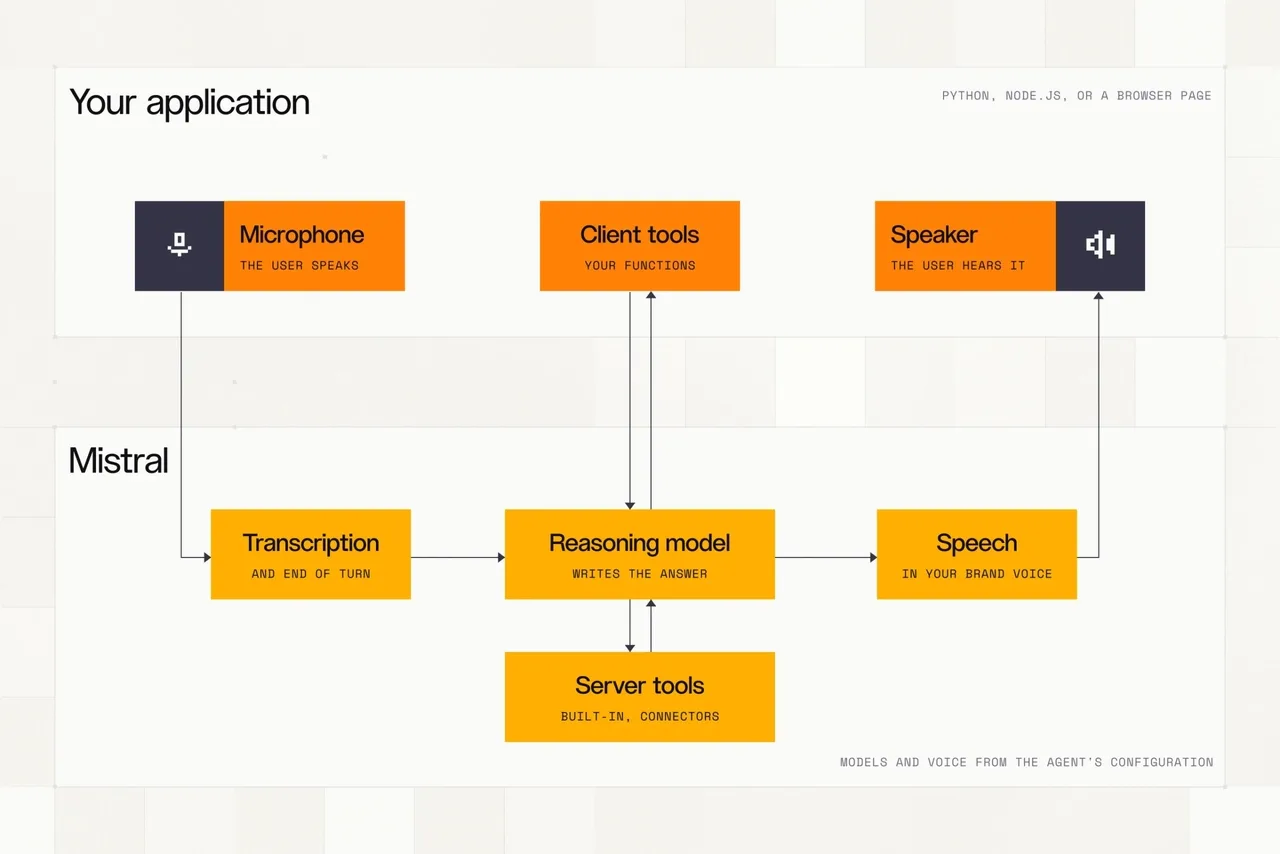
In the voice agent SDK, built on LiveKit, Voxtral Mini Transcribe Realtime 3 listens, a Mistral reasoning model calls tools, and Voxtral TTS 3 speaks the reply; Mistral quotes under one second per turn and says the agent stops talking when the caller interrupts. Batch and realtime speech cost the same $13 per million characters, below the $0.016 per 1,000 characters ($16 per million) Mistral listed for the March 2026 Voxtral TTS. Mistral's launch charts plot the model against Eleven v4, Gemini 3.8 Flash TTS, Inworld TTS-2, Cartesia Sonic 3.6 and others on internal tests scored by an automated judge, but publish no per-model figures.
| Released | 2026-10-20 |
|---|---|
| License | Proprietary (Mistral Premier) |
| Weights | API only |
| Parameters | Not disclosed |
| Modalities | Text, Audio |
| Status | Public preview on the Mistral API (Premier models), released October 20, 2026. |
Pricing
| Input | $13 / 1M characters |
|---|
Same price for batch and realtime speech on the Mistral API.
Strengths
- Zero-shot voice cloning plus professional voice cloning from about 30 minutes of audio
- 34 emotion tags and 2 pace tags, plus prompt instructions and phoneme hints for rare words
- Streaming with about 90 ms time-to-first-audio
- One price for batch and realtime: $13 per million characters
- Speaks the replies in Mistral's LiveKit-based voice agent SDK, with interruption handling
Best for
- Reach for it as the voice of a phone or in-app voice agent built on Mistral's SDK, where the reply should follow the tone of the conversation.
- Reach for professional voice cloning when a brand or narrator voice has to stay consistent across a product.
- Use emotion, pace and phoneme hints for scripted narration with product names or invented words.
- Use the March 2026 Voxtral TTS instead when you need open weights to run on your own hardware.
How to access
| Provider | Model ID |
|---|---|
| Mistral API ↗ | voxtral-mini-tts-3-0 |
Voxtral TTS (text-to-speech) — every version
The full lineage of the Voxtral TTS (text-to-speech) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Voxtral TTS 3current | 2026-10-20 | — | Proprietary |
| Voxtral TTS | 2026-03-23 | — | CC BY-NC 4.0 |
FAQ
How much does Voxtral TTS 3 cost?
$13 per million characters on the Mistral API, the same for batch and realtime speech. The March 2026 Voxtral TTS was listed at $0.016 per 1,000 characters.
Are the Voxtral TTS 3 weights open?
No weights were published with the October 20, 2026 release; it is a Premier model in public preview on the Mistral API, and Mistral offers on-premises or private-cloud deployment on request. The earlier Voxtral TTS (March 2026) has open weights under CC BY-NC 4.0.
Can Voxtral TTS 3 clone a voice?
Yes. The docs list zero-shot voice cloning and professional voice cloning; Mistral says professional cloning reproduces a speaker's character and style from about 30 minutes of audio.
How fast is it?
Mistral's docs give about 90 ms time-to-first-audio when streaming. In the voice agent SDK, Mistral quotes a full listen-reason-speak turn in under one second.