Lynch Lab · 2026-10-25 · notable
Old CNN beats frontier LLMs at skin cancer diagnosis — Lynch Lab test
Dermatologist Magnus Lynch tested GPT-6 Astra and Claude Fable 5.1 against a fine-tuned Inception v3 CNN on 200 biopsy-proven skin lesions. The CNN got 62% right on first choice; both LLMs got 42%.
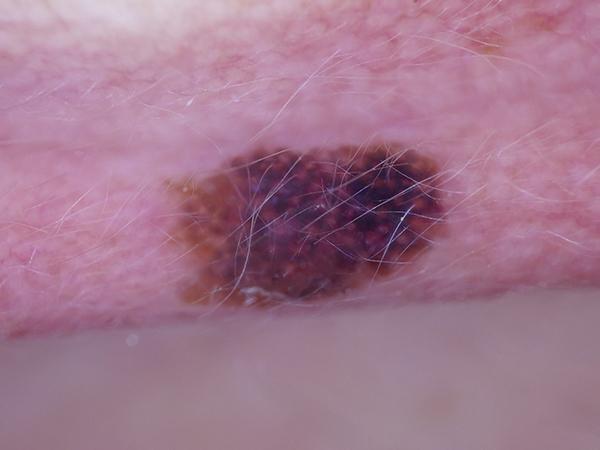
A decade-old image classifier made fewer misses than two frontier LLMs on hard, biopsy-proven skin lesions.
Key specs
| Cnn first choice accuracy | 62% |
|---|---|
| Llm first choice accuracy | 42% |
What is it?
Magnus Lynch, a consultant dermatologist at Guy's Hospital and King's College London, ran a small head-to-head test of GPT-6 Astra, Claude Fable 5.1 and an Inception v3 CNN. The test set is 200 lesions from the MILK10k dataset, each with a clinical photo and a dermoscopic image, split evenly between lesions that need care and lesions that are safe to discharge.
How does it work?
Each model picked from six diagnoses for every case. The CNN was pretrained on everyday photos, then fine-tuned on 68,011 ISIC Archive images; the LLMs ran once each at default settings. Scoring looked at first choice, top two, and whether a patient would be wrongly sent home. The cases, prompts, every LLM reply and the scoring code are in a public download.
Why does it matter?
The general-purpose LLMs played it safe, keeping almost all risky lesions but also almost all harmless ones, and named far fewer correct diagnoses than the narrow CNN. Lynch notes clear limits: only 30 melanomas, single runs, possible LLM exposure to the public images, and a CNN that is a baseline rather than state of the art.
Who is it for?
clinical AI researchers and dermatologists
Try it
https://lynchlab.net/skin-ai-inception