Tencent · 2026-10-22 · notable
WeVisOne-VL — Tencent's open model for boxes, masks and mattes
WeVisOne-VL is an open vision-language model from Tencent's WeChat Vision team. One 2B or 4B model handles detection, counting, pointing, OCR, segmentation and alpha matting, and it rejects questions about objects that are not there.
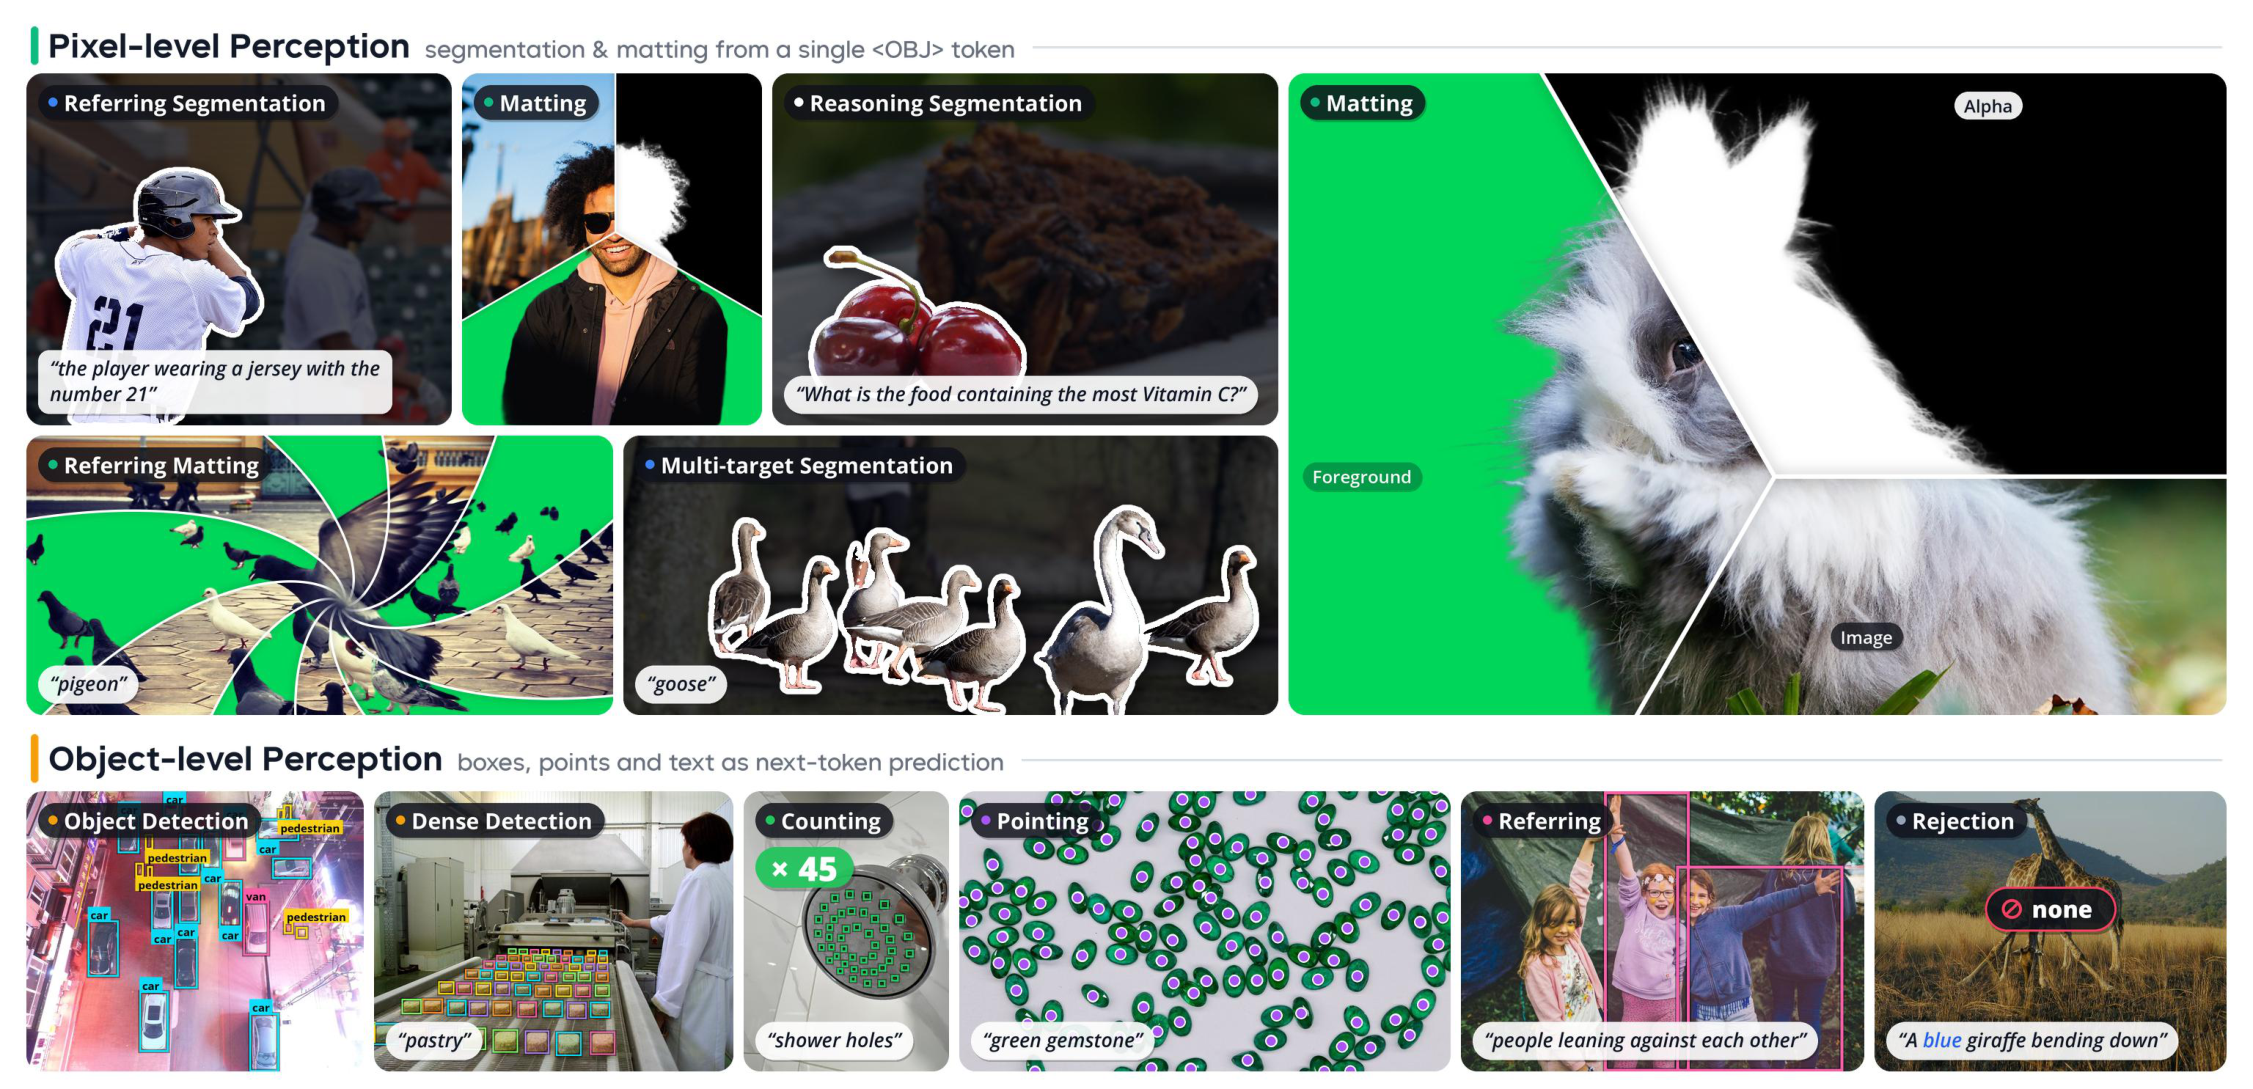
One open Tencent model for the whole range of visual perception, from points and boxes to pixel-level mattes.
Key specs
| Hf papers upvotes | 223 |
|---|---|
| Lvis f1 (4 b) | 55.3 |
What is it?
Tencent's WeChat Vision team released WeVisOne-VL, a vision-language model in 2B and 4B sizes under Apache-2.0. It covers object-level tasks (detection, referring, counting, pointing, OCR) and pixel-level tasks (referring segmentation and promptable alpha matting) in one model.
How does it work?
Every task is written as structured next-token prediction. A special <OBJ> token triggers a light 9.6M-parameter pixel decoder that reads multi-level Qwen3-VL ViT features to draw masks and mattes. Training uses a three-stage SFT curriculum followed by mixed-task reinforcement learning.
Why does it matter?
Teams usually stitch separate detectors, segmenters and matting models together. The paper reports leading results on more than 30 benchmarks, and the 4B model beats the best open baseline on LVIS detection (55.3 vs 50.7 F1) and ReasonSeg (71.2 vs 65.0 gIoU). It was the top paper on Hugging Face Papers on 23 October.
Who is it for?
computer vision engineers
Try it
WeVisOneVL("tencent/WeVisOne-VL-4B", backend="transformers")