
What is SemIf?
SemIf is an open-source baseline for what its author calls a semantic if: a small language model answers a runtime-defined question by reporting the probability of each option you allow, rather than writing an answer sentence that your code parses back into a conditional. It sits in the Structured Output category of the App Orchestration tools and is open-source, written in Python and licensed MIT.
Overview
SemIf is an open-source baseline for what its author calls a semantic if: a small language model answers a runtime-defined question by reporting the probability of each option you allow, rather than writing an answer sentence that your code parses back into a conditional. One forward pass carries the unstructured state, the criteria and the typed options, and the declared option logits are read back directly. No answer token is sampled, so there is no JSON to repair and no decoding loop.
The project was formerly called OpenJev and is an independent reproduction of the interface pattern published by TypeSafe for its Jev service. Its author states that it does not reproduce Jev's undisclosed model or training, and that it is not affiliated with or endorsed by TypeSafe. What SemIf shows is that frozen, openly available models in the 0.6B to 4B range can serve the same shape of request on hardware you already own.
SemIf sits in the structured-output layer of an LLM stack, alongside constrained-decoding libraries such as Outlines, XGrammar and LM Format Enforcer. The difference is that those tools shape the tokens a model generates, while SemIf skips generation entirely for the narrow case of choosing among a fixed set of described options. Its results, fixtures, runners, raw timings, prompt hashes and known failure rows are committed to the repository so the published numbers can be rerun.
What it does
- Direct scoring mode that reads declared option logits in a single forward pass, emitting zero output tokens
- Runtime-defined criteria and option descriptions supplied with each request, so no fine-tune is needed per decision
- Shared-state modes that prefill one long state once and branch it across many criteria, serially or in parallel
- Browser demo that runs quantized GGUF builds of Qwen3-0.6B, MiniCPM5-2B and Qwen3.5-4B on WebGPU
- Native MLX backend for macOS on Apple Silicon
- Committed fixtures, runners, row-level predictions, raw timings and model revisions for reproduction
Getting started
SemIf needs Python 3.10 or newer, CUDA and a GPU that can hold a 4B BF16 model. On Apple Silicon, install the MLX extra instead and pass --backend mlx.
Create a virtual environment
Set HF_HOME to a drive with room for the model weights before installing.
python -m venv .venv
. .venv/bin/activate
export HF_HOME=/path/to/large-drive/huggingface
Install SemIf
Install from a checkout of the repository. Add the mlx extra on Apple Silicon.
pip install -e '.[test]'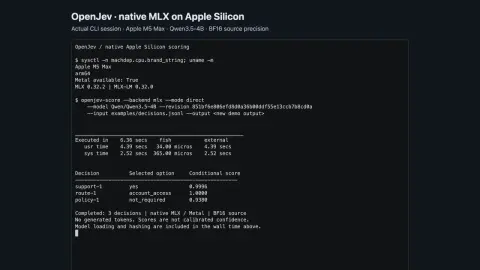
Score the bundled examples
Direct mode reads typed option scores for each row. Each result carries timing, the exact model revision and a prompt hash.
CUDA_VISIBLE_DEVICES=0 semif-score \
  --mode direct \
  --model Qwen/Qwen3.5-4B \
  --revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a \
  --input examples/decisions.jsonl \
  --output results.jsonl
Reuse one state across many criteria
When every row shares the same state, shared mode prefills it once and evaluates the criteria in parallel.
semif-score --mode shared --model Qwen/Qwen3.5-4B --input examples/decisions.jsonl --output results.jsonlCommands and code are distilled from the project's own documentation — always check the official repo for the latest.
When to use it
- Routing, triage and retry decisions inside an agent loop where a full generated answer is wasted work
- Scoring one long document or conversation against many yes/no criteria at once
- Running typed decisions locally or in a browser when sending the state to a hosted API is not an option
- Benchmarking whether a small open model is good enough before paying for a hosted decision service
How SemIf compares
SemIf alongside other open-source structured output tools AI/TLDR tracks, ranked by GitHub stars.
| Tool | Stars | What it does |
|---|---|---|
| Laya | ★ 35k | An Apache-2.0 decision model that answers choice, score and boolean questions about text in one forward pass, returning calibrated probabilities instead of generated JSON. |
| Guidance | ★ 21.8k | A programming model that interleaves generation, prompting, and control logic to constrain output and enforce formats like JSON or regex patterns. |
| Outlines | ★ 16k | A library for structured generation that constrains an LLM's token output to match a JSON schema, regex, or grammar so the result is always valid. |
| Instructor | ★ 14.1k | A library that wraps an LLM client to return data validated against a schema, retrying automatically on invalid output, with SDKs in several languages. |
| BAML | ★ 9.5k | A domain-specific language for defining LLM functions with typed schemas, parsing flexible model output into reliable structured data across many languages. |
| Marvin | ★ 6.2k | A Python toolkit from Prefect for turning LLM calls into typed functions that extract, classify, and cast text into structured Python objects. |
| SemIf | ★ 4.9k | Read typed option probabilities from an open model instead of generating JSON |
| LM Format Enforcer | ★ 2k | A library that enforces an output format such as JSON schema or regex by filtering the tokens an LLM is allowed to generate at each step. |