
Overview
DeepSeek-V4-Pro is the larger of the two models in DeepSeek's V4 series. It first appeared as a preview on 24 April 2026 and reached general availability on 13 August 2026 as the checkpoint DeepSeek-V4-Pro-0813, which DeepSeek calls 'the official release of DeepSeek-V4-Pro, superseding the preview version, with greatly enhanced agentic capabilities'. It is a Mixture-of-Experts language model with 1.6 trillion total parameters and 49 billion activated per token, and it supports a context length of one million tokens. The smaller sibling in the series is DeepSeek-V4-Flash (284B total / 13B active).
The model introduces a Hybrid Attention Architecture that combines Compressed Sparse Attention and Heavily Compressed Attention to make long-context inference far cheaper than V3: in the 1M-token setting DeepSeek reports it needs only about 27% of the single-token inference FLOPs of the prior generation. It was trained on more than 32 trillion tokens and uses techniques including Manifold-Constrained Hyper-Connections and the Muon optimizer. The 0813 release keeps the preview's model structure and attaches a DSpark speculative-decoding module.
The GA checkpoint is aimed squarely at agent work. In DeepSeek's own comparison it scores 87.9 on Terminal Bench 2.1 (against 72.1 for the preview), 62.7 on DeepSWE (12.8 for the preview), 83.3 on Cybergym, 74.1 on Toolathlon-Verified, 61.5 on NL2Repo and 31.8 on the public AutomationBench set, with HLE at 42.7 without tools and 60.0 with tools. DeepSeek evaluates the code-agent tasks using the minimal mode of DeepSeek Harness at the `max` reasoning-effort level.
Reasoning effort is selectable through the `reasoning_effort` parameter, which in the 0813 release takes the levels `low`, `high` and `max`. All weights are released under the MIT License and published on Hugging Face, making the model fully open for local deployment and commercial use; for the `high` and `max` levels DeepSeek recommends allowing up to 384K output tokens.
DeepSeek also changed how the V4 API is billed alongside the GA launch: from 16:00 UTC on 16 August 2026 prices vary by time of day, with peak hours defined as 01:00–04:00 and 06:00–10:00 UTC and off-peak rates set at half the peak rate.
| Released | 2026-08-13 |
|---|---|
| License | MIT |
| Weights | Open weights |
| Parameters | 1.6T total · 49B active |
| Context | 1M |
| Max output | 384K |
| Architecture | Mixture-of-Experts |
| Modalities | Text |
| Status | Generally available |
Benchmarks
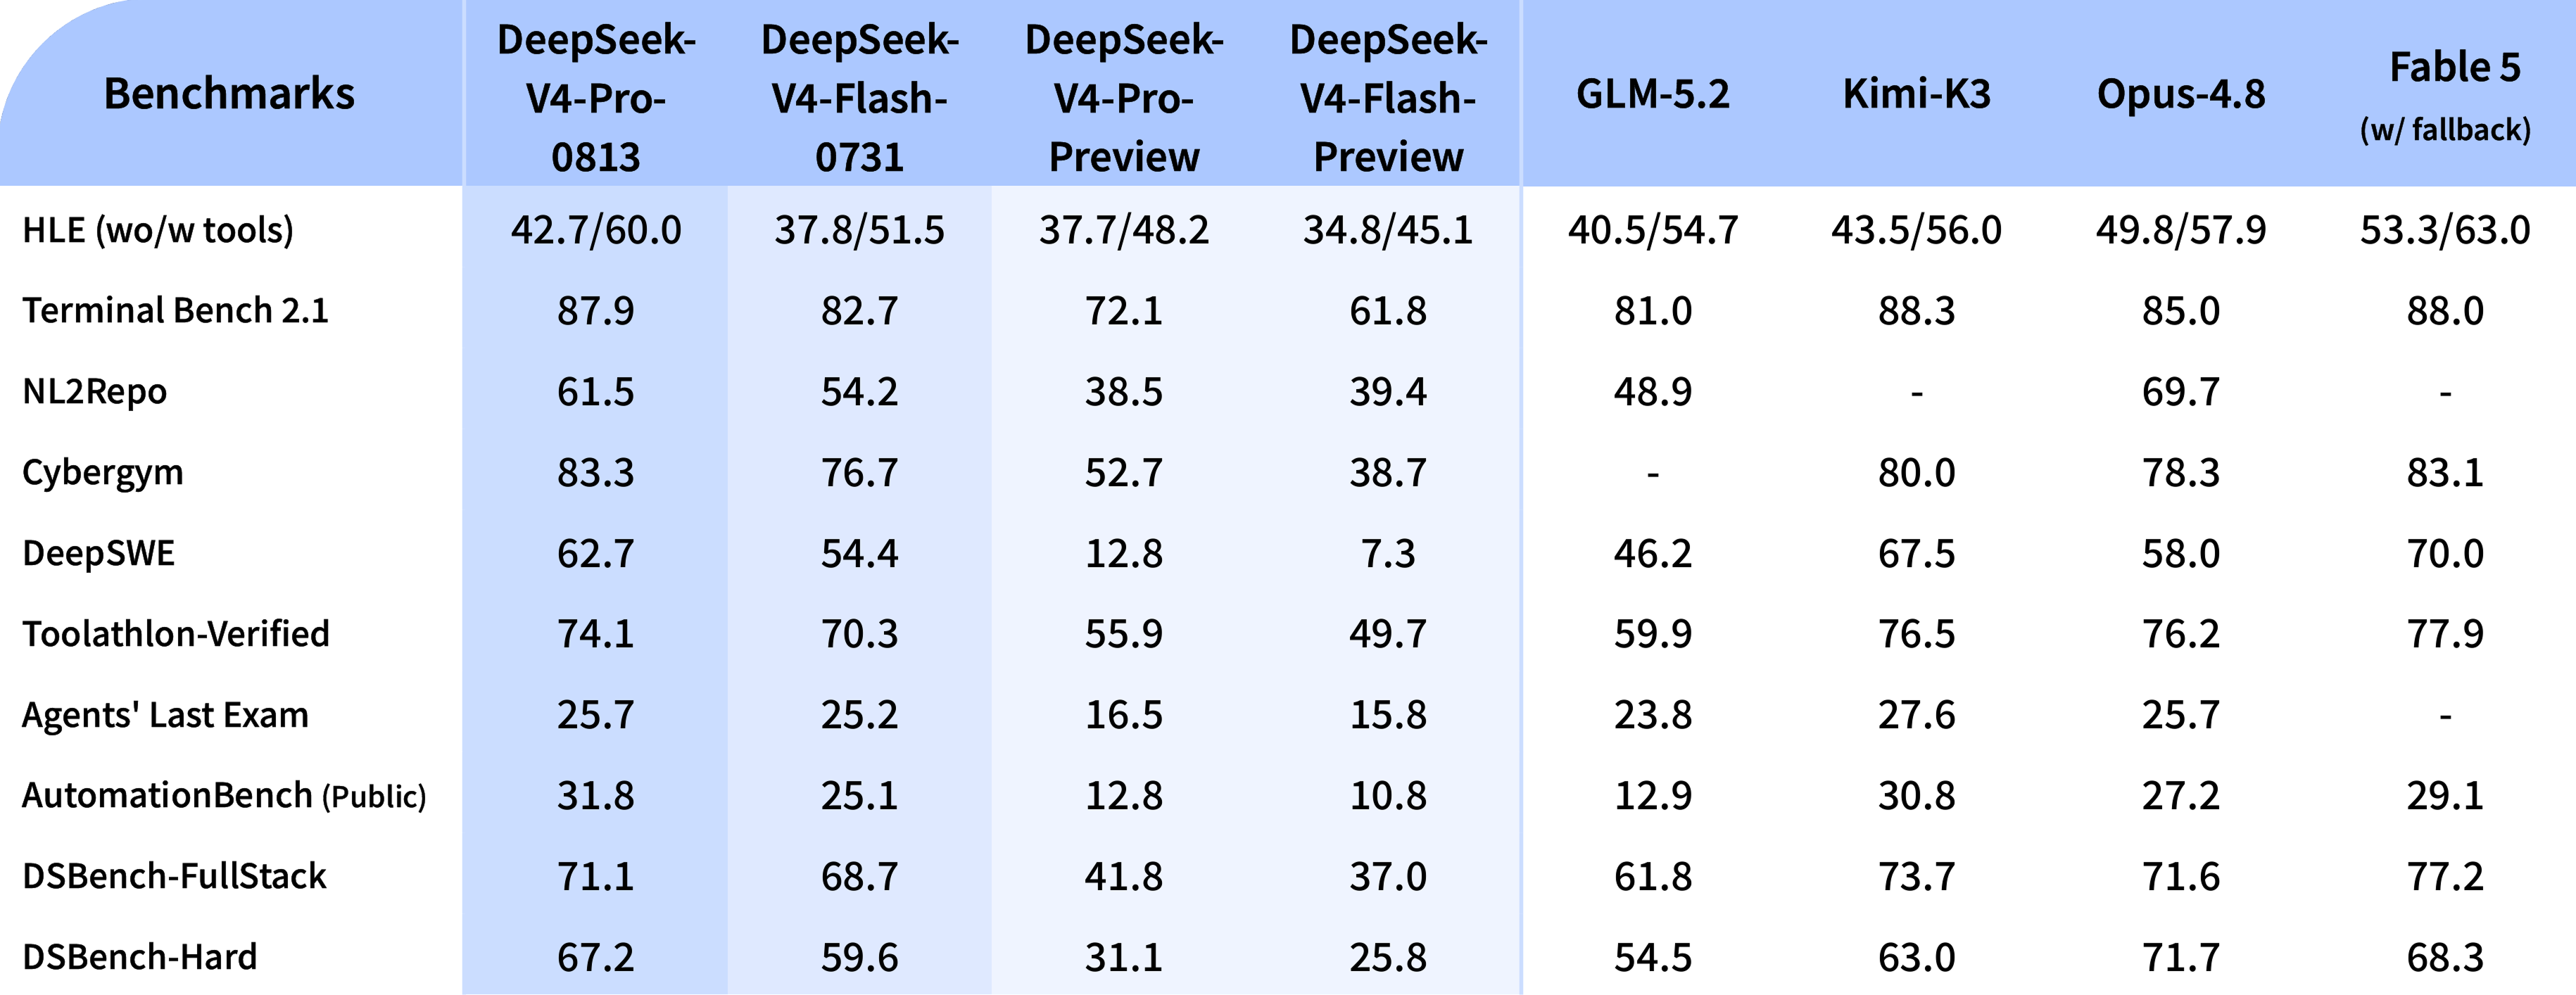
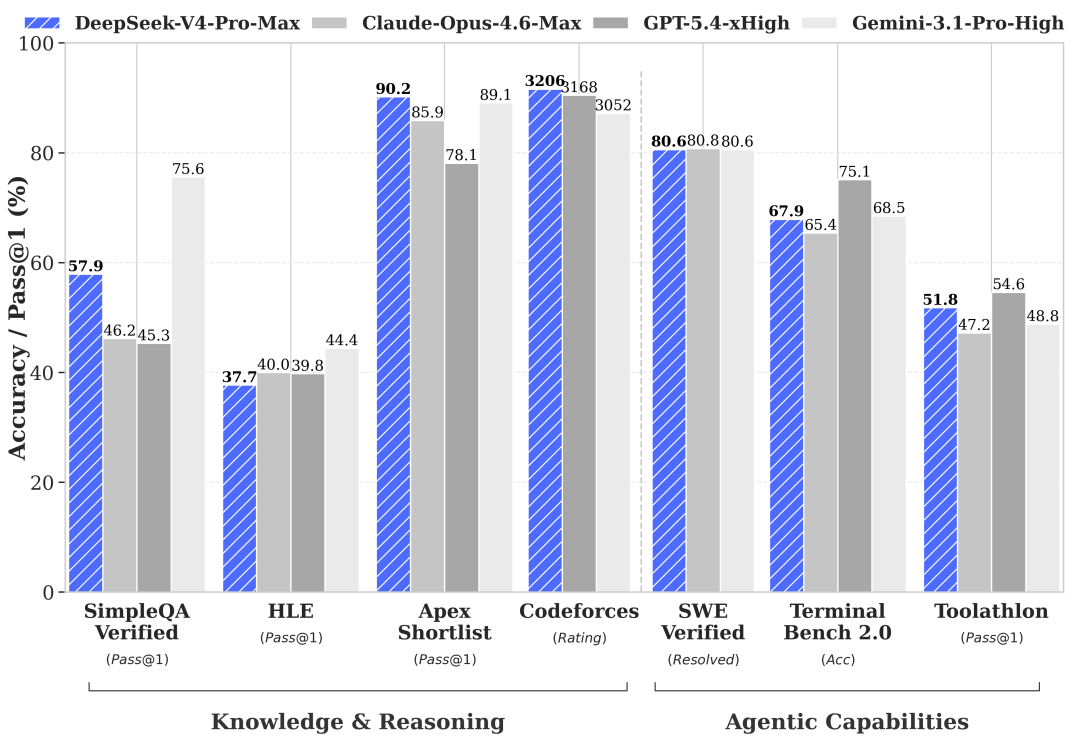
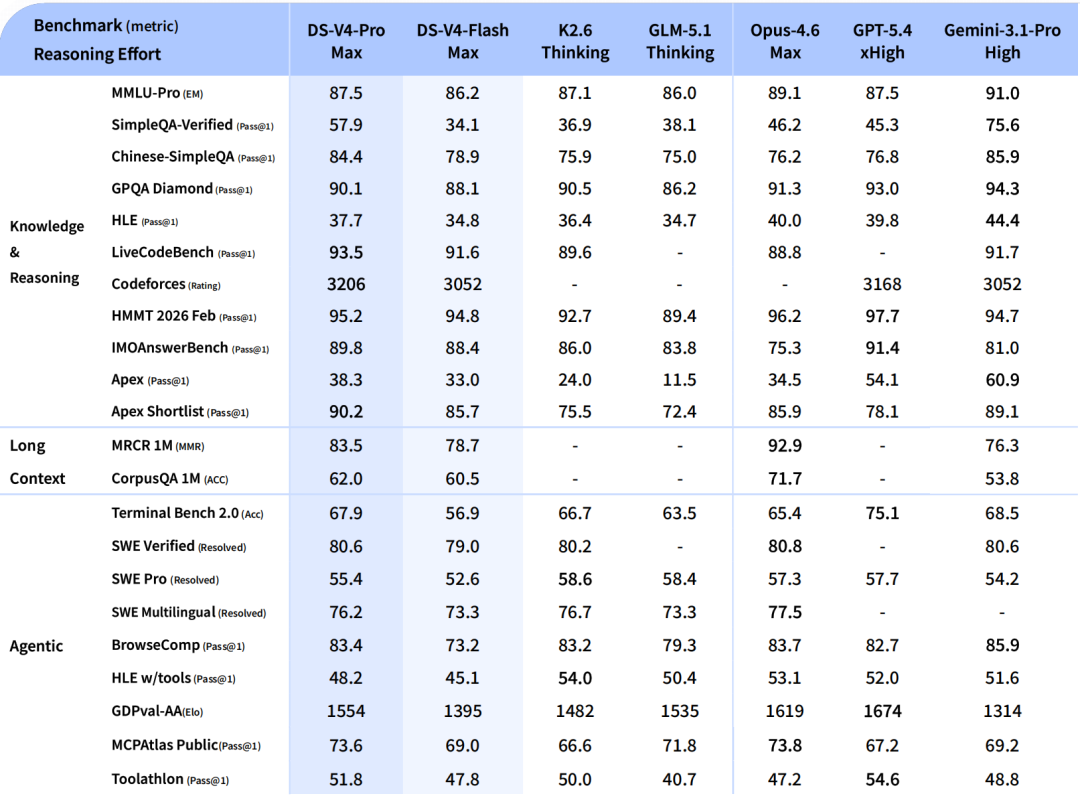
DeepSeek-V4-Pro-0813 against the field, as published by DeepSeek with the GA release (13 August 2026).
| Benchmark | DeepSeek-V4-Pro-0813 | DeepSeek-V4-Flash-0731 | DeepSeek-V4-Pro (Preview) | DeepSeek-V4-Flash (Preview) | GLM-5.2 | Kimi K3 | Opus-4.8 | Fable-5 (w/ fallback) |
|---|---|---|---|---|---|---|---|---|
| HLE (without / with tools) | 42.7 / 60.0 | 37.8 / 51.5 | 37.7 / 48.2 | 34.8 / 45.1 | 40.5 / 54.7 | 43.5 / 56.0 | 49.8 / 57.9 | 53.3 / 63.0 |
| Terminal Bench 2.1 | 87.9 | 82.7 | 72.1 | 61.8 | 81 | 88.3 | 85 | 88 |
| NL2Repo | 61.5 | 54.2 | 38.5 | 39.4 | 48.9 | — | 69.7 | — |
| Cybergym | 83.3 | 76.7 | 52.7 | 38.7 | — | 80 | 78.3 | 83.1 |
| DeepSWE | 62.7 | 54.4 | 12.8 | 7.3 | 46.2 | 67.5 | 58 | 70 |
| Toolathlon-Verified | 74.1 | 70.3 | 55.9 | 49.7 | 59.9 | 76.5 | 76.2 | 77.9 |
| Agents' Last Exam | 25.7 | 25.2 | 16.5 | 15.8 | 23.8 | 27.6 | 25.7 | — |
| AutomationBench (public) | 31.8 | 25.1 | 12.8 | 10.8 | 12.9 | 30.8 | 27.2 | 29.1 |
| DSBench-FullStack (internal) | 71.1 | 68.7 | 41.8 | 37 | 61.8 | 73.7 | 71.6 | 77.2 |
| DSBench-Hard (internal) | 67.2 | 59.6 | 31.1 | 25.8 | 54.5 | 63 | 71.7 | 68.3 |
This model's scores
- Terminal Bench 2.187.9%
- Cybergym83.3%
- Toolathlon-Verified74.1%
- DSBench-FullStack (internal)71.1%
- DSBench-Hard (internal)67.2%
- DeepSWE62.7%
- NL2Repo61.5%
- HLE (with tools)60%
- AutomationBench (public set)31.8%
- Agents' Last Exam25.7%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Pricing
| Input | $0.66 off-peak · $1.32 peak / 1M tokens |
|---|---|
| Cached input | $0.022 off-peak · $0.044 peak / 1M tokens |
| Output | $1.98 off-peak · $3.96 peak / 1M tokens |
Input prices are cache-miss. DeepSeek bills V4 by time of day from 16:00 UTC on 16 August 2026: peak is 01:00–04:00 and 06:00–10:00 UTC, Monday to Friday, all other hours are off-peak, and off-peak is half the peak rate. Before that change V4-Pro was a flat $0.435 cache-miss input / $0.003625 cache-hit input / $0.87 output per 1M tokens.
Strengths
- Open MIT-licensed weights at frontier scale (1.6T parameters), free for commercial use and local deployment
- 87.9 on Terminal Bench 2.1 and 62.7 on DeepSWE in DeepSeek's GA comparison — far above the April preview (72.1 and 12.8)
- Native one-million-token context window with efficient hybrid attention
- Selectable reasoning effort (low / high / max) to trade latency for depth, with up to 384K output tokens
- DSpark speculative-decoding module attached in the 0813 release
- Aggressive cache-hit discounts, and off-peak API rates at half the peak price
Best for
- Long-document and large-codebase analysis that needs the full 1M-token window
- Agentic and coding workflows that benefit from high-effort reasoning modes
- Self-hosted / on-prem deployment where open MIT weights are a requirement
- Cost-sensitive high-volume inference via the DeepSeek API
How to access
| Provider | Model ID |
|---|---|
| DeepSeek Platform ↗ | deepseek-v4-pro |
DeepSeek V4 — every version
The full lineage of the DeepSeek V4 line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| DeepSeek V4.1 Flashcurrent | 2026-09-10 | 1M | MIT |
| DeepSeek-V4-Flash-Vision-Exp | 2026-08-21 | 1M | MIT |
| DeepSeek-V4-Pro | 2026-08-13 | 1M | MIT |
| DeepSeek-V4-Flash | 2026-07-31 | — | MIT |
DeepSeek-V4-Pro in the news
- 2026-08-19NOTABLETwo Minute Papers — 'DeepSeek Just Made Closed AI Look Ridiculous'
- 2026-08-13MAJORDeepSeek raises V4 API prices — output costs more than double from August 16
- 2026-08-12MAJORDeepSeek V4 Pro 0813 — the 1.6T flagship leaves preview
- 2026-06-26MAJORDSpark + DeepSpec — DeepSeek opens its speculative decoding stack
- 2026-05-03MAJORDeepClaude — Run Claude Code's Agent Loop on DeepSeek V4 Pro for 17x Cheaper Tokens
From the AI/TLDR release feed — every item is source-verified when it ships.
FAQ
Is DeepSeek-V4-Pro open source?
Yes. The model weights are published on Hugging Face under the MIT License, one of the most permissive open licenses — the GA checkpoint lives at deepseek-ai/DeepSeek-V4-Pro-0813. That means you can download, run, fine-tune, and use DeepSeek-V4-Pro commercially, including for self-hosted and on-premise deployment, without paying DeepSeek.
What is DeepSeek-V4-Pro-0813?
It is the general-availability release of DeepSeek-V4-Pro, published on 13 August 2026. DeepSeek describes it as superseding the April 2026 preview, with greatly enhanced agentic capabilities, built on the preview's model structure with a DSpark speculative-decoding module attached.
How big is DeepSeek-V4-Pro and how much context does it handle?
DeepSeek-V4-Pro is a Mixture-of-Experts model with 1.6 trillion total parameters, of which 49 billion are activated per token. It supports a context length of one million tokens, which DeepSeek treats as the default across its official services, making it suitable for very long documents and large codebases.
What are the reasoning modes in DeepSeek-V4-Pro?
The 0813 release exposes a `reasoning_effort` parameter with three levels — `low`, `high` and `max` — controlling how much deliberation the model spends before answering. For the `high` and `max` levels DeepSeek recommends allowing up to 384K output tokens.
How much does the DeepSeek-V4-Pro API cost?
DeepSeek bills V4-Pro by time of day. Off-peak it is $0.022 per 1M cache-hit input tokens, $0.66 per 1M cache-miss input tokens and $1.98 per 1M output tokens; at peak (01:00–04:00 and 06:00–10:00 UTC) those double to $0.044, $1.32 and $3.96. This schedule replaced a flat $0.003625 / $0.435 / $0.87 tariff at 16:00 UTC on 16 August 2026.