

Overview
DeepSeek-V4-Flash is the smaller, faster, and cheaper of the two models in DeepSeek's V4 series, released as a preview on 24 April 2026 alongside the larger DeepSeek-V4-Pro. It is a Mixture-of-Experts language model with 284 billion total parameters, of which 13 billion are activated per token, and it natively supports a one-million-token context window with up to 384K tokens of output.
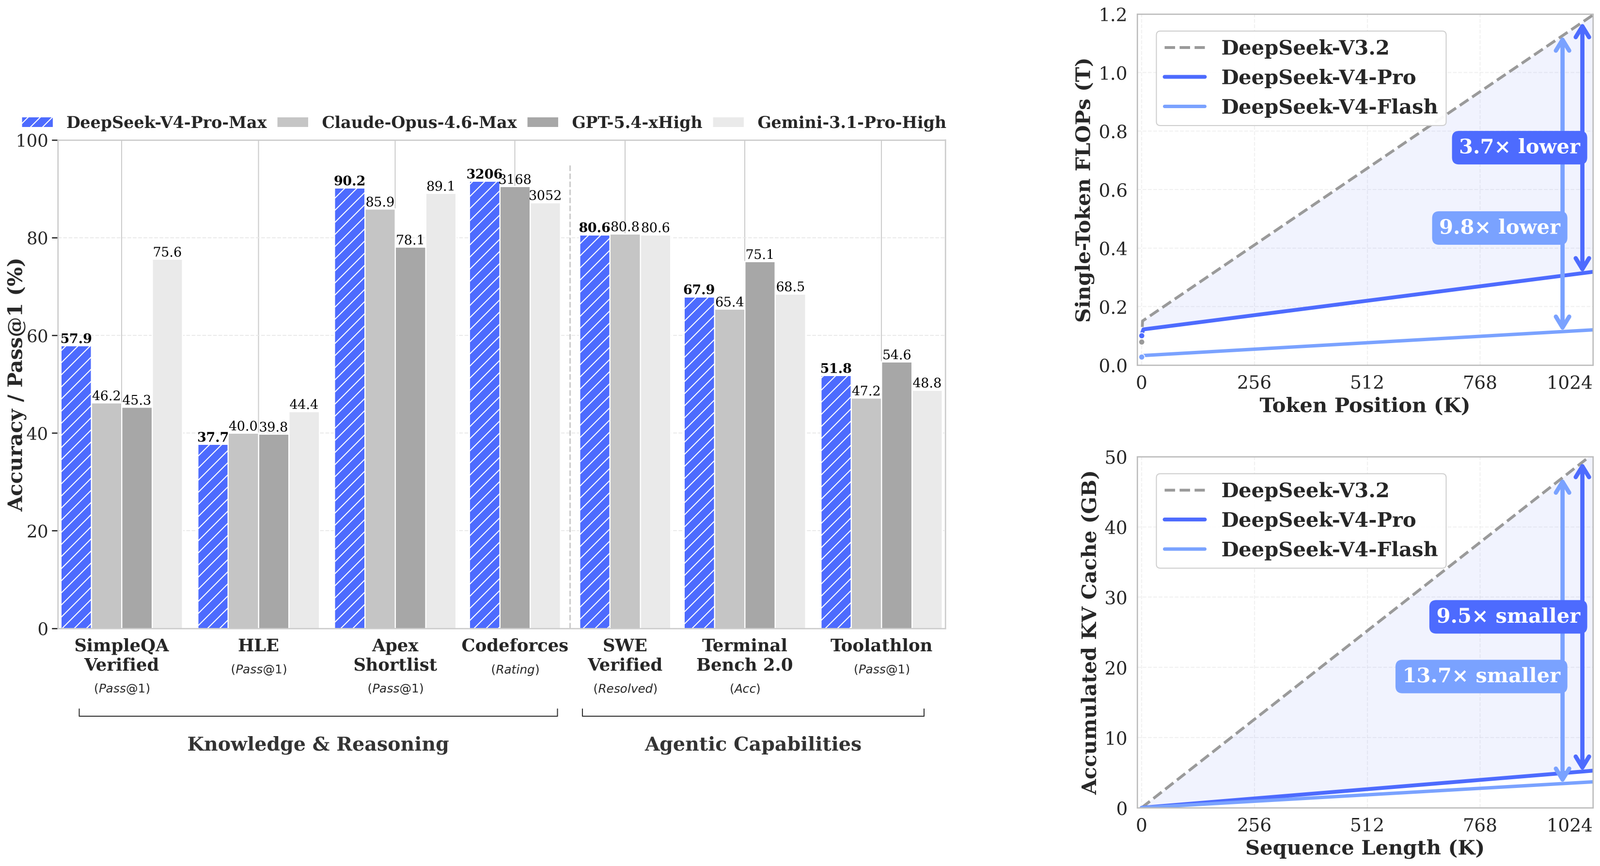
Like the Pro tier, DeepSeek-V4-Flash uses a Hybrid Attention Architecture that combines Compressed Sparse Attention and Heavily Compressed Attention. DeepSeek reports that in the 1M-token setting it needs only about 27% of the single-token inference FLOPs and 10% of the KV cache of DeepSeek-V3.2, which is what makes such a long context affordable. The model was pre-trained on more than 32 trillion tokens, runs in mixed FP4/FP8 precision (FP4 for MoE experts), and exposes three reasoning-effort modes: Non-think, Think High, and Think Max. DeepSeek says Flash in its Max mode approaches the reasoning quality of V4-Pro when given a larger thinking budget.
All weights are published on Hugging Face under the MIT License, so DeepSeek-V4-Flash is free for commercial use, fine-tuning, and self-hosting via vLLM, SGLang, or quantized GGUF builds in Ollama and LM Studio. On the DeepSeek API the legacy deepseek-chat and deepseek-reasoner aliases were retired on 2026-07-24 after having routed to Flash's non-thinking and thinking modes, and DeepSeek positions Flash as its low-cost agentic and coding workhorse, priced at a third of the V4-Pro rate.
On 2026-07-31 the `deepseek-v4-flash` API entered official public beta on a re-post-trained checkpoint DeepSeek released as DeepSeek-V4-Flash-0731. The checkpoint keeps the same architecture and parameter count as the April preview but reports substantially stronger agent scores — Terminal-Bench 2.1 82.7, DSBench-FullStack 68.7, Cybergym 76.7, Toolathlon Verified 70.3, DeepSWE 54.4, and NL2Repo 54.2, tested with the DeepSeek Harness minimal mode at max effort. The official V4-Flash natively supports the Responses API format and is specifically adapted for OpenAI Codex; DeepSeek says the official release of V4-Pro will follow.
| Released | 2026-04-24 |
|---|---|
| License | MIT |
| Weights | Open weights |
| Parameters | 284B total · 13B active |
| Context | 1M |
| Max output | 384K |
| Architecture | Mixture-of-Experts (Hybrid Attention: CSA + HCA) |
| Modalities | Text |
| Status | Retired on the DeepSeek API — DeepSeek announced on 10 September 2026 that V4-Flash is retired; the legacy `deepseek-v4-flash` name is still accepted and is served by DeepSeek-V4.1-Flash, billed at the Flash price. Before that, the re-post-trained DeepSeek-V4-Flash-0731 checkpoint had taken over the alias on 2026-07-31 as an official public beta. The MIT-licensed open weights remain on Hugging Face. |
Benchmarks
This model's scores
- MMLU-Pro (Max)86.2%
- GPQA Diamond (Max)88.1%
- HMMT 2026 Feb (Max)94.8%
- LiveCodeBench (Max)91.6%
- SWE Verified (Max)79%
- SimpleQA-Verified (Max)34.1%
- MRCR 1M (Max)78.7%
- Terminal-Bench 2.1 (V4-Flash-0731)82.7%
- NL2Repo (V4-Flash-0731)54.2%
- Cybergym (V4-Flash-0731)76.7%
- DeepSWE (V4-Flash-0731)54.4%
- Toolathlon Verified (V4-Flash-0731)70.3%
- DSBench-FullStack (V4-Flash-0731)68.7%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Pricing
| Input | $0.22 off-peak · $0.44 peak / 1M tokens |
|---|---|
| Cached input | $0.007 off-peak · $0.014 peak / 1M tokens |
| Output | $0.66 off-peak · $1.32 peak / 1M tokens |
Input prices are cache-miss. DeepSeek bills V4 by time of day from 16:00 UTC on 16 August 2026: peak is 01:00–04:00 and 06:00–10:00 UTC, Monday to Friday, all other hours are off-peak, and off-peak is half the peak rate. Before that change V4-Flash was a flat $0.14 cache-miss input / $0.0028 cache-hit input / $0.28 output per 1M tokens. These were V4-Flash's rates until its 10 September 2026 retirement; since then the legacy `deepseek-v4-flash` name is served by DeepSeek-V4.1-Flash and billed at the Flash price ($0.15–$0.30 cache-miss input, $0.003–$0.006 cache-hit input, $0.60–$1.20 output per 1M tokens, off-peak to peak).
Strengths
- Open MIT-licensed weights, free for commercial use, fine-tuning, and local deployment via vLLM, SGLang, Ollama, or LM Studio
- Native one-million-token context with efficient hybrid attention (roughly 27% of V3.2's per-token FLOPs and 10% of its KV cache at 1M)
- Selectable reasoning effort (Non-think / Think High / Think Max) to trade latency for depth
- Low API pricing — $0.22 per 1M cache-miss input tokens and $0.66 per 1M output off-peak, a third of the V4-Pro rate, with aggressive cache-hit discounts
- Strong coding and reasoning scores for its size, approaching V4-Pro in the Max mode (LiveCodeBench 91.6, SWE Verified 79.0)
Best for
- High-volume agentic and coding workflows where cost and latency matter more than absolute peak quality
- Long-document and large-codebase analysis that needs the full 1M-token window on a budget
- Self-hosted / on-prem deployment where open MIT weights and a smaller 13B-active footprint are required
- A drop-in replacement for the retiring deepseek-chat and deepseek-reasoner endpoints via its non-thinking and thinking modes
How to access
| Provider | Model ID |
|---|---|
| DeepSeek Platform ↗ | deepseek-v4-flash |
DeepSeek V4 — every version
The full lineage of the DeepSeek V4 line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| DeepSeek V4.1 Flashcurrent | 2026-09-10 | 1M | MIT |
| DeepSeek-V4-Flash-Vision-Exp | 2026-08-21 | 1M | MIT |
| DeepSeek-V4-Pro | 2026-08-13 | 1M | MIT |
| DeepSeek-V4-Flash | 2026-07-31 | — | MIT |
DeepSeek-V4-Flash in the news
- 2026-08-13MAJORDeepSeek raises V4 API prices — output costs more than double from August 16
- 2026-08-04NOTABLEDeepSeek V4-Flash on one MI300X — 168 tok/s decode, no quantization
- 2026-08-03NOTABLETwo Minute Papers — 'Another DeepSeek Moment Has Arrived'
- 2026-07-31MAJORDeepSeek V4-Flash goes official — 0731 hits 82.7 on Terminal Bench 2.1
- 2026-05-06MAJORds4 — Antirez Ships C/Metal Inference Engine for DeepSeek V4 Flash on Apple Silicon
From the AI/TLDR release feed — every item is source-verified when it ships.
FAQ
Is DeepSeek-V4-Flash open source?
Yes. The weights are published on Hugging Face under the MIT License, one of the most permissive open licenses, so you can download, run, fine-tune, and use DeepSeek-V4-Flash commercially, including self-hosted and on-prem. It can be served with vLLM or SGLang, or run from quantized GGUF builds in Ollama and LM Studio.
How is DeepSeek-V4-Flash different from DeepSeek-V4-Pro?
Both shipped on 24 April 2026 and share the same 1M-token context, hybrid attention design, and MIT license. Flash is the smaller, cheaper tier — 284B total / 13B active parameters versus Pro's 1.6T / 49B — so it responds faster and DeepSeek prices it at exactly a third of Pro's per-token rate ($0.22 vs $0.66 per 1M cache-miss input tokens off-peak). DeepSeek says Flash in its Max reasoning mode approaches Pro's quality given a larger thinking budget.
What are the reasoning modes in DeepSeek-V4-Flash?
It offers three reasoning-effort settings: Non-think for fast direct answers, Think High for deliberate step-by-step analysis, and Think Max (V4-Flash-Max) for maximum reasoning depth. The retiring deepseek-chat and deepseek-reasoner API aliases now route to Flash's non-thinking and thinking modes.
How much does the DeepSeek-V4-Flash API cost?
DeepSeek bills V4-Flash by time of day. Off-peak it is $0.22 per 1M cache-miss input tokens, $0.007 per 1M cache-hit input tokens and $0.66 per 1M output tokens; at peak (01:00–04:00 and 06:00–10:00 UTC) those double to $0.44, $0.014 and $1.32. This schedule replaced a flat $0.14 / $0.0028 / $0.28 tariff at 16:00 UTC on 16 August 2026. DeepSeek retired V4-Flash on 10 September 2026; the legacy `deepseek-v4-flash` name is still accepted but is served by DeepSeek-V4.1-Flash and billed at the Flash price.
What is DeepSeek-V4-Flash-0731?
DeepSeek-V4-Flash-0731 is a re-post-trained checkpoint of DeepSeek-V4-Flash that took over the `deepseek-v4-flash` API alias on 2026-07-31, moving the model from preview to official public beta. DeepSeek's change log notes it keeps the same architecture and parameter count as the April preview and was only re-post-trained, reporting large agent-benchmark gains — Terminal-Bench 2.1 82.7, DSBench-FullStack 68.7, Cybergym 76.7, Toolathlon Verified 70.3, DeepSWE 54.4, and NL2Repo 54.2 — plus native Responses API support and a Codex integration. The API calling method is unchanged.