Overview
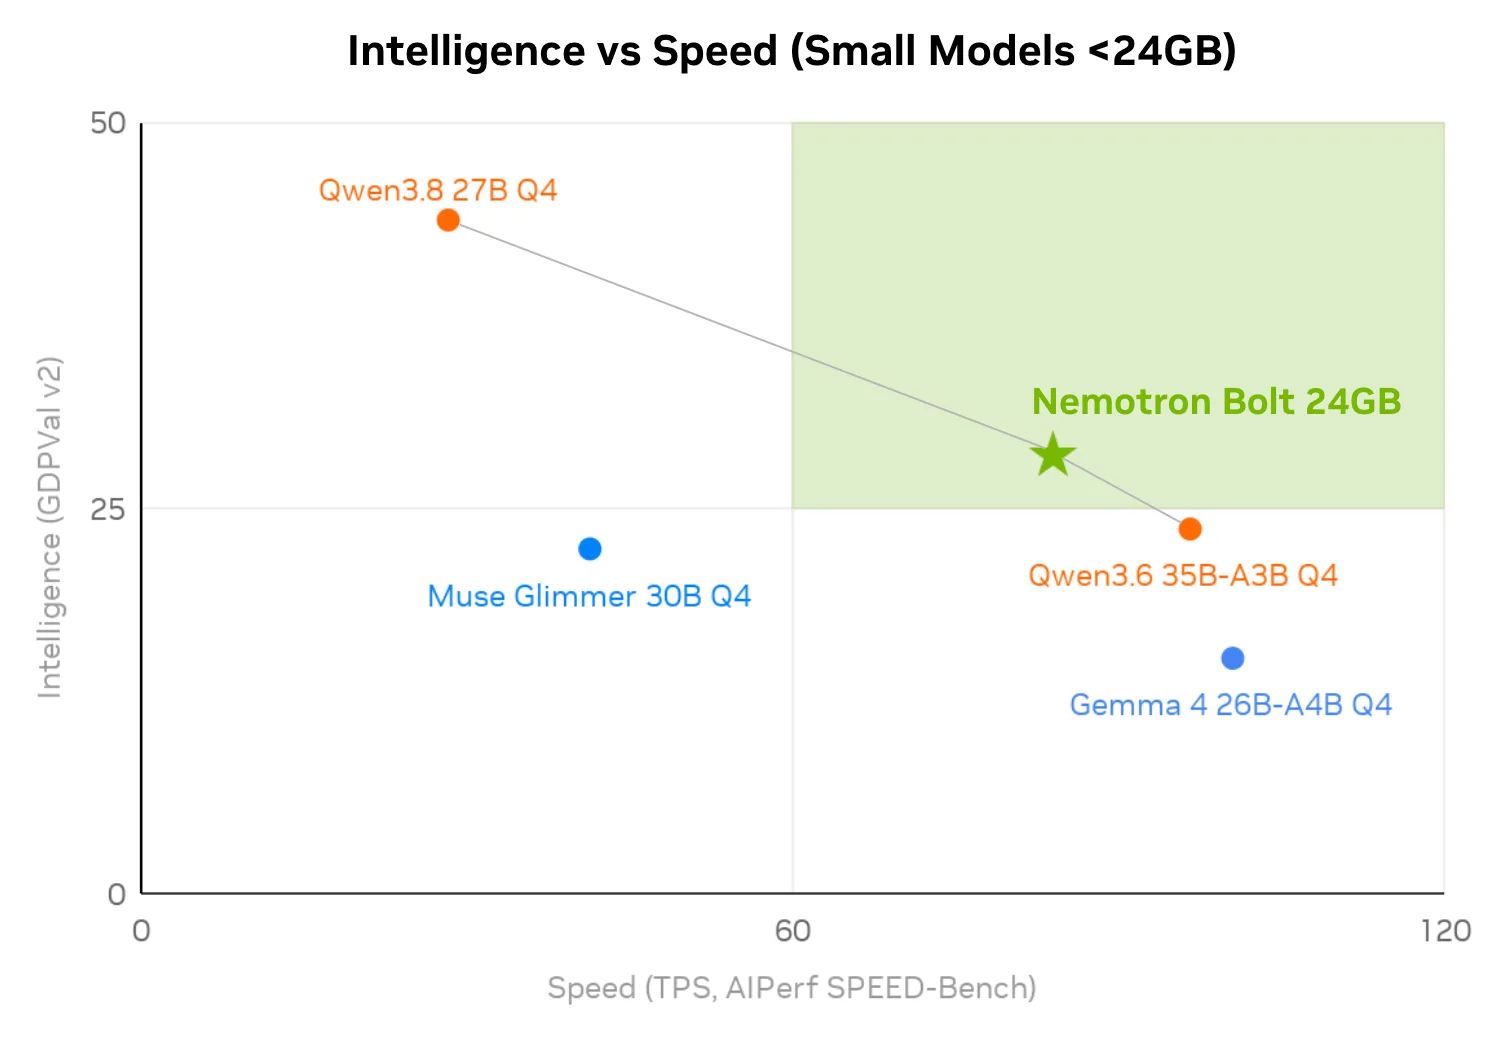
Nemotron 3.5 Bolt 74B-A9B is the local member of NVIDIA's Nemotron 3.5 generation, released on 15 October 2026 alongside the data-centre Nemotron 3.5 Super VL. NVIDIA built it to run everyday agentic tasks — multistep reasoning, tool calling and web browsing — on GeForce RTX PCs, RTX PRO workstations, DGX Spark and DGX Station, and timed it for RTX Spark laptops arriving the following day. The design goal is stated as a budget: fit in 24GB of memory and decode at 80 or more tokens per second.
Bolt starts from Super VL rather than being trained from scratch. NVIDIA's Star Elastic structured compression cuts the 120B-parameter, 12B-active parent down to 74 billion total and 9 billion active parameters, with expert top-K fixed at 9 instead of 22. The flagship 24GB release then quantises the routed and shared expert weights to IQ2_XXS at about 2.06 bits per parameter, keeps the Mamba layers in NVFP4 and the embeddings, attention and output layers in Q8_0, and recovers accuracy with quantisation-aware distillation. It keeps Super VL's hybrid Mamba-2/Transformer LatentMoE backbone and C-RADIO v4-H vision encoder, so it reads images and MP4 video up to two minutes long as well as text, with a 256K-token context shared between prompt, visual inputs, history and tool results.
NVIDIA ships three checkpoints under OpenMDW-1.1: the packed 24GB model, a 24GB GGUF for llama.cpp-style runtimes, and an unquantised BF16 checkpoint intended mainly for customisation and post-training. A LiLiCorr draft model for speculative decoding is published separately; NVIDIA reports a mean acceptance length of 4.68 tokens with greedy decoding. NVIDIA names llama.cpp, Ollama, LM Studio, Unsloth and vLLM as supported runtimes. A smaller sibling, Bolt E4B 4GB, was announced in the same post for 23 October 2026.
On NVIDIA's published table the 24GB release beats Qwen3.6-35B-A3B, Gemma 4 26B-A4B and Nemotron 3.5 Lightning on most rows — GPQA Diamond 86.43, Terminal-Bench 2.1 50.98, BrowseComp 66.75 — and NVIDIA calls it the #1 open model in its class on PinchBench, where it scores 87.82 to Qwen3.6-35B-A3B's 88.07 in the table. The trade is speed: on NVIDIA's AIPerf SPEED-Bench coding run it decodes at 83.99 tokens per second against 96.63 for Qwen3.6-35B-A3B and 100.56 for Gemma 4 26B-A4B, though well ahead of the dense Qwen3.8 27B at 28.26.
| Released | 2026-10-15 |
|---|---|
| License | OpenMDW-1.1 |
| Weights | Open weights |
| Parameters | 74B total · 9B active (Mixture-of-Experts) |
| Context | 256K |
| Architecture | Hybrid Mamba-2 + Transformer LatentMoE with a C-RADIO v4-H vision encoder; compressed from Nemotron 3.5 Super VL 120B-A12B with Star Elastic |
| Knowledge cutoff | May 2026 (post-training data) |
| Modalities | Text, Image, Video |
| Status | Generally available — open weights on Hugging Face (24GB IQ2 release, GGUF and BF16 checkpoints) |
Benchmarks
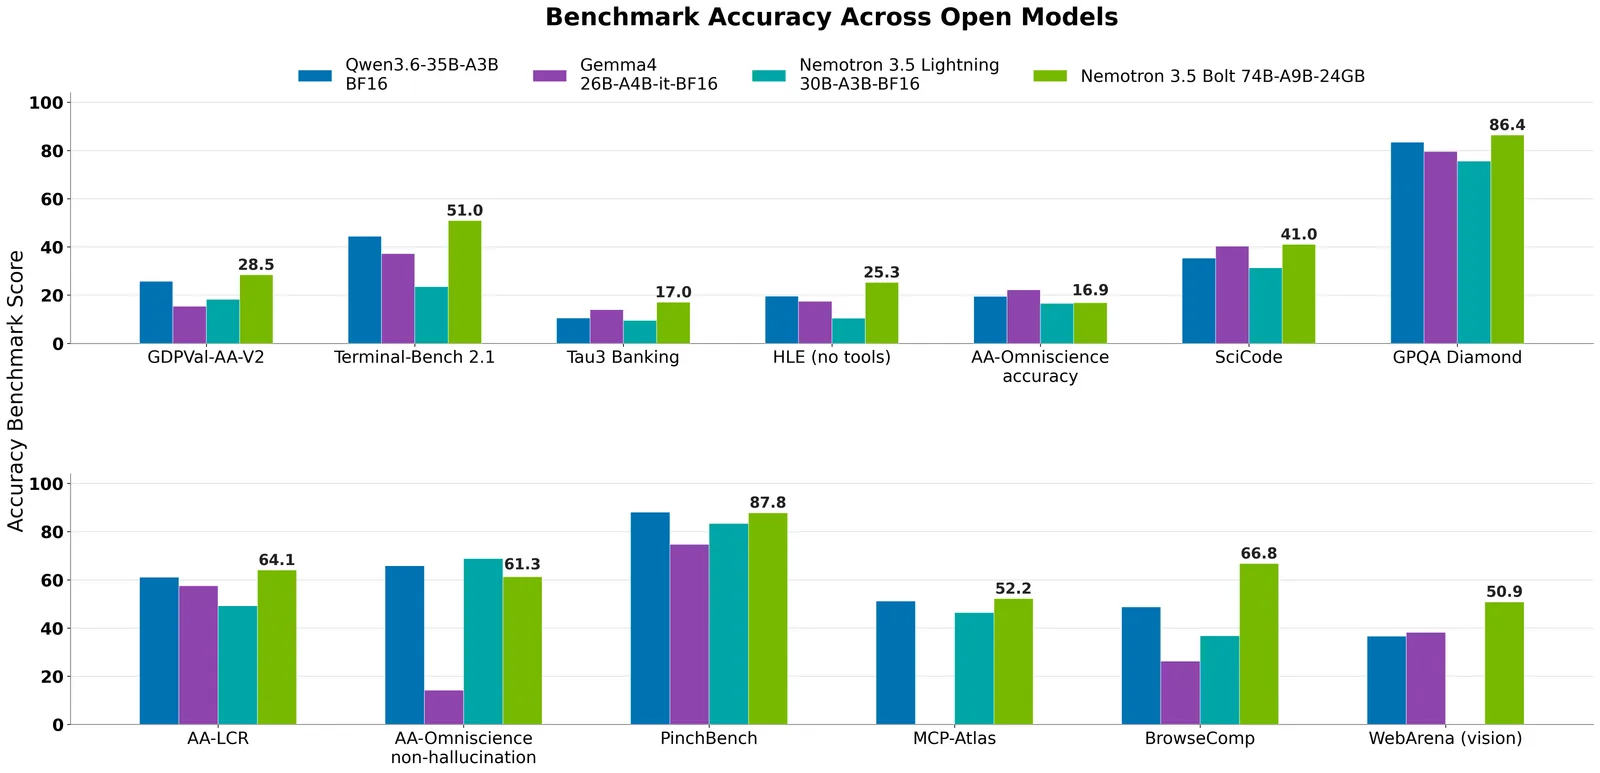
NVIDIA's published comparison from the BF16 model card (15 October 2026), with the packed 24GB (IQ2) release and the unquantised BF16 checkpoint side by side. A dash means the source left the cell blank. NVIDIA notes Qwen3.6-35B-A3B reports 62.8 on MCP-Atlas; 51.2 is NVIDIA's own run on 500 public tasks.
| Benchmark | Nemotron 3.5 Bolt 74B-A9B 24GB (IQ2) | Nemotron 3.5 Bolt 74B-A9B (BF16) | Qwen3.6-35B-A3B | Gemma 4 26B-A4B | Nemotron 3.5 Lightning 30B-A3B |
|---|---|---|---|---|---|
| Terminal-Bench 2.1 | 50.98 | 53.93 | 44.38 | 37.22 | 23.46 |
| τ³-bench (Banking) | 17.01 | 17.01 | 10.52 | 14.02 | 9.48 |
| Humanity's Last Exam (no tools) | 25.3 | 28.73 | 19.56 | 17.42 | 10.47 |
| AA-Omniscience accuracy | 16.9 | 21.8 | 19.47 | 22.17 | 16.63 |
| SciCode | 41.02 | 44.49 | 35.33 | 40.28 | 31.38 |
| GPQA Diamond | 86.43 | 88.83 | 83.4 | 79.61 | 75.57 |
| AA-LCR | 64.06 | 67.38 | 61.06 | 57.56 | 49.19 |
| AA-Omniscience non-hallucination | 61.27 | 56.14 | 65.85 | 14.22 | 68.81 |
| PinchBench | 87.82 | 90.35 | 88.07 | 74.7 | 83.43 |
| MCP-Atlas | 52.2 | 55.6 | 51.2 | — | 46.4 |
| BrowseComp | 66.75 | 70 | 48.74 | 26.3 | 36.81 |
| WebArena (vision) | 50.86 | 50.25 | 36.6 | 38.2 | — |
This model's scores
- PinchBench87.82%
- GPQA Diamond86.43%
- BrowseComp66.75%
- AA-LCR64.06%
- MCP-Atlas52.2%
- Terminal-Bench 2.150.98%
- WebArena (vision)50.86%
- SciCode41.02%
- Humanity's Last Exam (no tools)25.3%
- τ³-bench (Banking)17.01%
Scores on a 0–100 scale (25-point gridlines); higher is better. Each benchmark links to its published source.
Strengths
- A 74B-parameter Mixture-of-Experts model packed into roughly 24GB, so it fits on a single consumer RTX GPU or DGX Spark
- Vision-language input — images and up to two minutes of video — in a local model, inherited from Nemotron 3.5 Super VL
- Ahead of Qwen3.6-35B-A3B, Gemma 4 26B-A4B and Nemotron 3.5 Lightning on GPQA Diamond, Terminal-Bench 2.1, BrowseComp and WebArena in NVIDIA's table
- Permissive OpenMDW-1.1 license with 24GB, GGUF and BF16 checkpoints plus a LiLiCorr speculative-decoding drafter
- 256K-token context window for long agent sessions on local hardware
Best for
- Local computer-use and browsing agents on RTX laptops and desktops where data should not leave the machine
- Offline coding and terminal agents on DGX Spark or an RTX PRO workstation
- Running a capable multimodal model alongside other applications within a 24GB memory budget
- Fine-tuning and post-training from the BF16 checkpoint before re-quantising for local deployment
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (weights) ↗ | nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB |
| Hugging Face (GGUF) ↗ | nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF |
Nemotron (open-weight) — every version
The full lineage of the Nemotron (open-weight) line, newest first. Every version has its own page — click any to compare specs, benchmarks and pricing.
| Version | Released | Context | License |
|---|---|---|---|
| Nemotron 3.5 Super VLcurrent | 2026-10-15 | 1M | OpenMDW-1.1 |
| Nemotron 3.5 Bolt 74B-A9B | 2026-10-15 | 256K | OpenMDW-1.1 |
| Nemotron 3.5 Lightning | 2026-08-11 | 1M | OpenMDW-1.1 |
FAQ
What does "24GB" mean in the name?
The packed model fits in about 24GB of memory. NVIDIA quantises the routed and shared expert weights to IQ2_XXS at about 2.06 bits per parameter, keeps the Mamba layers in NVFP4 and the embedding, attention and output layers in Q8_0, and uses quantisation-aware distillation to recover accuracy.
What hardware does it run on?
NVIDIA targets GeForce RTX PCs, RTX PRO workstations, DGX Spark and DGX Station, and timed the release for RTX Spark laptops arriving on 16 October 2026. Supported runtimes include llama.cpp, Ollama, LM Studio, Unsloth and vLLM.
How is it related to Nemotron 3.5 Super VL?
Bolt is compressed from Super VL 120B-A12B with NVIDIA's Star Elastic method, reducing it to 74B total and 9B active parameters with expert top-K cut from 22 to 9. It keeps the parent's hybrid Mamba-2/Transformer backbone and vision encoder.
Is it faster than Qwen3.6-35B-A3B?
Not on NVIDIA's own speed test: it decodes at 83.99 tokens per second on AIPerf SPEED-Bench coding against 96.63 for Qwen3.6-35B-A3B and 100.56 for Gemma 4 26B-A4B. It scores higher than both on most accuracy rows in NVIDIA's table, and is about three times faster than the dense Qwen3.8 27B (28.26).
Which checkpoint should I download?
The 24GB release (or its GGUF) for local inference, and the BF16 checkpoint for customisation and post-training — the BF16 model card says it is intended primarily for that rather than for direct production inference.