Overview
Nemotron 3.5 Transcribe is an open-weight speech model that NVIDIA released on 28 October 2026. One checkpoint does transcription in 40 languages, translation for 31 languages to or from English, speaker attribution in 13 languages, and question answering over audio (trained in English). It accepts recordings up to one hour long with up to eight labeled speakers. It is built for recorded audio, not live streaming.
The model is promptable: instead of fixed settings, you tell it in plain language what output you want. NVIDIA's examples include "Transcribe this recording and label each speaker", "Translate this audio into English", a list of likely domain terms such as drug names, and "Transcribe without disfluencies" for a clean rather than verbatim transcript. In NVIDIA's Eka Care case study on Indian medical speech, a better prompt alone cut word error rate from 30.8% to 23.8%, and fine-tuning with NeMo Speech brought it to 11.8%.
Under the hood, a Transformer speech encoder and a speaker encoder feed a hybrid Mamba-2–Transformer Mixture-of-Experts language model built on Nemotron 3.5 Lightning. The model has 34B parameters in total and about 4.3B active per token. NVIDIA ships BF16 reference weights plus FP8 and NVFP4 variants and serves it through vLLM with a NeMo Speech plugin and an OpenAI-compatible chat endpoint. It runs on a single GPU, from Jetson AGX Thor and DGX Spark to Blackwell data-center cards.
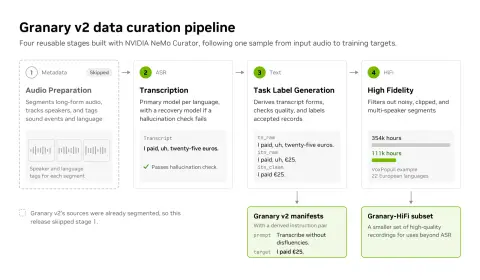
NVIDIA released it together with Granary v2, an open speech dataset of 463,062 hours across 48 languages, built with NeMo Curator. Granary v2 gives each recording three transcript styles — verbatim with spelled-out numbers, verbatim with symbols, and clean without fillers — which are the same styles you can request from the model with a prompt.
| Released | 2026-10-28 |
|---|---|
| License | OpenMDW-1.1 |
| Weights | Open weights |
| Parameters | 34B total · about 4.3B active (3.5B language model + 800M audio encoder) |
| Context | 64K |
| Architecture | Transformer ASR encoder plus speaker encoder feeding a Mamba-2–Transformer hybrid Mixture-of-Experts language model built on Nemotron 3.5 Lightning 30B-A3B |
| Modalities | Audio, Text |
| Status | Generally available — open weights on Hugging Face (BF16, FP8 and NVFP4 variants) and ModelScope, released October 28, 2026 |
Benchmarks
Strengths
- First among open-weight models on the Hugging Face Open ASR English leaderboard, at 5.33% average WER
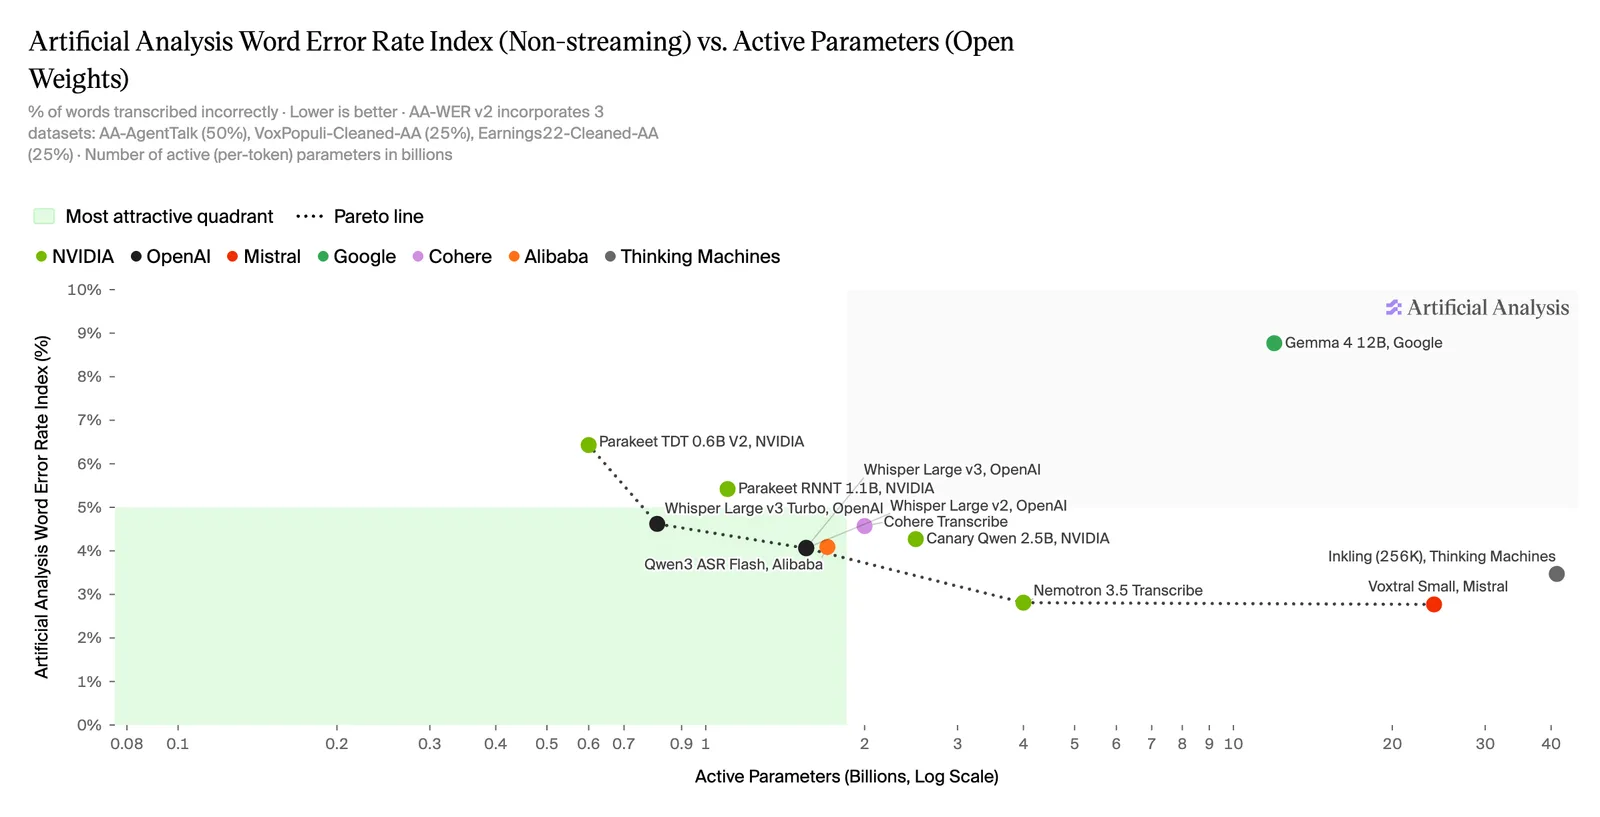
- 2.8% AA-WER on Artificial Analysis, tied for first among open-weight models with about 4B active parameters
- Lowest diarization error of 14 systems on David AI's 21-language DAI-ASR-I18N test (18.26% DER)
- One model for transcription, translation, speaker labels and audio Q&A, steered by natural-language prompts
- OpenMDW-1.1 license with BF16, FP8 and NVFP4 checkpoints that run on one GPU
Best for
- Meeting and interview transcripts that need to show who said what, for recordings up to an hour
- Medical or legal transcription where a prompt with likely terms, or a short fine-tune, fixes domain words
- Translating recorded audio in 31 languages into English text, or English audio into those languages
- Building a custom speech model on your own data with the NeMo Speech recipes and Granary v2
How to access
| Provider | Model ID |
|---|---|
| Hugging Face (open weights) ↗ | nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B |
FAQ
Can Nemotron 3.5 Transcribe caption live audio?
No. NVIDIA built Nemotron 3.5 Transcribe for recorded audio, not live streaming. It takes recordings up to one hour long as 16 kHz single-channel audio in WAV, FLAC, MP3 or OGG and returns text with optional word timestamps.
What hardware does Nemotron 3.5 Transcribe need?
The model card lists one H100 80 GB as the reference deployment, and NVIDIA says the model runs on a single GPU from Jetson AGX Thor and DGX Spark up to Blackwell data-center cards. On one RTX PRO 6000 Blackwell Server Edition with NVFP4, NVIDIA reports about 100 hours of audio processed in under three minutes.
Can I fine-tune Nemotron 3.5 Transcribe on my own vocabulary?
Yes. NVIDIA's NeMo Speech recipes train the speech encoder and projection layer and adapt the language model with LoRA. In NVIDIA's medical case study the full adaptation took about 14 GPU-hours on one GB300 and cut word error rate on held-out speakers from 22.44% to 12.17%.