Overview
ort is a Rust interface for running hardware-accelerated inference and training on machine learning models in the Open Neural Network Exchange (ONNX) format. It is primarily a wrapper around Microsoft's ONNX Runtime, the C++ inference engine, and started life as a continuation of the now-inactive onnxruntime-rs crate. The project is maintained by pyke and published on crates.io as ort, dual-licensed MIT or Apache-2.0.
The workflow starts outside Rust: your framework of choice (PyTorch, TensorFlow, Keras, scikit-learn, PaddlePaddle) exports the model to an ONNX graph built from basic operations such as MatMul, Conv or Add. ort loads that graph into a session and runs it through ONNX Runtime, which applies graph optimizations and can hand work to execution providers for NVIDIA CUDA and TensorRT, Intel OpenVINO, Qualcomm QNN, Apple CoreML, DirectML and other accelerators.
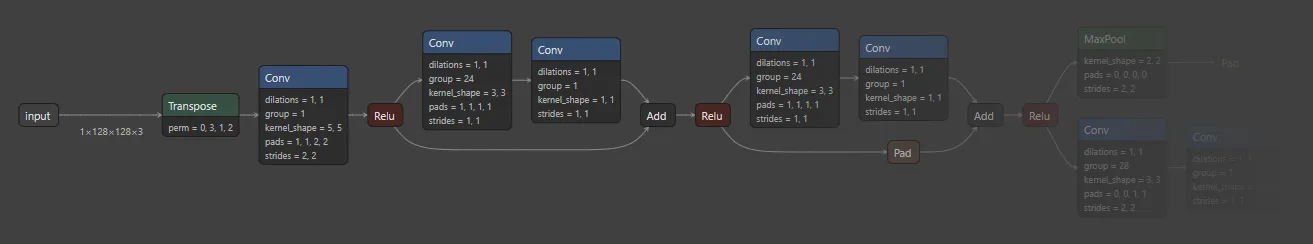
Because ONNX Runtime is C++, linking it into some targets (WebAssembly in particular) is awkward, so ort also supports alternative backends that implement the same ONNX Runtime C API on top of other engines: ort-tract (Sonos tract) and ort-candle (Hugging Face candle) in pure Rust, and ort-web, which runs the full ONNX Runtime in the browser. The README and docs list Hugging Face Text Embeddings Inference, Google's Magika, Wasmtime's WASI-NN implementation, SurrealDB and Supabase edge functions among its users.
What it does
- Safe, ergonomic Rust API over ONNX Runtime: build an Environment and Session, pass inputs with the inputs! macro, and extract outputs as ndarray arrays
- Execution providers enabled by Cargo feature (cuda, tensorrt, coreml, directml and more), registered in priority order with automatic fallback to the next provider or the CPU
- Prebuilt ONNX Runtime binaries downloaded from pyke's CDN by default, with load-dynamic, pkg-config and custom linking for builds from source
- Alternative backends — ort-tract, ort-candle and ort-web — selected with one set_api call when ONNX Runtime can't be linked, including WebAssembly targets
- Multiversioning: api-* Cargo features let one ort release target a range of ONNX Runtime minor versions
- Extras beyond plain inference: a training feature, IoBinding to control where inputs and outputs live, custom operators, float16/bfloat16 tensors via half, and no_std support (with alloc)
Getting started
These steps follow the Getting started section of the ort guide. You need a model exported to ONNX first; the guide points to Hugging Face Optimum, torch.onnx, sklearn-onnx, tf2onnx and Paddle2ONNX for the conversion.
Add ort to Cargo.toml
On a supported platform the default download-binaries feature fetches a prebuilt ONNX Runtime for you, so this is the only setup. The guide pins the release-candidate version exactly.
[dependencies]
ort = "=2.0.0-rc.13"
Load your model
Create an environment, then build a session with graph optimizations and a thread count and commit it from the .onnx file.
use ort::session::{builder::GraphOptimizationLevel, Session};

let env = ort::init().build()?;
let mut model = Session::builder(&env)?
    .with_optimization_level(GraphOptimizationLevel::Level3)?
    .with_intra_threads(4)?
    .commit_from_file("yolov8m.onnx")?;
Run inference
Pass named inputs to run() and extract the output tensor you need.
let outputs = model.run(ort::inputs!["image" => image])?;
let predictions = outputs["output0"].try_extract_array::<f32>()?;
Turn on GPU acceleration
Enable the execution provider's Cargo feature (for example features = ["cuda"]) and register it on the session builder. If it fails to register, ort falls back to the CPU unless you add .error_on_failure().
use ort::{ep, session::Session};

fn main() -> anyhow::Result<()> {
    let env = ort::init().build()?;
    let session = Session::builder(&env)?
        .with_execution_providers([
            #[cfg(feature = "cuda")]
            ep::CUDA::default().build()
        ])?
        .commit_from_file("model.onnx")?;

    Ok(())
}
Commands and code are distilled from the project's own documentation — always check the official repo for the latest.
When to use it
- Ship a PyTorch or TensorFlow model inside a Rust service or CLI without a Python runtime, by exporting it to ONNX and running it through ort
- Run embedding, OCR, speech-to-text or YOLO detection models locally in a Rust desktop or mobile app, as several projects listed in the README do
- Accelerate the same model on different hardware — CUDA or TensorRT on servers, CoreML on Apple devices, DirectML on Windows — by switching execution providers
- Target WebAssembly or unusual platforms where ONNX Runtime won't link, using the ort-web, ort-tract or ort-candle backend behind the same API
Version history
Every verified update to ort that AI/TLDR tracked, newest first — each links to our coverage and the official changeset.
- 2026-07-28v2.0.0-rc.13
Moves to ONNX Runtime 1.28, gates execution-provider structs behind their Cargo features at compile time, adds lax-feature-matching, ships only CUDA 13 binaries and reworks the custom-operator API.
- 2026-03-05v2.0.0-rc.12
Adds multiversioning via api-* features (ONNX Runtime 1.17 to 1.24), automatic device selection that prefers an available NPU, CUDA 13 builds alongside CUDA 12, and build attestations.
- 2026-01-07v2.0.0-rc.11
Introduces ort-web, which runs the full ONNX Runtime on the web with WebNN and WASM execution providers, plus configurable TLS backends and static linking to iOS frameworks.
How ort compares
ort alongside other open-source local runtimes tools AI/TLDR tracks, ranked by GitHub stars.
| Tool | Stars | What it does |
|---|---|---|
| Ollama | ★ 182k | A developer-friendly tool that downloads and runs local LLMs from the terminal with a built-in OpenAI-compatible API. |
| llama.cpp | ★ 130k | A C/C++ inference engine that runs LLMs in the GGUF format on CPUs, Apple Silicon, and GPUs with low memory use. |
| GPT4All | ★ 77.4k | GPT4All is a free desktop app and Python client that runs large language models locally on your own computer, with no API calls or GPU required. |
| LocalAI | ★ 49.3k | A self-hosted server that exposes an OpenAI-compatible API for running text, vision, voice, and image models on local hardware. |
| Jan | ★ 44.7k | An open-source desktop app that runs LLMs fully offline as a ChatGPT-style assistant on your own computer. |
| Colibrì | ★ 37.7k | A pure-C inference engine that keeps a Mixture-of-Experts model's dense trunk resident in RAM and streams its routed experts from disk, so 744B-2.8T models run on consumer hardware. |
| llmfit | ★ 37.2k | A Rust terminal tool that inspects your CPU, RAM, GPUs and VRAM and scores which open-weight models and quantizations will actually run well on that machine, with a TUI, CLI, REST API and local-runtime integrations. |
| ort | ★ 2.5k | A Rust binding for ONNX Runtime that runs hardware-accelerated inference and training on ONNX models, on-device or in the datacenter |